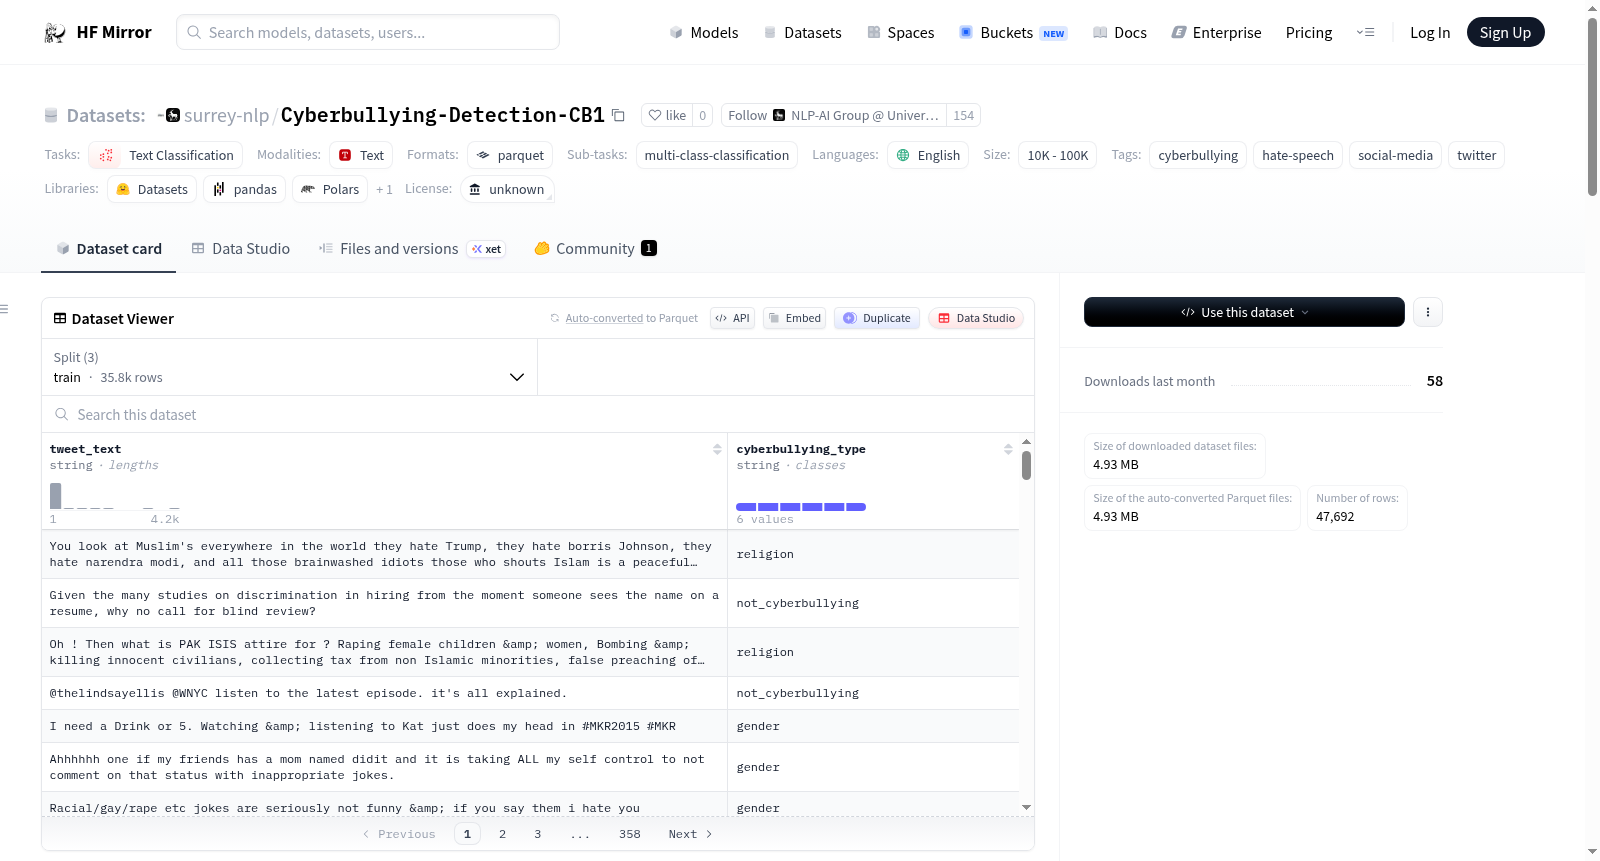
surrey-nlp/Cyberbullying-Detection-CB1
收藏资源简介:
--- language: - en license: unknown task_categories: - text-classification task_ids: - multi-class-classification tags: - cyberbullying - hate-speech - social-media - twitter pretty_name: Cyberbullying Detection CB1 size_categories: - 10K<n<100K dataset_info: features: - name: tweet_text dtype: string - name: cyberbullying_type dtype: string splits: - name: train num_bytes: 5559974 num_examples: 35769 - name: validation num_bytes: 311587 num_examples: 2000 - name: test num_bytes: 1542394 num_examples: 9923 download_size: 4930386 dataset_size: 7413955 configs: - config_name: default data_files: - split: train path: data/train-* - split: validation path: data/validation-* - split: test path: data/test-* --- # Cyberbullying Detection — CB1 ## Dataset Description **CB1** is a multi-class text classification dataset for automated cyberbullying detection on social media. Each instance is a single social media post (sourced from Twitter/X) annotated with a cyberbullying category. This dataset is part of the **Cyberbullying-Detection** collection on Hugging Face. --- ## Dataset Structure ### Data Fields | Field | Type | Description | |-------|------|-------------| | `tweet_text` | `string` | Raw social media post text | | `cyberbullying_type` | `string` | Cyberbullying category (see label list below) | ### Label Classes | Label | Description | |-------|-------------| | `not_cyberbullying` | Posts that contain no cyberbullying content. Includes general social commentary, opinions, and everyday conversation that may be critical or sarcastic but does not target individuals or groups with harmful intent. | | `gender` | Posts that target individuals based on gender identity or sexual orientation. Includes harassment related to being male, female, non-binary, gay, lesbian, or transgender, as well as misogynistic and homophobic language. | | `religion` | Posts that attack, mock, or dehumanise individuals or communities based on their religious beliefs or affiliation. Includes targeting of Christians, Muslims, Hindus, Jews, and other faith groups | | `ethnicity` | Posts that demean or attack individuals based on their race or ethnic background. Includes the use of racial slurs and derogatory language directed at racial or ethnic minorities | | `age` | Posts that bully or demean individuals based on their age. Includes harassment targeting young people (e.g. school-age bullying) as well as mockery of older individuals. | | `other_cyberbullying` | Posts that constitute cyberbullying but do not fit neatly into the above categories. Includes general online harassment, trolling, and hostile behaviour not tied to a specific protected characteristic. | --- ## Dataset Splits The dataset is split as follows: | Split | Size | Description | |-------|------|-------------| | `train` | 75% of total | Training set | | `validation` | 2,000 rows | Development / validation set (sampled from the 25% held-out portion) | | `test` | Remaining ~25% minus 2,000 | Test set | ### Split Methodology ```python from sklearn.model_selection import train_test_split # Step 1: 75% train, 25% test+dev train_df, test_dev_df = train_test_split(df, test_size=0.25, random_state=42) # Step 2: 2000 rows for dev, rest for test dev_df = test_dev_df.sample(n=2000, random_state=42) test_df = test_dev_df.drop(dev_df.index) ``` --- ## Usage ```python from datasets import load_dataset dataset = load_dataset("Washii/Cyberbullying-Detection-CB1") # Access splits train = dataset["train"] validation = dataset["validation"] test = dataset["test"] # Example print(train[0]) # {'text': '...', 'label': 'ethnicity/race'} ``` --- ## Source Data The original data is sourced from **"[Cyberbullying Detection](https://www.kaggle.com/datasets/andrewmvd/cyberbullying-classification)"** dataset in Kaggle, containing tweets annotated for cyberbullying across multiple categories. The full raw file is `CB1.csv`. --- ## Citation If you use this dataset, please cite the original source appropriately. --- ## Dataset Card Authors Uploaded and curated by [Washii](https://huggingface.co/Washii).
语言: - 英语 许可协议:未知 任务类别: - 文本分类 任务子类别: - 多类别分类 标签: - 网络欺凌 - 仇恨言论 - 社交媒体 - 推特(Twitter) 别名:网络欺凌检测CB1 样本规模区间:10K<n<100K 数据集信息: 特征: - 名称:tweet_text,数据类型:字符串 - 名称:cyberbullying_type,数据类型:字符串 划分集: - 名称:训练集,字节数:5559974,样本数:35769 - 名称:验证集,字节数:311587,样本数:2000 - 名称:测试集,字节数:1542394,样本数:9923 下载大小:4930386 数据集总大小:7413955 配置: - 配置名称:默认配置 数据文件: - 划分集:训练集,路径:data/train-* - 划分集:验证集,路径:data/validation-* - 划分集:测试集,路径:data/test-* # 网络欺凌检测——CB1 ## 数据集概述 **CB1**是一款面向社交媒体自动化网络欺凌检测的多类别文本分类数据集。每条数据样本均为单条社交媒体帖文(源自推特/X平台),并标注了对应的网络欺凌类别。 本数据集是Hugging Face平台上**Cyberbullying-Detection**数据集合集的组成部分。 --- ## 数据集结构 ### 数据字段 | 字段名 | 数据类型 | 描述 | |-------|------|-------------| | `tweet_text` | `string` | 原始社交媒体帖文文本 | | `cyberbullying_type` | `string` | 网络欺凌类别(详见下文标签列表) | ### 标签类别 | 标签 | 描述 | |-------|-------------| | `not_cyberbullying` | 未包含任何网络欺凌内容的帖文。涵盖一般性社会评论、个人观点及日常对话,此类内容可能带有批评或讽刺意味,但不存在针对个人或群体的恶意伤害行为。 | | `gender` | 基于性别身份或性取向对个体进行攻击的帖文。包括针对男性、女性、非二元性别群体、男同性恋、女同性恋或跨性别群体的骚扰行为,以及厌女症和恐同言论。 | | `religion` | 基于宗教信仰或宗教归属对个体或社群进行攻击、嘲讽或去人性化的帖文。包括针对基督徒、穆斯林、印度教徒、犹太教徒及其他信仰群体的相关行为。 | | `ethnicity` | 基于种族或族裔背景对个体进行贬低或攻击的帖文。包括使用种族蔑称和针对少数种族或族裔群体的贬损性语言。 | | `age` | 基于年龄对个体进行欺凌或贬低的帖文。包括针对青少年(例如校园欺凌)的骚扰行为,以及对年长群体的嘲讽行为。 | | `other_cyberbullying` | 属于网络欺凌范畴,但无法归入上述类别的帖文。包括未与特定受保护特征相关联的一般性网络骚扰、钓鱼式挑衅及敌对行为。 | --- ## 数据集划分 本数据集划分方式如下: | 划分集 | 规模 | 描述 | |-------|------|-------------| | `train` | 总样本的75% | 训练集 | | `validation` | 2000条数据 | 开发/验证集(从预留的25%样本中采样得到) | | `test` | 剩余约25%样本减去2000条 | 测试集 | ### 划分方法 python from sklearn.model_selection import train_test_split # 步骤1:按75%训练集、25%测试+开发集比例划分 train_df, test_dev_df = train_test_split(df, test_size=0.25, random_state=42) # 步骤2:从测试+开发集中采样2000条作为开发集,剩余作为测试集 dev_df = test_dev_df.sample(n=2000, random_state=42) test_df = test_dev_df.drop(dev_df.index) --- ## 使用方法 python from datasets import load_dataset dataset = load_dataset("Washii/Cyberbullying-Detection-CB1") # 访问各划分集 train = dataset["train"] validation = dataset["validation"] test = dataset["test"] # 示例 print(train[0]) # {'text': '...', 'label': 'ethnicity/race'} --- ## 源数据 本数据集的原始数据源自Kaggle平台上的**“网络欺凌检测”**数据集(链接:https://www.kaggle.com/datasets/andrewmvd/cyberbullying-classification),该数据集包含多类别标注的网络欺凌相关推特帖文。完整原始数据文件为`CB1.csv`。 --- ## 引用说明 若您使用本数据集,请按规范引用原始数据源。 --- ## 数据集卡片作者 本数据集卡片由[Washii](https://huggingface.co/Washii)上传并整理。