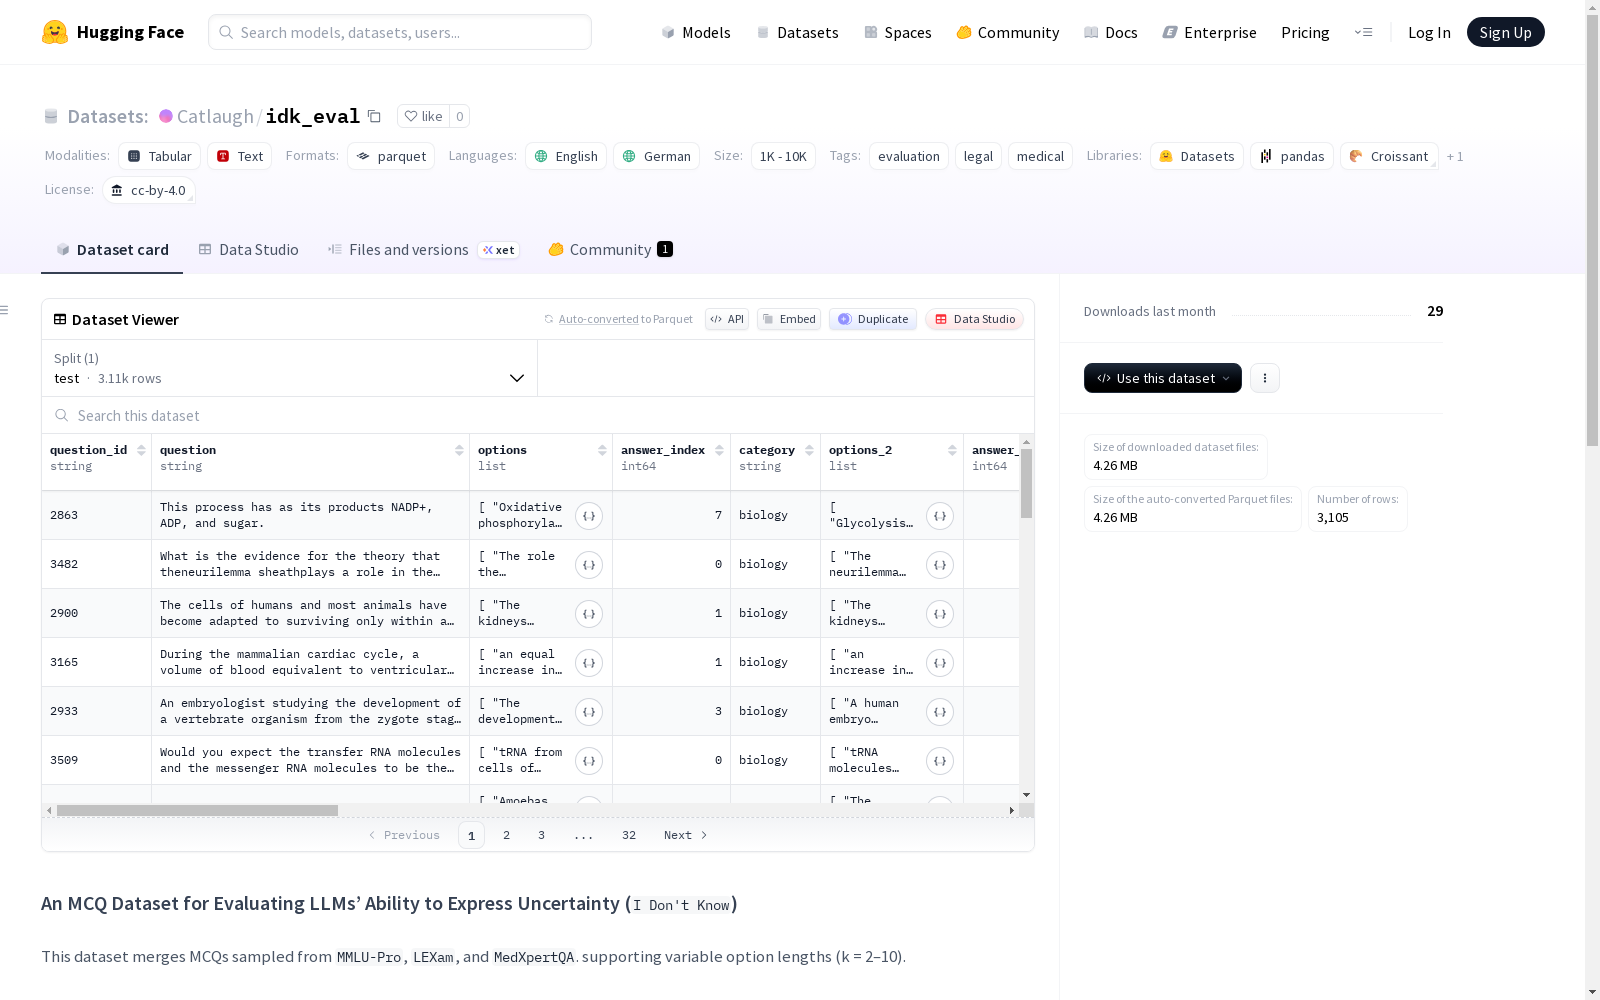
idk_eval
收藏资源简介:
这是一个用于评估大型语言模型(LLMs)表达不确定性('我不知道')能力的多项选择题(MCQ)数据集。数据集合并了来自MMLU-Pro、LEXam和MedXpertQA的MCQ样本,支持可变选项长度(k=2-10)。数据集包含不同领域的题目,如法律和医学,并分为多个类别。每个类别有特定数量的题目,并生成了不同选项长度的变体。数据集包含英语和德语,使用CC-BY-4.0许可。
This is a multiple-choice question (MCQ) dataset designed to evaluate the ability of large language models (LLMs) to express uncertainty using the phrase "I don't know". The dataset integrates MCQ samples sourced from MMLU-Pro, LEXam, and MedXpertQA, and supports variable option lengths ranging from 2 to 10 (k=2-10). It encompasses questions across diverse domains including law and medicine, and is partitioned into multiple categories. Each category contains a fixed number of questions, with variants generated for different option lengths. The dataset is available in both English and German, and is licensed under CC-BY-4.0.
数据集概述
基本信息
- 数据集名称: An MCQ Dataset for Evaluating LLMs’ Ability to Express Uncertainty (
I Dont Know) - 托管地址: https://huggingface.co/datasets/Catlaugh/idk_eval
- 许可证: CC-BY-4.0
- 语言: 英语 (en)、德语 (de)
- 标签: 评估 (evaluation)、法律 (legal)、医学 (medical)
数据集结构与内容
- 配置名称:
idk_eval - 数据划分: 仅包含
test划分 - 数据文件:
idk_eval/test-* - 样本数量: 3105 个示例
- 数据集大小: 8839719 字节
- 下载大小: 4257544 字节
特征字段
question_id: 字符串,问题IDquestion: 字符串,问题内容options: 字符串列表,选项answer_index: int64,答案索引category: 字符串,类别options_2至options_10: 字符串列表,不同选项长度的变体(k=2至10)answer_index_2至answer_index_10: int64,对应不同选项长度变体的答案索引
数据来源与构建
来源数据集
MMLU-Pro: 来自多个领域的10选项多项选择题LEXam: 来自法律的16选项多项选择题MedXpertQA: 来自医学的10选项多项选择题
构建方法
- 为
LEXam构建了4个类别:lexam_de_poslexam_de_neglexam_en_poslexam_en_neg
- 为
MedXpertQA构建了6个类别:medx_basic_science_reasoningmedx_basic_science_understandingmedx_diagnosis_reasoningmedx_diagnosis_understandingmedx_treatment_reasoningmedx_treatment_understanding
- 排除了MMLU的
other类别 - 每个类别采样115个问题
- 生成了选项长度变体 k ∈ [2, 10]
- 在数据集中,选项列命名为
options_{k},答案索引列命名为answer_index_{k}
相关资源
- 数据准备代码位于:https://huggingface.co/datasets/Catlaugh/idk_eval/blob/main/code/prepare_data.py