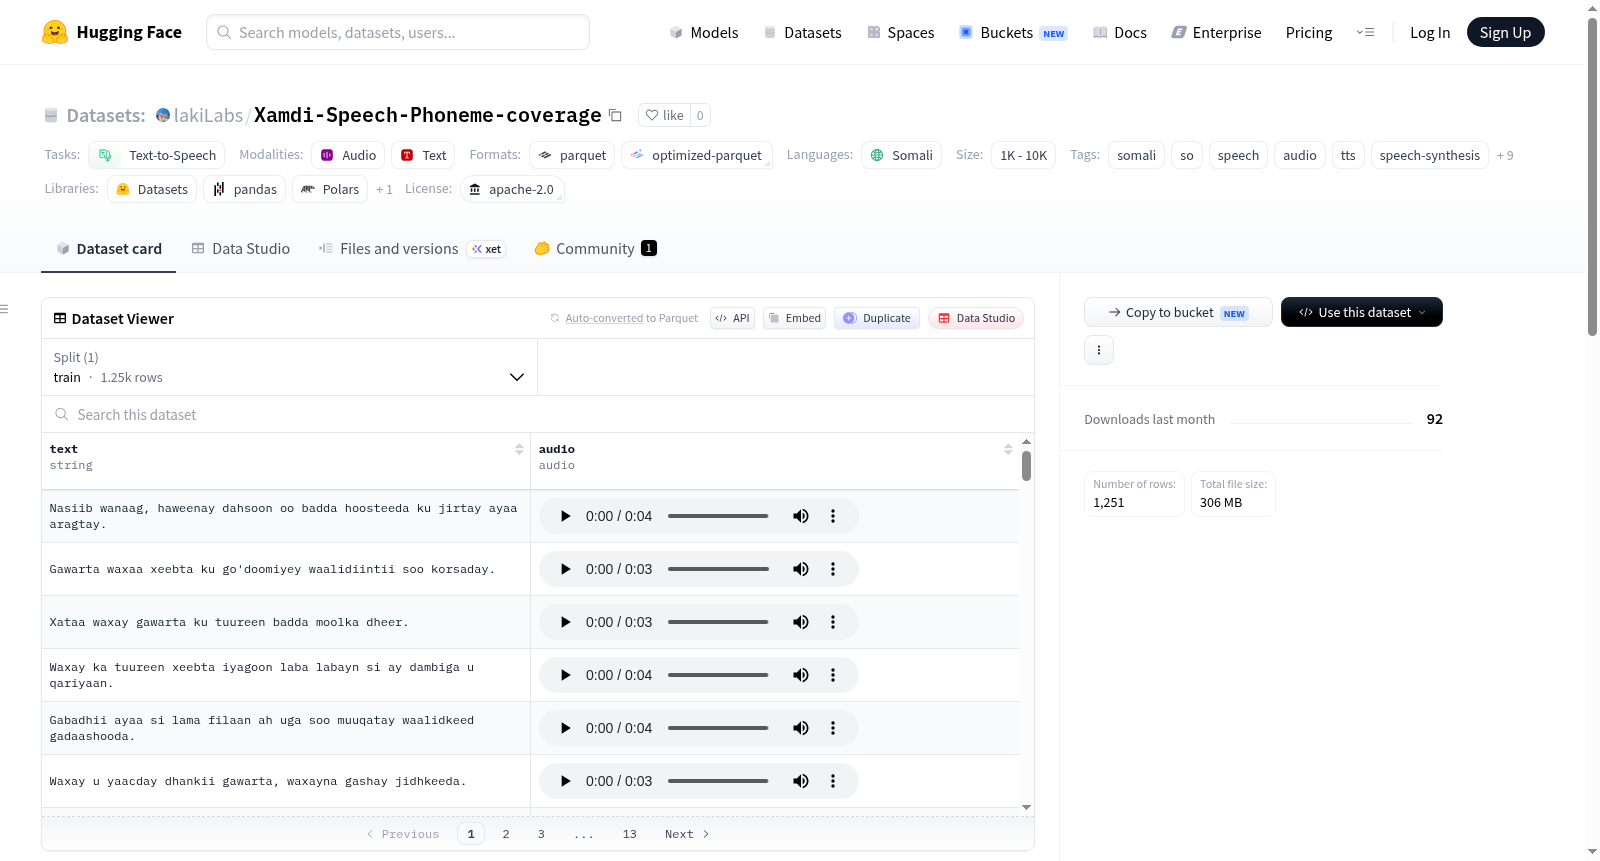
Xamdi-Speech-Phoneme-coverage
收藏资源简介:
Xamdi Speech Phoneme Coverage是一个索马里语语音数据集,专门用于自动语音识别和文本转语音模型的微调。该数据集包含1,251个配对的音频和文本样本,所有句子均唯一无重复。音频为WAV格式,采样率为24 kHz,由单一女性说话人(Xamdi)录制。其核心特点是实现了100%的音素覆盖,涵盖了除P和V之外的所有索马里语原生字母和声音(P和V不属于索马里语原生字母表)。数据集结构简单,每个样本包含audio和text两个字段。由于规模适中,该数据集主要适用于对现有STT或TTS模型进行微调或语音克隆,而非从头训练基础模型。未来版本计划引入更多说话人朗读相同文本语料,以支持不同声音之间的公平比较。
Xamdi Speech Phoneme Coverage is a Somali language speech dataset specifically designed for fine-tuning automatic speech recognition (ASR) and text-to-speech (TTS) models. This dataset contains 1,251 paired audio and text samples, with all sentences being unique and non-repetitive. The audio is in WAV format with a sampling rate of 24 kHz, recorded by a single female speaker named Xamdi. Its core feature is achieving 100% phoneme coverage, covering all native Somali letters and sounds except for P and V, as P and V are not part of the native Somali alphabet. The dataset has a simple structure, with each sample containing two fields: audio and text. Due to its moderate scale, this dataset is primarily suitable for fine-tuning existing STT or TTS models and voice cloning, rather than training base models from scratch. Future versions plan to introduce more speakers reading the same text corpus to support fair comparisons between different voices.
数据集概述
数据集名称: Xamdi Speech Phoneme Coverage
语言: 索马里语 (so)
许可证: Apache-2.0
任务类别: 文本转语音 (TTS)
数据集大小: 1,251 个样本 (1k<n<10k)
下载大小: 305,923,944 字节
数据集大小: 289,499,349 字节
数据构成
- 音频格式: WAV,采样率 24 kHz
- 说话人: 单一女性声音(Xamdi)
- 音素覆盖: 100%,涵盖所有原生索马里字母和发音(不含非原生字母 P 和 V)
- 句子独特性: 每条语句唯一,无重复句子
数据特征
每个样本包含两个字段:
- audio: 音频数据
- text: 对应文本字符串
数据拆分
- 训练集: 1,251 个样本,289,499,349 字节
用途说明
- 推荐用途: 用于微调现有的文本转语音 (TTS) 模型
- 不适用于: 从头训练基础模型,因其规模专为微调设计
未来版本
未来版本将增加其他说话人,朗读完全相同的文本语料。仅说话人不同,句子和音素覆盖保持一致,以便进行不同声音间的公平比较。