shivaniachary123/Finance-Instruct-500k
收藏资源简介:
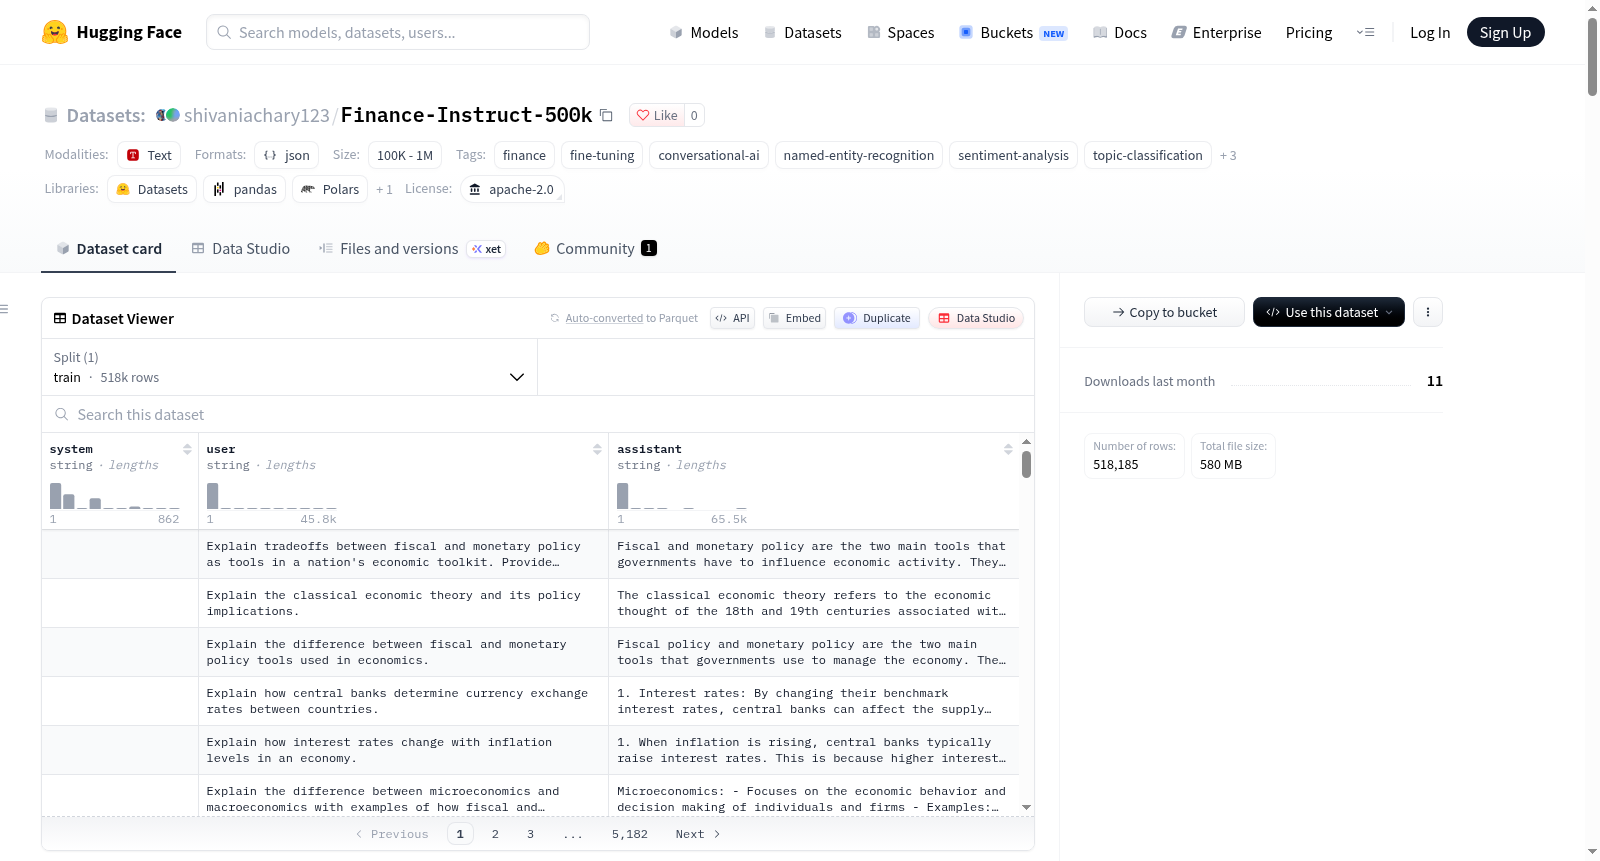
--- license: apache-2.0 tags: - finance - fine-tuning - conversational-ai - named-entity-recognition - sentiment-analysis - topic-classification - rag - multilingual - lightweight-llm --- # Finance-Instruct-500k Dataset ## Overview **Finance-Instruct-500k** is a comprehensive and meticulously curated dataset designed to train advanced language models for financial tasks, reasoning, and multi-turn conversations. Combining data from numerous high-quality financial datasets, this corpus provides over **500,000 entries**, offering unparalleled depth and versatility for finance-related instruction tuning and fine-tuning. The dataset includes content tailored for financial reasoning, question answering, entity recognition, sentiment analysis, address parsing, and multilingual natural language processing (NLP). Its diverse and deduplicated entries make it suitable for a wide range of financial AI applications, including domain-specific assistants, conversational agents, and information extraction systems. Most entries include system, user and assistant fields. Recent additions include: - **[BAAI/IndustryInstruction_Finance-Economics](https://huggingface.co/datasets/BAAI/IndustryInstruction_Finance-Economics)**: Broader financial instructions and **Chinese** language coverage. - **[Josephgflowers/Financial-NER-NLP](https://huggingface.co/datasets/Josephgflowers/Financial-NER-NLP)**: Advanced **XBRL tagging** and named-entity recognition examples.  --- ## Key Features - **Extensive Coverage**: Over 500,000 entries spanning financial QA, reasoning, sentiment analysis, topic classification, multilingual NER, and conversational AI. - **Multi-Turn Conversations**: Rich dialogues emphasizing contextual understanding and reasoning. - **Diverse Data Sources**: Includes entries from **Cinder**, **Sujet-Finance-Instruct-177k**, **Phinance Dataset**, **BAAI/IndustryInstruction_Finance-Economics**, **Josephgflowers/Financial-NER-NLP**, and many other high-quality datasets. - **RAG-Formatted Data**: Retrieval-augmented generation (RAG) tasks include external data prepended to the `user` field for enhanced contextual understanding. - **Deduplicated and Preprocessed**: Eliminates overlaps and irregular entries for cleaner and higher-quality data. - **XBRL Tagging**: Includes structured finance entity labeling from **Financial-NER-NLP** for advanced extraction tasks. --- **Future Plans** 1M! Like my work? Want to see more? Custom request? Message me on discord: joseph.flowers.ra Donate here: https://buymeacoffee.com/josephgflowers --- ## Supported Tasks and Use Cases 1. **Financial Question Answering**: - Contextual and direct-answer financial QA. - Multilingual QA and financial terminology explanation. 2. **Reasoning Tasks**: - Symbolic and numeric reasoning. - Portfolio analysis and investment strategy simulation. 3. **Conversational AI**: - Multi-turn dialogues to develop finance-specific assistants and advisors. 4. **Named Entity Recognition (NER)**: - Multilingual financial entity recognition. - XBRL tagging for structured finance data (via **Financial-NER-NLP**). - Address parsing and PII handling. 5. **Sentiment Analysis**: - Text classification as bullish, bearish, neutral, positive, or negative. - Entity-level sentiment analysis. 6. **Topic Classification**: - Categorization of financial texts into topics such as market trends, risk analysis, and economic events. 7. **Lightweight LLM Training**: - Domain-specific fine-tuning for smaller models in resource-constrained environments. 8. **RAG Applications**: - Seamless integration with external data using prepended context in the `user` field. --- ## Dataset Composition The dataset is a deduplicated combination of the following sources filtered for finance-related entries or tasks: 1. **[alvanlii/finance-textbooks](https://huggingface.co/datasets/alvanlii/finance-textbooks)** 2. **[glaiveai/RAG-v1](https://huggingface.co/datasets/glaiveai/RAG-v1)** 3. **[instruction-pretrain/ft-instruction-synthesizer-collection](https://huggingface.co/datasets/instruction-pretrain/ft-instruction-synthesizer-collection)** (NewsQA, ConvFinQA, WikiTableQA) 4. **[gretelai/gretel-pii-masking-en-v1](https://huggingface.co/datasets/gretelai/gretel-pii-masking-en-v1)** 5. **[CohereForAI/aya_dataset (HotpotQA)](https://huggingface.co/datasets/CohereForAI/aya_dataset)** 6. **[CohereForAI/aya_dataset](https://huggingface.co/datasets/CohereForAI/aya_dataset)** 7. **[nvidia/OpenMathInstruct-1](https://huggingface.co/datasets/Nvidia-OpenMathInstruct)** 8. **[TIGER-Lab/WebInstructSub](https://huggingface.co/datasets/TIGER-Lab/WebInstructSub)** 9. **[glaiveai/glaive-code-assistant-v3](https://huggingface.co/datasets/glaiveai/glaive-code-assistant-v3)** 10. **[Open-Orca/1million-gpt-4](https://huggingface.co/datasets/Open-Orca/1million-gpt-4)** 11. **[Norquinal/claude_evol_instruct_210k](https://huggingface.co/datasets/Norquinal/claude_evol_instruct_210k)** 12. **[migtissera/Synthia-v1.3](https://huggingface.co/datasets/migtissera/Synthia-v1.3)** 13. **[meta-math/MetaMathQA](https://huggingface.co/datasets/meta-math/MetaMathQA)** 14. **[HuggingFaceTB/cosmopedia](https://huggingface.co/datasets/HuggingFaceTB/cosmopedia)** 15. **[Josephgflowers/PII-NER](https://huggingface.co/datasets/Josephgflowers/PII-NER)** 16. **[gbharti/finance-alpaca](https://huggingface.co/datasets/gbharti/finance-alpaca)** 17. **[ugursa/Yahoo-Finance-News-Sentences](https://huggingface.co/datasets/ugursa/Yahoo-Finance-News-Sentences)** 18. **[AdaptLLM/finance-tasks_Headline](https://huggingface.co/datasets/AdaptLLM/finance-tasks_Headline)** 19. **[ceadar-ie/FinTalk-19k](https://huggingface.co/datasets/ceadar-ie/FinTalk-19k)** 20. **[zeroshot/twitter-financial-news-topic](https://huggingface.co/datasets/zeroshot/twitter-financial-news-topic)** 21. **[dylanalloy/ehc-contrived-financial](https://huggingface.co/datasets/dylanalloy/ehc-contrived-financial)** 22. **[zeroshot/twitter-financial-news-sentiment](https://huggingface.co/datasets/zeroshot/twitter-financial-news-sentiment)** 23. **[financial_phrasebank](https://huggingface.co/datasets/financial_phrasebank)** 24. **[AdiOO7/llama-2-finance](https://huggingface.co/datasets/AdiOO7/llama-2-finance)** 25. **[amphora/lmsys-finance](https://huggingface.co/datasets/amphora/lmsys-finance)** 26. **[AdaptLLM/finance-tasks_ConvFinQA](https://huggingface.co/datasets/AdaptLLM/finance-tasks_ConvFinQA)** 27. **[KennNguyenDev/FiQA_Financial_Phrasebank_Combined](https://huggingface.co/datasets/KennNguyenDev/FiQA_Financial_Phrasebank_Combined)** 28. **[AdaptLLM/finance-tasks_FPB](https://huggingface.co/datasets/AdaptLLM/finance-tasks_FPB)** 29. **[yixuantt/FinEntity](https://huggingface.co/datasets/yixuantt/FinEntity)** 30. **[AdaptLLM/finance-tasks_FiQA_SA](https://huggingface.co/datasets/AdaptLLM/finance-tasks_FiQA_SA)** 31. **[nickmuchi/financial-classification](https://huggingface.co/datasets/nickmuchi/financial-classification)** 32. **[lighthouzai/finqabench](https://huggingface.co/datasets/lighthouzai/finqabench)** 33. **[adityamavle/FinRiskAnalysis](https://huggingface.co/datasets/adityamavle/FinRiskAnalysis)** 34. **[sujet-ai/Sujet-Finance-Instruct-177k](https://huggingface.co/datasets/sujet-ai/Sujet-Finance-Instruct-177k)** 35. **Cinder (custom multi-turn reasoning and parsing data)** 36. **[BAAI/IndustryInstruction_Finance-Economics](https://huggingface.co/datasets/BAAI/IndustryInstruction_Finance-Economics)** 37. **[Josephgflowers/Financial-NER-NLP](https://huggingface.co/datasets/Josephgflowers/Financial-NER-NLP)** --- ## Dataset Structure ### Data Fields - **system**: Instruction or system message providing context. - **user**: Query or input from the user, with RAG data prepended if applicable. - **assistant**: Model-generated response or ground truth answer. ### Format All entries are structured as: - `system`, `user`, `assistant` ### Example Entry ```json { "system": "You are a financial assistant. Answer the user's question accurately but keep it brief.", "user": "What is the difference between stocks and bonds?", "assistant": "Stocks represent ownership in a company, while bonds are a form of debt where the investor lends money to an entity." } ``` --- ## Languages - **English**: Primary language of the dataset. - **Chinese**: Increased coverage thanks to the **BAAI/IndustryInstruction_Finance-Economics** subset. - **Other Multilingual Data**: Includes content from multilingual NER sources and the Aya datasets. --- ## Collection and Preprocessing 1. **Deduplication**: Removed over 60,000 duplicate entries across all source datasets. 2. **Data Cleaning**: Eliminated non-ASCII characters, fixed punctuation and spelling, and ensured consistent formatting. 3. **Dataset Merging**: Unified entries from various sources into a single cohesive dataset. # Lost in the dedupe. Future releases will restore Annotations. 4. **Annotation**: Enhanced metadata for clarity and usability, including task types and system prompts. 5. **XBRL Tagging**: Integrated from **Financial-NER-NLP** subset, enabling structured labeling of financial instruments. --- ## Ethical Considerations - **User Privacy**: All PII is synthetic and anonymized to ensure compliance with privacy standards. - **Professional Use Only**: This dataset is not a substitute for certified financial guidance or professional advice. --- ## Limitations - **Bias**: Coverage may skew toward certain financial sectors or topics based on dataset distribution. - **Accuracy**: Outputs trained on this dataset require validation for critical financial applications. - **Multilingual Support**: Non-English entries vary in volume, though recent additions (BAAI dataset) increase Chinese content. - **Noise**: I am aware of some non financial data, malformed system user assistant portions, and some unstructured data. Some of the datasets I filtered and used were rag generated without the associated documents. Some were more geared for pre training it looks like (cosmo). Overall the dataset performs well.  --- ## Citation If you use this dataset, please cite: ```bibtex @dataset{josephgflowers2025financeinstruct, title={Finance-Instruct-500k}, author={Joseph G. Flowers}, year={2025}, url={https://huggingface.co/datasets/Josephgflowers/Finance-Instruct-500k} } ``` --- ## How to Load the Dataset ```python from datasets import load_dataset dataset = load_dataset("Josephgflowers/Finance-Instruct-500k") print(dataset["train"][0]) ``` --- ## License This dataset is released under the Apache 2.0 license.
--- 许可证: Apache-2.0 标签: - 金融 - 微调 - 对话式AI - 命名实体识别(Named-Entity-Recognition) - 情感分析 - 主题分类 - 检索增强生成(Retrieval-Augmented Generation, RAG) - 多语言 - 轻量级大语言模型(LLM/Large Language Model) --- # Finance-Instruct-500k 数据集 ## 概述 **Finance-Instruct-500k** 是一款经过精心整理的综合性数据集,专为金融任务、语言推理与多轮对话场景训练先进语言模型而设计。本语料整合了多份高质量金融数据集的内容,总计包含超过**50万条数据条目**,可为金融相关的指令微调与模型微调提供极具深度与通用性的训练资源。 本数据集涵盖面向金融推理、问答、实体识别、情感分析、地址解析以及多语言自然语言处理(NLP)的定制化内容。其多样化且已去重的数据条目,可广泛适配各类金融人工智能应用,包括领域专属助手、AI智能体(AI Agent)与信息抽取系统。 多数数据条目包含系统提示、用户查询与助手回复三个字段。 近期新增内容包括: - **[BAAI/IndustryInstruction_Finance-Economics](https://huggingface.co/datasets/BAAI/IndustryInstruction_Finance-Economics)**:覆盖更广泛的金融指令场景,新增**中文**语言支持。 - **[Josephgflowers/Financial-NER-NLP](https://huggingface.co/datasets/Josephgflowers/Financial-NER-NLP)**:提供进阶**XBRL**标记与命名实体识别示例。  --- ## 核心特性 - **覆盖范围全面**:超50万条数据,涵盖金融问答、语言推理、情感分析、主题分类、多语言命名实体识别与对话式AI等场景。 - **多轮对话支持**:包含丰富的对话数据,强调上下文理解与逻辑推理能力。 - **多样化数据源**:整合了**Cinder**、**Sujet-Finance-Instruct-177k**、**Phinance 数据集**、**BAAI/IndustryInstruction_Finance-Economics**、**Josephgflowers/Financial-NER-NLP** 等众多高质量金融数据集。 - **RAG格式数据**:检索增强生成任务将外部参考数据前置至`user`字段,以强化模型的上下文理解能力。 - **去重与预处理**:剔除重复条目与异常数据,确保数据集干净且高质量。 - **XBRL标记支持**:整合自**Financial-NER-NLP**子集,可为进阶信息抽取任务提供结构化金融实体标注能力。 --- **未来规划**:目标扩容至100万条数据!如果您认可我的工作,希望获取更多内容或提出定制需求,请通过Discord联系我:joseph.flowers.ra。捐赠通道:https://buymeacoffee.com/josephgflowers --- ## 支持的任务与应用场景 1. **金融问答**: - 上下文关联型与直接答案式金融问答。 - 多语言金融问答与专业术语解释。 2. **推理任务**: - 符号与数值逻辑推理。 - 投资组合分析与投资策略模拟。 3. **对话式AI**: - 多轮对话数据,用于开发专属金融助手与投资顾问。 4. **命名实体识别**: - 多语言金融实体识别。 - 面向结构化金融数据的XBRL标记(通过**Financial-NER-NLP**子集实现)。 - 地址解析与个人可识别信息(Personally Identifiable Information, PII)处理。 5. **情感分析**: - 将文本分类为看涨、看跌、中性、正面或负面情绪。 - 实体级情感分析。 6. **主题分类**: - 将金融文本归类至市场趋势、风险分析、经济事件等细分主题。 7. **轻量级大语言模型训练**: - 为资源受限环境下的小型模型开展领域专属微调。 8. **RAG应用**: - 通过将上下文参考数据前置至`user`字段,实现与外部数据源的无缝集成。 --- ## 数据集构成 本数据集为经金融相关条目或任务筛选后的多源数据去重整合结果,包含以下来源: 1. **[alvanlii/finance-textbooks](https://huggingface.co/datasets/alvanlii/finance-textbooks)** 2. **[glaiveai/RAG-v1](https://huggingface.co/datasets/glaiveai/RAG-v1)** 3. **[instruction-pretrain/ft-instruction-synthesizer-collection](https://huggingface.co/datasets/instruction-pretrain/ft-instruction-synthesizer-collection)**(涵盖NewsQA、ConvFinQA、WikiTableQA) 4. **[gretelai/gretel-pii-masking-en-v1](https://huggingface.co/datasets/gretelai/gretel-pii-masking-en-v1)** 5. **[CohereForAI/aya_dataset (HotpotQA)](https://huggingface.co/datasets/CohereForAI/aya_dataset)** 6. **[CohereForAI/aya_dataset](https://huggingface.co/datasets/CohereForAI/aya_dataset)** 7. **[nvidia/OpenMathInstruct-1](https://huggingface.co/datasets/Nvidia-OpenMathInstruct)** 8. **[TIGER-Lab/WebInstructSub](https://huggingface.co/datasets/TIGER-Lab/WebInstructSub)** 9. **[glaiveai/glaive-code-assistant-v3](https://huggingface.co/datasets/glaiveai/glaive-code-assistant-v3)** 10. **[Open-Orca/1million-gpt-4](https://huggingface.co/datasets/Open-Orca/1million-gpt-4)** 11. **[Norquinal/claude_evol_instruct_210k](https://huggingface.co/datasets/Norquinal/claude_evol_instruct_210k)** 12. **[migtissera/Synthia-v1.3](https://huggingface.co/datasets/migtissera/Synthia-v1.3)** 13. **[meta-math/MetaMathQA](https://huggingface.co/datasets/meta-math/MetaMathQA)** 14. **[HuggingFaceTB/cosmopedia](https://huggingface.co/datasets/HuggingFaceTB/cosmopedia)** 15. **[Josephgflowers/PII-NER](https://huggingface.co/datasets/Josephgflowers/PII-NER)** 16. **[gbharti/finance-alpaca](https://huggingface.co/datasets/gbharti/finance-alpaca)** 17. **[ugursa/Yahoo-Finance-News-Sentences](https://huggingface.co/datasets/ugursa/Yahoo-Finance-News-Sentences)** 18. **[AdaptLLM/finance-tasks_Headline](https://huggingface.co/datasets/AdaptLLM/finance-tasks_Headline)** 19. **[ceadar-ie/FinTalk-19k](https://huggingface.co/datasets/ceadar-ie/FinTalk-19k)** 20. **[zeroshot/twitter-financial-news-topic](https://huggingface.co/datasets/zeroshot/twitter-financial-news-topic)** 21. **[dylanalloy/ehc-contrived-financial](https://huggingface.co/datasets/dylanalloy/ehc-contrived-financial)** 22. **[zeroshot/twitter-financial-news-sentiment](https://huggingface.co/datasets/zeroshot/twitter-financial-news-sentiment)** 23. **[financial_phrasebank](https://huggingface.co/datasets/financial_phrasebank)** 24. **[AdiOO7/llama-2-finance](https://huggingface.co/datasets/AdiOO7/llama-2-finance)** 25. **[amphora/lmsys-finance](https://huggingface.co/datasets/amphora/lmsys-finance)** 26. **[AdaptLLM/finance-tasks_ConvFinQA](https://huggingface.co/datasets/AdaptLLM/finance-tasks_ConvFinQA)** 27. **[KennNguyenDev/FiQA_Financial_Phrasebank_Combined](https://huggingface.co/datasets/KennNguyenDev/FiQA_Financial_Phrasebank_Combined)** 28. **[AdaptLLM/finance-tasks_FPB](https://huggingface.co/datasets/AdaptLLM/finance-tasks_FPB)** 29. **[yixuantt/FinEntity](https://huggingface.co/datasets/yixuantt/FinEntity)** 30. **[AdaptLLM/finance-tasks_FiQA_SA](https://huggingface.co/datasets/AdaptLLM/finance-tasks_FiQA_SA)** 31. **[nickmuchi/financial-classification](https://huggingface.co/datasets/nickmuchi/financial-classification)** 32. **[lighthouzai/finqabench](https://huggingface.co/datasets/lighthouzai/finqabench)** 33. **[adityamavle/FinRiskAnalysis](https://huggingface.co/datasets/adityamavle/FinRiskAnalysis)** 34. **[sujet-ai/Sujet-Finance-Instruct-177k](https://huggingface.co/datasets/sujet-ai/Sujet-Finance-Instruct-177k)** 35. **Cinder(自定义多轮推理与解析数据)** 36. **[BAAI/IndustryInstruction_Finance-Economics](https://huggingface.co/datasets/BAAI/IndustryInstruction_Finance-Economics)** 37. **[Josephgflowers/Financial-NER-NLP](https://huggingface.co/datasets/Josephgflowers/Financial-NER-NLP)** --- ## 数据集结构 ### 数据字段 - **system**:提供上下文信息的指令或系统提示。 - **user**:用户的查询或输入,若适用则前置了RAG相关参考数据。 - **assistant**:模型生成的回复或标准答案。 ### 数据格式 所有数据条目均采用以下结构: - `system`、`user`、`assistant` ### 示例条目 json { "system": "你是一名金融助手,请准确简要地回答用户的问题。", "user": "股票与债券有何区别?", "assistant": "股票代表对一家公司的所有权,而债券则是投资者向某一实体出借资金的债务形式。" } --- ## 支持语言 - **英语**:本数据集的核心语言。 - **中文**:得益于**BAAI/IndustryInstruction_Finance-Economics**子集的加入,中文内容占比显著提升。 - **其他多语言数据**:涵盖多语言命名实体识别数据源与Aya数据集的多语言内容。 --- ## 采集与预处理流程 1. **去重处理**:从所有源数据集中移除了超过6万条重复条目。 2. **数据清洗**:剔除非ASCII字符,修正标点与拼写错误,并统一数据格式。 3. **数据集合并**:将多源数据条目整合为一个统一的连贯数据集。 > 注:去重过程中部分标注信息暂未恢复,未来版本将重新加入完整标注。 4. **标注增强**:优化元数据以提升清晰度与可用性,包括任务类型与系统提示模板。 5. **XBRL标记集成**:从**Financial-NER-NLP**子集整合该功能,支持金融工具的结构化标注。 --- ## 伦理考量 - **用户隐私保护**:所有个人可识别信息(PII)均为合成且匿名化处理,符合全球隐私保护标准。 - **仅用于专业场景**:本数据集不能替代经认证的金融咨询或专业投资建议。 --- ## 局限性说明 - **数据偏差**:基于源数据集的分布特征,数据集覆盖范围可能偏向特定金融领域或主题。 - **准确性风险**:基于本数据集训练的模型输出,需在关键金融应用场景中进行人工验证。 - **多语言支持不均**:非英语条目数量参差不齐,尽管近期新增的BAAI数据集大幅提升了中文内容占比。 - **存在噪声数据**:已知存在少量非金融相关数据、格式异常的系统/用户/助手字段,以及部分非结构化数据。部分使用的数据集为未附带关联文档的检索增强生成数据,部分数据集更适合预训练场景(如cosmopedia)。总体而言,本数据集表现良好。  --- ## 引用方式 若使用本数据集,请引用以下文献: bibtex @dataset{josephgflowers2025financeinstruct, title={Finance-Instruct-500k}, author={Joseph G. Flowers}, year={2025}, url={https://huggingface.co/datasets/Josephgflowers/Finance-Instruct-500k} } --- ## 数据集加载方法 python from datasets import load_dataset dataset = load_dataset("Josephgflowers/Finance-Instruct-500k") print(dataset["train"][0]) --- ## 许可证 本数据集采用Apache 2.0许可证发布。