criteo/criteo-uplift
收藏资源简介:
该数据集是通过整合多个增量测试的结果构建的,这些测试是一种特定的随机试验程序,其中随机部分的人群被阻止接受广告。数据集包含2500万行,每行代表一个用户,包含11个特征、一个处理指标和两个标签(访问和转化)。特征值以浮点数形式表示,处理组和标签以二进制形式表示。为了保护隐私,数据进行了非均匀子采样,特征名称被匿名化,特征值被随机投影,以保持预测能力的同时防止恢复原始特征或用户上下文。数据集的主要用途是用于提升建模、个体处理效果预测/异质处理效果的基准测试。
This dataset is constructed by aggregating results from multiple incremental tests, which are a specific type of randomized trial procedure wherein a randomly selected subset of the population is denied access to advertisements. The dataset contains 25 million rows, where each row represents a single user and includes 11 features, one treatment metric, and two labels (visit and conversion). Feature values are represented as floating-point numbers, while treatment assignment and labels are encoded in binary form. To protect privacy, the data has undergone non-uniform subsampling, with feature names anonymized and feature values randomly projected, so as to preserve predictive performance while preventing the recovery of original features or user context. The primary use cases of this dataset are uplift modeling and benchmarking for individual treatment effect (ITE) prediction as well as heterogeneous treatment effect (HTE) estimation.
数据集概述
基本信息
- 许可证: cc-by-nc-sa-4.0
- 标签: criteo, advertising, causality
- 美观名称: criteo-uplift
- 大小类别: 10M<n<100M
- 任务类别: tabular-classification
数据描述
- 数据来源: 该数据集是通过多个增量测试(一种随机试验程序,其中随机部分人口被阻止接收广告)的结果组合而成。
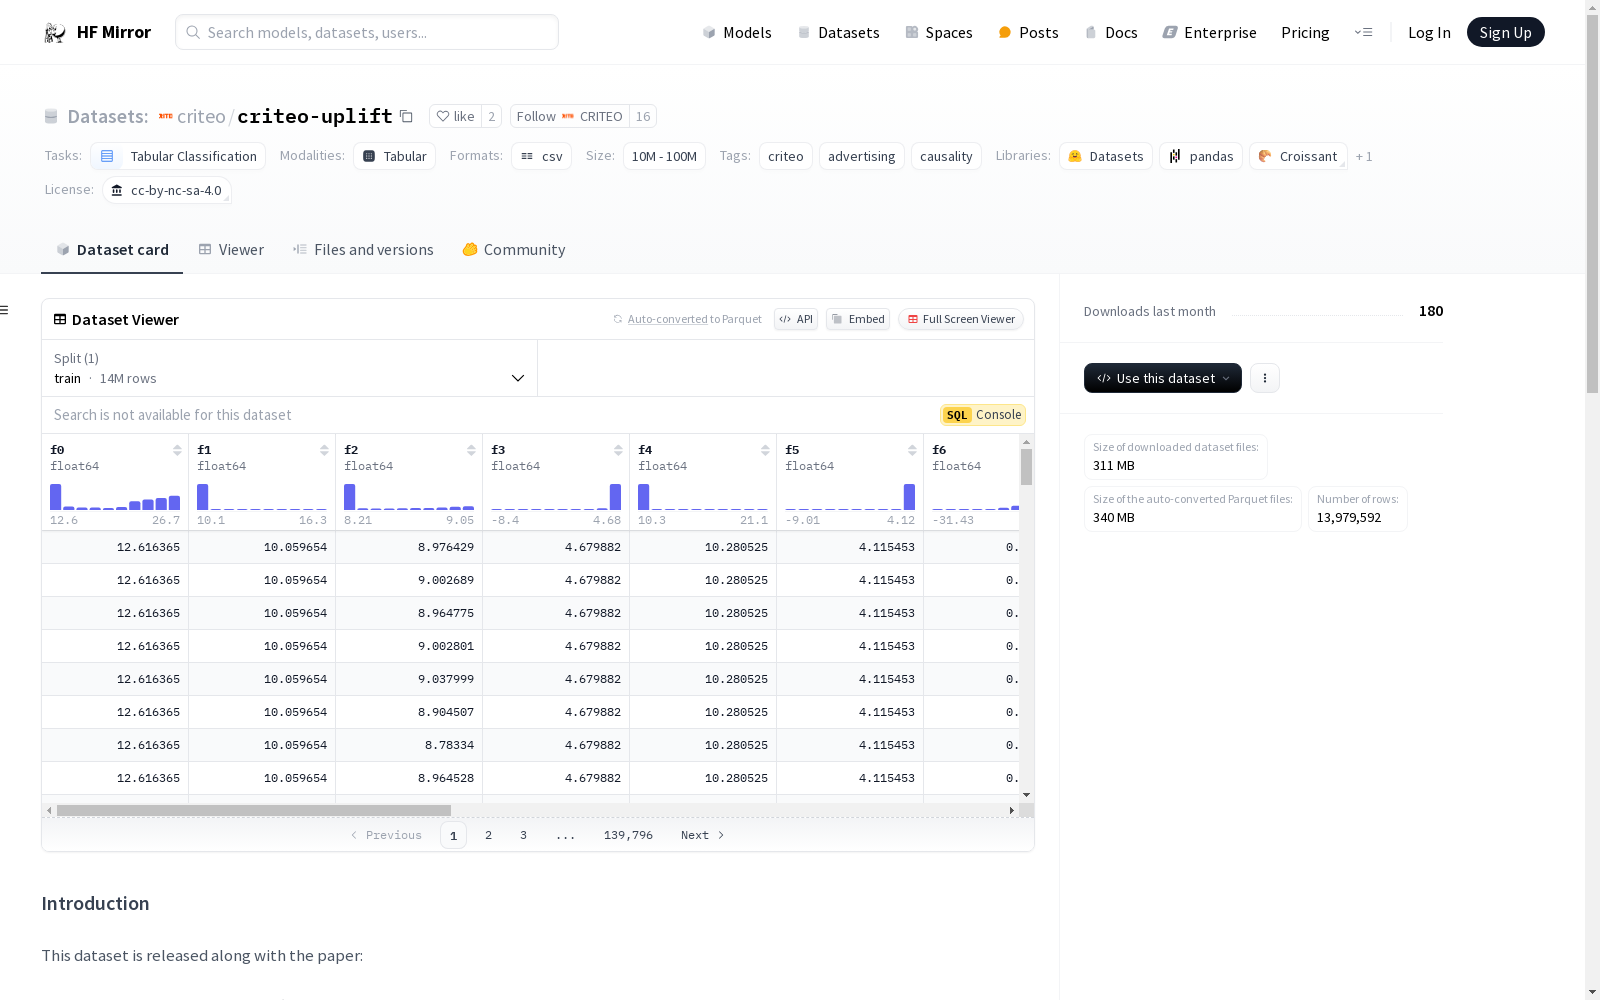
- 数据规模: 包含2500万行,每行代表一个用户,具有11个特征、一个处理指示符和2个标签(访问和转换)。
- 字段描述:
f0, f1, f2, f3, f4, f5, f6, f7, f8, f9, f10, f11: 特征值(密集,浮点数)treatment: 处理组(1 = 处理,0 = 对照)conversion: 用户是否发生转换(二进制,标签)visit: 用户是否发生访问(二进制,标签)exposure: 处理效果,用户是否有效暴露(二进制)
隐私保护
- 数据已经进行了非均匀子采样,以防止从数据集中推断出原始增量水平,同时保持一个现实且具有挑战性的基准。特征名称已匿名化,其值已随机投影,以保持预测能力,同时实际上不可能恢复原始特征或用户上下文。
关键数据
- 格式: CSV
- 大小: 297M(压缩)
- 行数: 13,979,592
- 平均访问率: 0.046992
- 平均转换率: 0.00292
- 处理比率: 0.85
任务和代码
- 主要用途: 用于基准测试Uplift Modeling、个体处理效果预测/异质处理效果。
- 参考论文: ITE and UM
- 参考实验代码和评估: Github