K-MMStar
收藏资源简介:
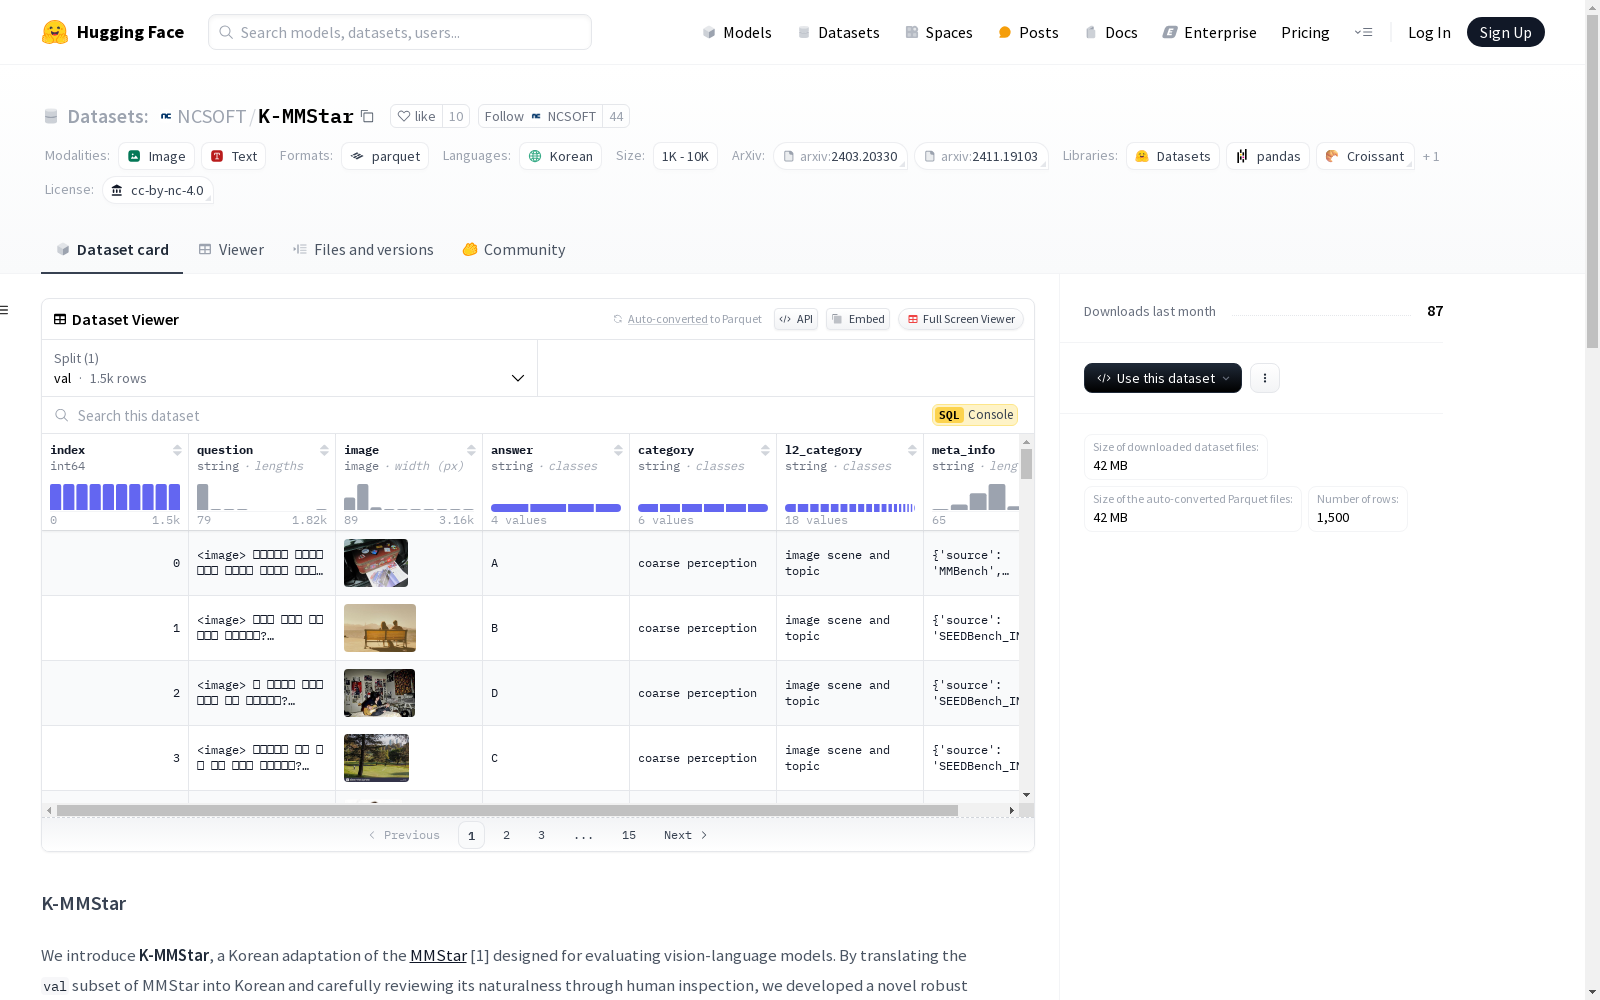
K-MMStar是一个用于评估视觉语言模型的韩语数据集。它是MMStar数据集的韩语改编版本,通过将MMStar的val子集翻译成韩语并进行人工审查,确保了其自然性。数据集包含多个特征,如问题、图像、答案、类别等,并分为多个评估维度,如粗略感知、细粒度感知和实例推理。数据集的目的是为了全面评估模型在韩语环境下的性能。
K-MMStar is a Korean-language dataset designed for evaluating vision-language models. It is a Korean adaptation of the MMStar dataset, created by translating the val subset of MMStar into Korean and undergoing manual reviews to guarantee its natural linguistic quality. The dataset comprises multiple components including questions, images, answers, and categories, and is divided into multiple evaluation dimensions such as coarse-grained perception, fine-grained perception, and instance-level reasoning. Its core purpose is to comprehensively evaluate the performance of models in a Korean-language context.
K-MMStar 数据集概述
基本信息
- 语言: 韩语 (ko)
- 许可证: CC BY-NC 4.0
- 配置:
- 名称: default
- 数据文件:
- 分割: val
- 路径: data/val-*
数据集结构
- 特征:
- index: 类型为 int64
- question: 类型为 string
- image: 类型为 image
- answer: 类型为 string
- category: 类型为 string
- l2_category: 类型为 string
- meta_info: 类型为 string
- 分割:
- 名称: val
- 字节数: 45162575.0
- 样本数: 1500
- 下载大小: 42027023
- 数据集大小: 45162575.0
数据集描述
K-MMStar 是 MMStar 数据集的韩语改编版本,专门用于评估视觉-语言模型的性能。该数据集通过将 MMStar 的 val 子集翻译成韩语,并通过人工检查确保其自然性,从而开发出一种新的韩语评估基准。数据集包含跨越 6 个评估维度的问答,如粗略感知、细粒度感知和实例推理,允许对模型在韩语中的表现进行全面评估。
引用
如果使用 K-MMStar 数据集进行研究,请引用以下内容: bibtex @misc{ju2024varcovisionexpandingfrontierskorean, title={VARCO-VISION: Expanding Frontiers in Korean Vision-Language Models}, author={Jeongho Ju and Daeyoung Kim and SunYoung Park and Youngjune Kim}, year={2024}, eprint={2411.19103}, archivePrefix={arXiv}, primaryClass={cs.CV}, url={https://arxiv.org/abs/2411.19103}, }