vaibhavalakshmiravideshik/mondo-doid-12k
收藏资源简介:
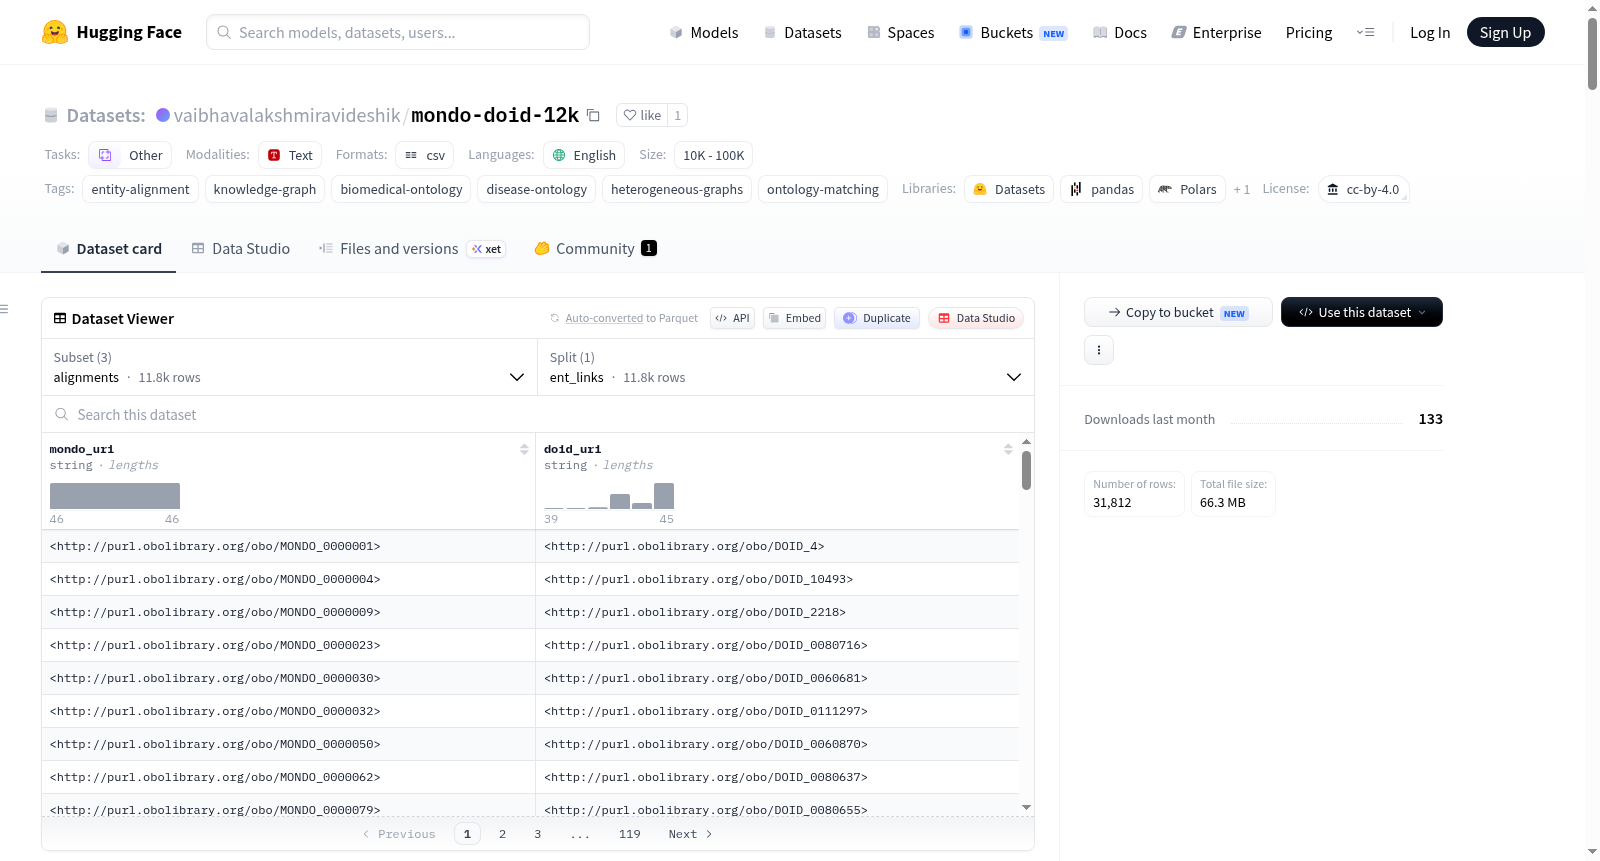
MONDO-DOID Entity Alignment 12K 是一个用于异构知识图谱的生物医学实体对齐基准数据集。它通过手动策划的精确匹配映射,对齐了Mondo疾病本体(MONDO)和人类疾病本体(DOID)中的疾病实体,这些映射以SSSOM格式由MONDO分发。该基准旨在支持现实的实体对齐研究,而非简化的字典匹配。金标准对齐嵌入在完整的MONDO和DOID本体图中,因此模型必须在存在显著模式不匹配、同义词变异、背景实体和本体特定粒度差异的情况下恢复对齐的疾病概念。数据集包含11,812个经过验证的金标准对齐对,以及来自两个本体的关系三元组和属性三元组,总数据量约为62.23 MB。KG1(MONDO)包含27,586个实体、300,671个属性三元组和44,674个关系三元组,涉及13种关系类型;KG2(DOID)包含12,127个实体、80,515个属性三元组和17,093个关系三元组,仅涉及一种关系类型。数据集具有异构性特征,如模式不匹配、密度不对称和粒度不匹配,适用于实体对齐、本体匹配和多模态对齐模型的研究与基准测试。
MONDO-DOID Entity Alignment 12K is a benchmark dataset for biomedical entity alignment across heterogeneous knowledge graphs. It aligns disease entities from the Mondo Disease Ontology (MONDO) and the Human Disease Ontology (DOID) via manually curated exact matching mappings, which are distributed by MONDO in SSSOM format. This benchmark is designed to support realistic entity alignment research rather than simplified dictionary matching. Gold-standard alignments are embedded within the full MONDO and DOID ontology graphs, so models must recover aligned disease concepts amid significant schema mismatches, synonym variations, background entities, and ontology-specific granularity discrepancies. The dataset contains 11,812 validated gold-standard alignment pairs, along with relational and attribute triples from both ontologies, with a total data volume of approximately 62.23 MB. KG1 (MONDO) consists of 27,586 entities, 300,671 attribute triples, and 44,674 relational triples, covering 13 relationship types; KG2 (DOID) includes 12,127 entities, 80,515 attribute triples, and 17,093 relational triples, with only one relationship type. The dataset exhibits heterogeneity characteristics including schema mismatches, asymmetric density, and granularity mismatches, making it suitable for research and benchmarking of entity alignment, ontology matching, and multi-modal alignment models.