Wikipedia-translated
收藏资源简介:
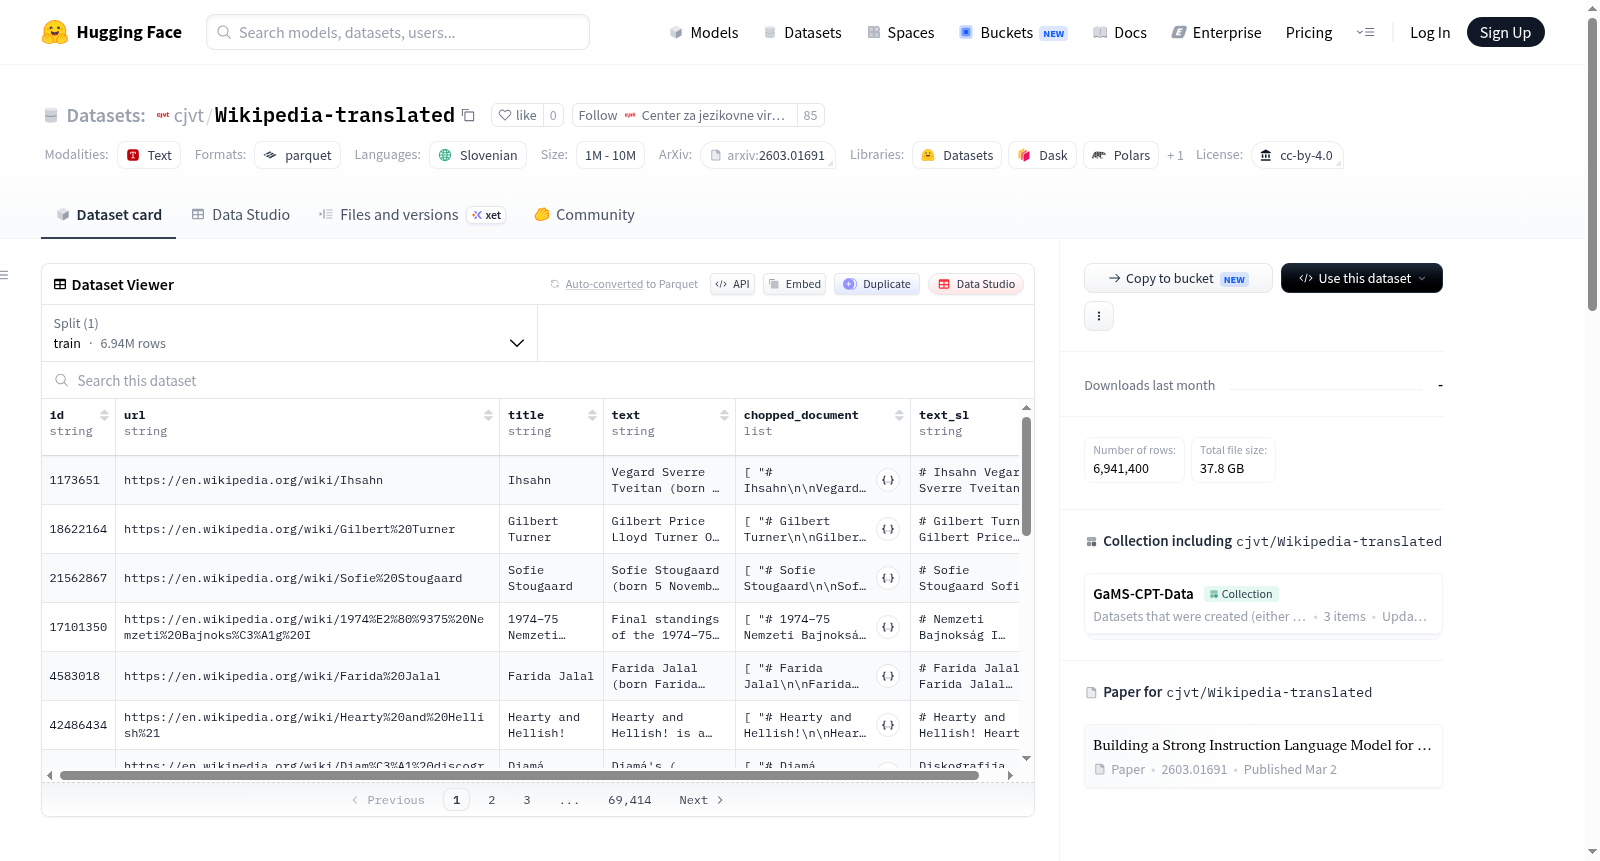
该数据集是英文维基百科的斯洛文尼亚语翻译版本,以 Markdown 格式提供。英文原始数据来源于 zidsi/wikipedia_markdown 数据集(2025年1月23日快照),并利用 cjvt/GaMS-DPO-Translator 模型进行自动翻译。数据集规模庞大,包含约 690 万份文档,翻译后的斯洛文尼亚语文本总计约 36 亿单词。数据集结构清晰,每条记录包含以下字段:唯一标识符 (`id`)、原始英文文章 URL (`url`)、原始英文文章标题 (`title`)、原始英文文章全文 (`text`)、为适应翻译模型上下文窗口而切分的英文文本块序列 (`chopped_document`),以及对应的斯洛文尼亚语翻译文章 (`text_sl`)。该数据集仅包含一个训练分割,样本数量为 6,941,400 个。其主要语言为斯洛文尼亚语。该资源在 PoVeJMo 研究计划(特别是 SloLLaMai 项目)框架下创建,旨在为斯洛文尼亚语提供开放访问且计算高效的语言模型资源,获得了斯洛文尼亚研究与创新署、NextGenerationEU 以及欧盟 Horizon Europe 计划的资金支持。数据集采用 CC BY 4.0 许可协议发布。它适用于机器翻译模型训练与评估、构建斯洛文尼亚语-英语双语语料库、跨语言信息检索、以及作为斯洛文尼亚语大语言模型预训练或指令微调的高质量语料。
This dataset is a Slovenian translation of the English Wikipedia, provided in Markdown format. The original English data is sourced from the 'zidsi/wikipedia_markdown' dataset (snapshot dated January 23, 2025), and was automatically translated using the 'cjvt/GaMS-DPO-Translator' model. This is a large-scale dataset containing approximately 6.9 million documents, with the total volume of translated Slovenian text reaching about 3.6 billion words. The dataset has a well-defined structure, where each record includes the following fields: unique identifier (`id`), URL of the original English article (`url`), title of the original English article (`title`), full text of the original English article (`text`), sequence of chopped English text blocks split to fit the context window of the translation model (`chopped_document`), and the corresponding Slovenian translated article (`text_sl`). This dataset only contains one training split, with a total of 6,941,400 samples, and its primary language is Slovenian. This resource was developed under the framework of the PoVeJMo research program, specifically the SloLLaMai project, with the goal of providing open-access and computationally efficient language model resources for Slovenian. It has received funding from the Slovenian Research and Innovation Agency, NextGenerationEU, and the EU Horizon Europe program. The dataset is released under the CC BY 4.0 license. It is applicable for training and evaluating machine translation models, constructing Slovenian-English bilingual corpora, cross-lingual information retrieval, and serving as high-quality corpus for pre-training or instruction fine-tuning of Slovenian large language models (LLMs).
数据集概述:Slovene translation of English Wikipedia
该数据集是英文维基百科的斯洛文尼亚语翻译版本,以 Markdown 格式提供。
- 语言:斯洛文尼亚语 (sl)
- 许可证:CC BY 4.0
- 数据来源:英文维基百科数据取自 zidsi/wikipedia_markdown 数据集,使用的快照日期为 2025年1月23日。
- 翻译模型:使用 cjvt/GaMS-DPO-Translator 模型进行翻译。
数据规模
- 文档数量:约 690 万 篇文档
- 斯洛文尼亚语词汇量:约 36 亿 个词
数据字段
数据集包含以下字段:
id:文档 IDurl:文档 URLtitle:原始(英文)文章标题text:原始(英文)文章内容chopped_document:为适配 GaMS-DPO-Translator 模型上下文窗口而切分的较小文本单元列表text_sl:英文文章的斯洛文尼亚语翻译
数据集划分
该数据集仅包含一个划分:
- train:共 6,941,400 个样本,数据大小约 63.9 GB(下载大小约 37.8 GB)
引用
bibtex misc{vreš2026buildingstronginstructionlanguage, title={Building a Strong Instruction Language Model for a Less-Resourced Language}, author={Domen Vreš and Tjaša Arčon and Timotej Petrič and Dario Vajda and Marko Robnik-Šikonja and Iztok Lebar Bajec}, year={2026}, eprint={2603.01691}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2603.01691}, }