HEAD-QA v2
收藏资源简介:
HEAD-QA v2是由拉科鲁尼亚大学构建的医疗推理多选问答基准数据集,涵盖西班牙六类专业资格考试的十年真题。该数据集包含12,751道高质量题目,涵盖医学、护理等六大专业领域,数据源自西班牙卫生部公开的官方考试资料。创建过程通过PDF解析、图像映射和化学公式标准化等预处理流程,确保数据格式统一与机器可读性。该数据集主要应用于评估大语言模型在生物医学领域的推理能力,旨在解决专业领域知识理解与复杂诊断推理的基准测评难题。
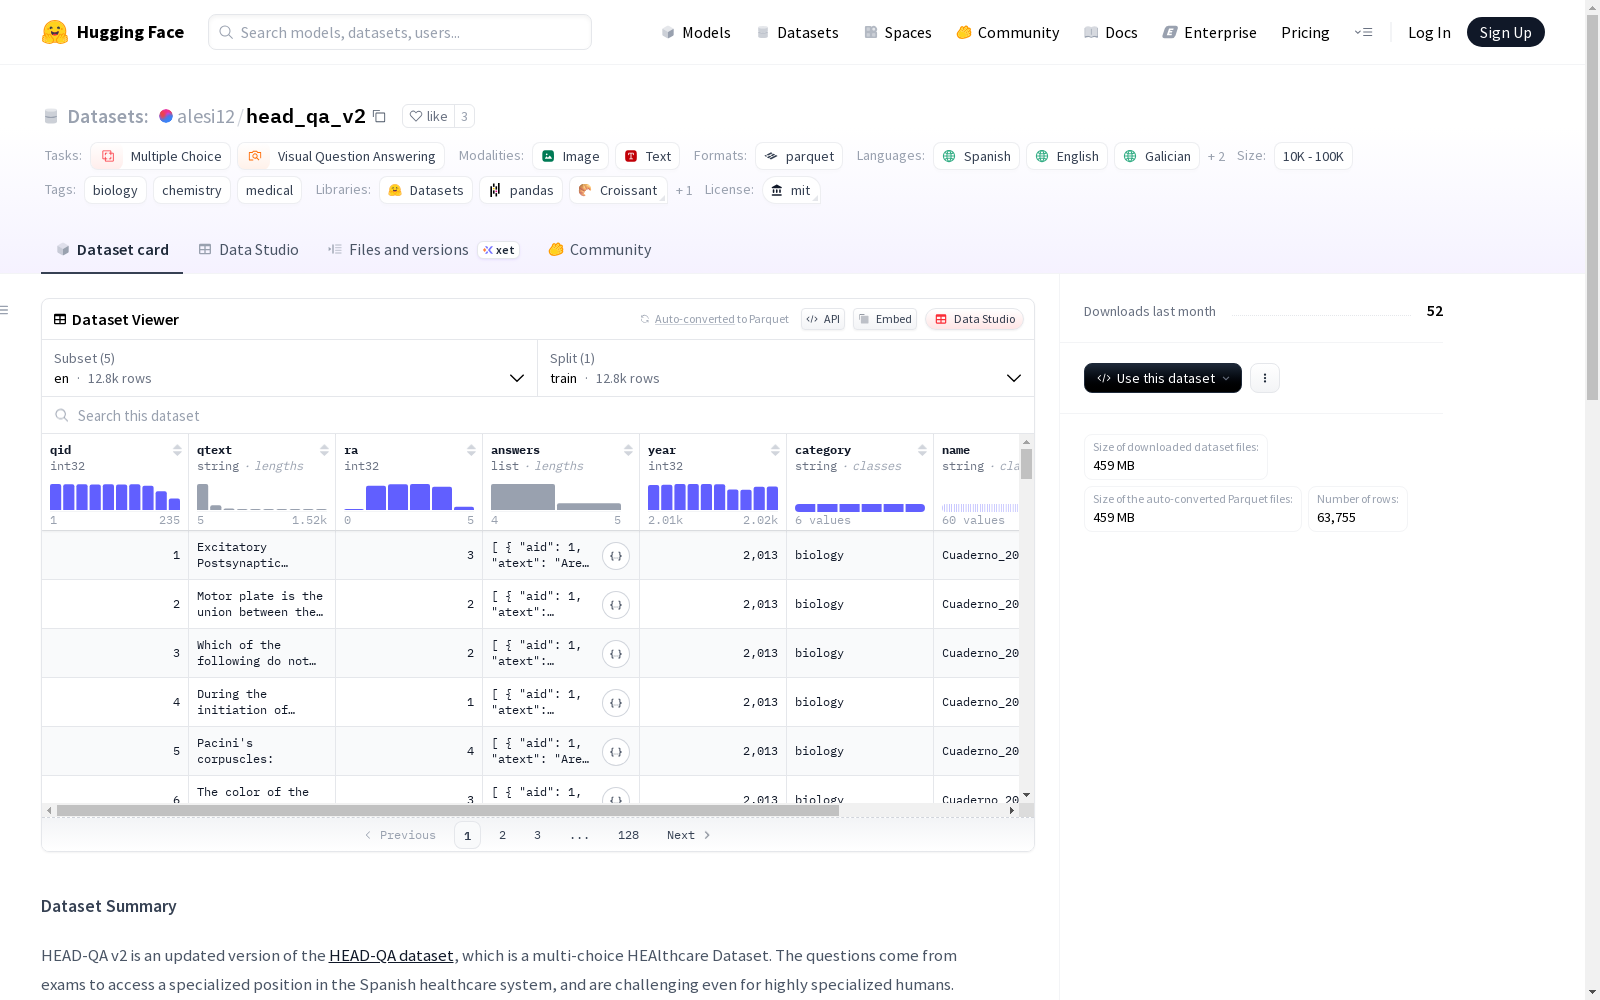
HEAD-QA v2 is a medical reasoning multiple-choice question answering benchmark dataset developed by the University of A Coruña. It covers ten-year official real questions from six types of professional qualification examinations in Spain, containing 12,751 high-quality questions spanning six professional fields including medicine and nursing. The dataset's data is sourced from official examination materials publicly released by the Spanish Ministry of Health. During the dataset construction, preprocessing pipelines including PDF parsing, image mapping, and chemical formula standardization were implemented to ensure uniform data formatting and machine readability. This benchmark is primarily designed to evaluate the reasoning capabilities of Large Language Models (LLMs) in the biomedical domain, aiming to tackle the challenges of benchmark evaluation for professional domain knowledge comprehension and complex diagnostic reasoning.
HEAD-QA V2 数据集概述
数据集基本信息
- 名称:HEAD-QA V2
- 许可证:MIT
- 规模类别:10K<n<100K
- 任务类别:多项选择、视觉问答
- 标签:生物学、化学、医学
语言支持
- 西班牙语 (es)
- 英语 (en)
- 加利西亚语 (gl)
- 意大利语 (it)
- 俄语 (ru)
数据集配置
英语配置 (en)
- 训练集样本数:12,751
- 下载大小:91,401,201 字节
- 数据集大小:105,722,025.276 字节
西班牙语配置 (es)
- 训练集样本数:12,751
- 下载大小:91,554,296 字节
- 数据集大小:106,107,706.276 字节
加利西亚语配置 (gl)
- 训练集样本数:12,751
- 下载大小:91,537,229 字节
- 数据集大小:105,914,317.276 字节
意大利语配置 (it)
- 训练集样本数:12,751
- 下载大小:91,569,865 字节
- 数据集大小:106,015,685.276 字节
俄语配置 (ru)
- 训练集样本数:12,751
- 下载大小:92,665,553 字节
- 数据集大小:109,395,800.276 字节
数据特征
所有配置包含以下特征:
- qid:问题ID(int32)
- qtext:问题文本(string)
- ra:正确答案索引(int32)
- answers:答案列表
- aid:答案ID(int32)
- atext:答案文本(string)
- year:年份(int32)
- category:类别(string)
- name:名称(string)
- image:图像(image)
数据集描述
HEAD-QA v2是HEAD-QA数据集的更新版本,是一个多选医疗数据集。问题来源于西班牙医疗系统专业职位考试的试题,即使对高度专业的人员也具有挑战性。
涵盖主题
- 医学
- 护理学
- 心理学
- 化学
- 药理学
- 生物学
扩展内容
HEAD-QA V2通过使用meta-llama/Llama-3.1-8B-Instruct模型进行多语言翻译,在原始数据集基础上进行了扩展。
引用信息
原始版本论文引用:
@inproceedings{vilares-gomez-rodriguez-2019-head, title = "{HEAD}-{QA}: A Healthcare Dataset for Complex Reasoning", author = "Vilares, David and G{o}mez-Rodr{i}guez, Carlos", booktitle = "Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics", month = jul, year = "2019", address = "Florence, Italy", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/P19-1092", doi = "10.18653/v1/P19-1092", pages = "960--966" }