exp_rpt_stack-pytest-v2-qwen3.5-122b-131k-opencode-sft-serveparity
收藏资源简介:
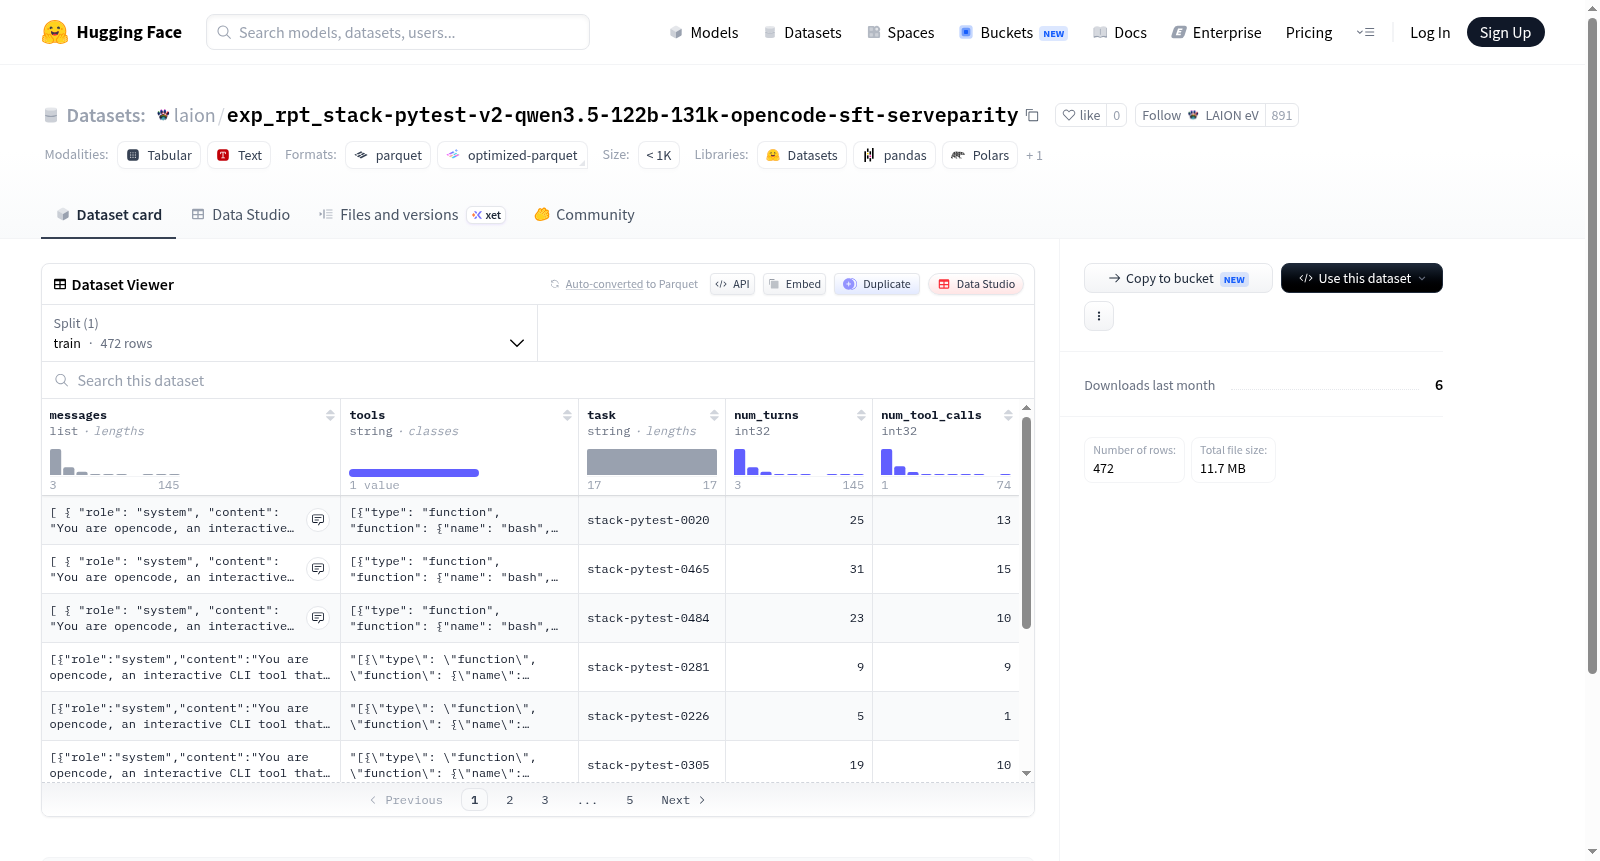
该数据集是一个结构化的对话数据集,专注于记录多轮交互过程中对工具(或函数)的调用。每个数据样本包含以下核心字段:一个消息列表(`messages`),其中每条消息包含角色(`role`)、内容(`content`)以及可选的工具调用信息(`tool_calls`,包含调用类型和具体的函数名称与参数);一个描述所用工具的字符串字段(`tools`);一个指明对话任务的字符串字段(`task`);以及两个统计字段:对话轮数(`num_turns`)和工具调用次数(`num_tool_calls`)。数据集目前仅包含训练集(`train` split),共472个样本。数据以结构化格式存储,适用于训练或评估能够理解和执行工具调用的对话系统或智能体。
This is a structured dialogue dataset focused on recording tool (or function) calls during multi-turn interactions. Each data sample includes the following core fields: a list of messages (`messages`), where each message contains a role (`role`), content (`content`), and optional tool call information (`tool_calls`, which includes the call type, specific function name and parameters); a string field (`tools`) that describes the tools used; a string field (`task`) that specifies the dialogue task; plus two statistical fields: the number of dialogue turns (`num_turns`) and the number of tool calls (`num_tool_calls`). The dataset currently only includes the training split (`train`), with a total of 472 samples. The data is stored in a structured format and is suitable for training or evaluating dialogue systems or AI Agents that can understand and execute tool calls.