Necyklopedie-MASK
收藏资源简介:
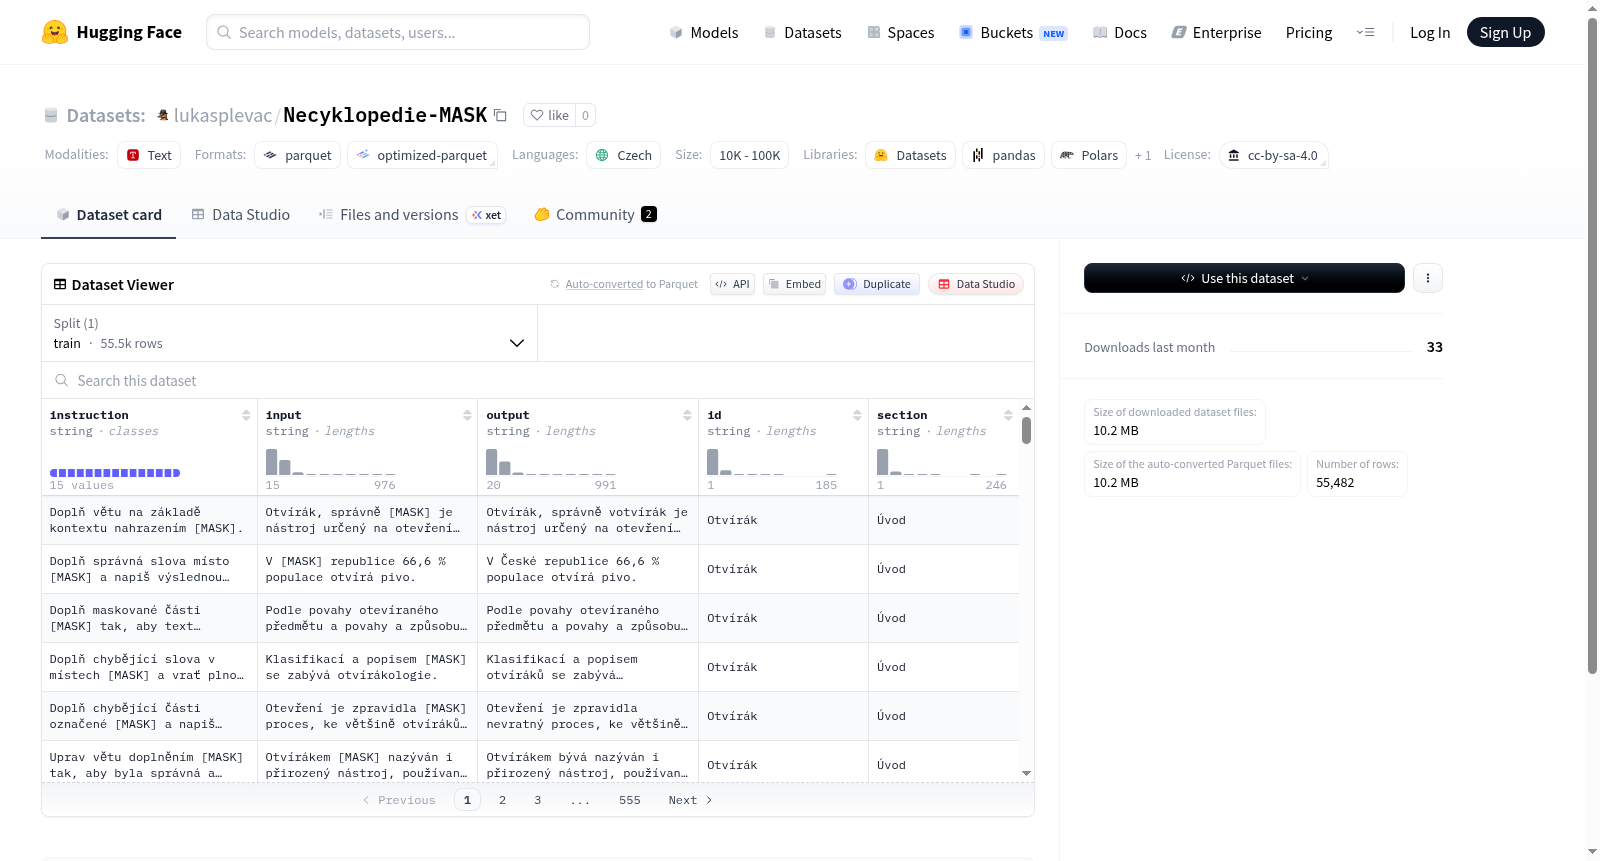
该数据集为捷克语(cs)文本数据集,采用CC-BY-SA-4.0许可协议。数据结构包含55,482个训练样本,总大小20.4MB。每个样本包含5个字段:instruction(指令文本)、input(输入内容)、output(输出内容)、id(唯一标识符)和section(分类章节)。数据以输入-输出配对形式组织,适用于文本生成、指令跟随等自然语言处理任务。由于字段命名特征,推测可能用于教学场景或任务导向型对话系统的开发。
This is a Czech (cs) text dataset released under the CC-BY-SA-4.0 license. It contains 55,482 training samples with a total size of 20.4 MB. Each sample consists of five fields: instruction, input, output, id (unique identifier), and section (classification category). The dataset is structured as input-output pairs and is suitable for natural language processing tasks including text generation and instruction following. Given the naming patterns of its fields, it is hypothesized that this dataset could be utilized for teaching scenarios or the development of task-oriented dialogue systems.
数据集概述
基本信息
- 数据集名称: Necyklopedie-MASK
- 语言: 捷克语 (cs)
- 许可证: CC BY-SA 4.0 (cc-by-sa-4.0)
数据集结构
- 配置名称: default
- 数据文件:
- 训练集 (train):
data/train-*
- 训练集 (train):
数据特征
数据集包含以下字段:
- instruction (string): 指令
- input (string): 输入
- output (string): 输出
- id (string): 标识符
- section (string): 部分
数据集规模
- 训练集样本数量: 55,482
- 训练集大小: 20,447,865 字节
- 下载大小: 10,183,056 字节
- 数据集总大小: 20,447,865 字节