Nemotron-Personas-Vietnam
收藏资源简介:
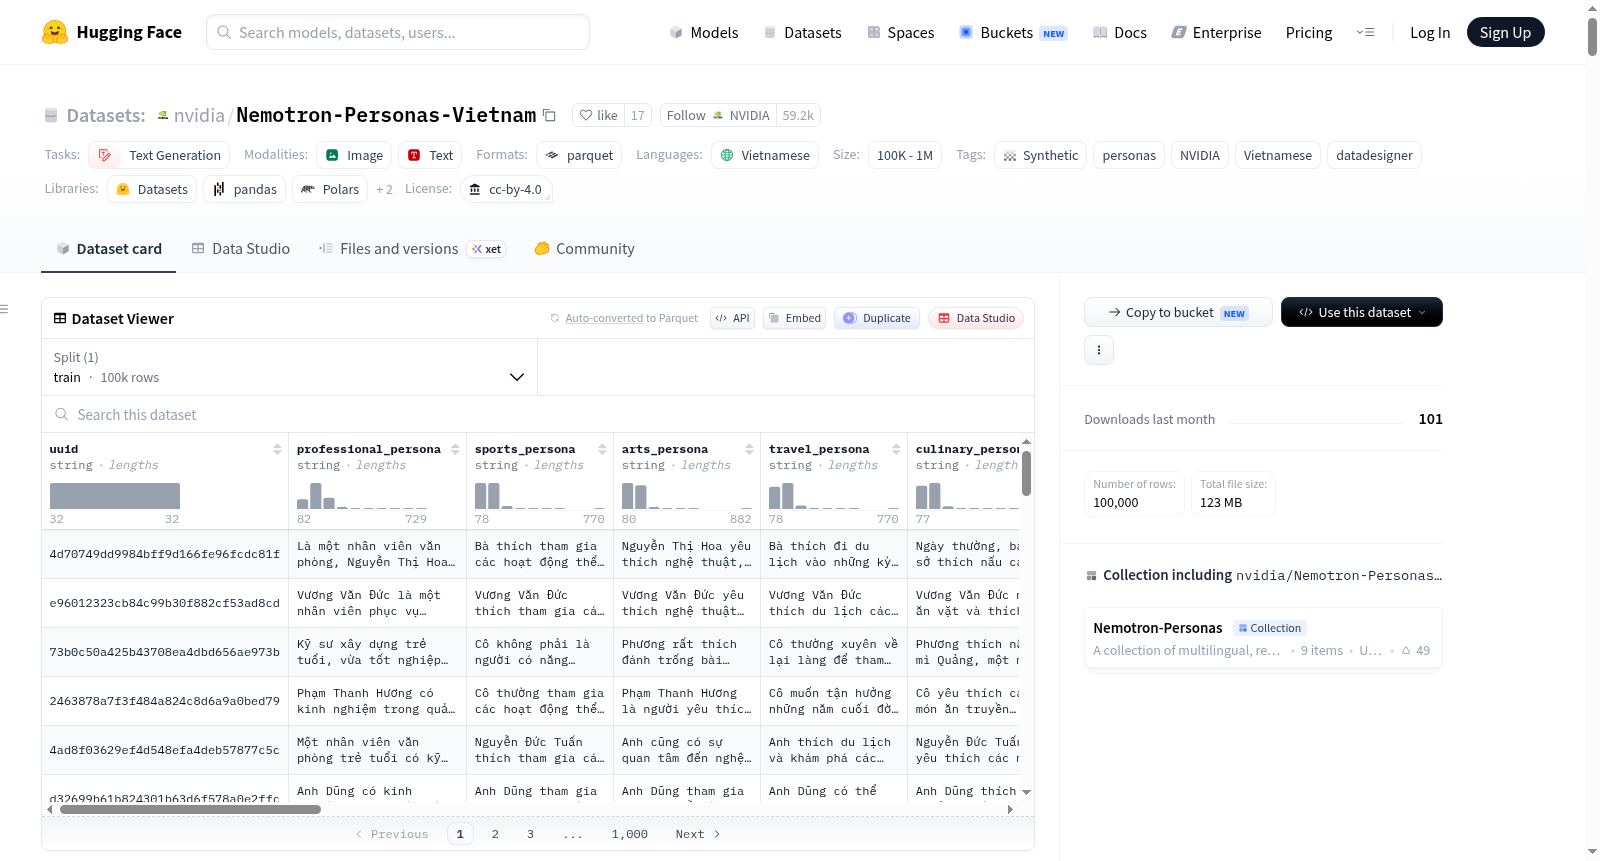
Nemotron-Personas-Vietnam 是一个开源的大规模越南语合成人物角色数据集,遵循 CC BY 4.0 许可。该数据集基于越南真实世界的人口统计、地理和人格特质分布生成,旨在全面反映越南人口的多样性和特征。它是首个此类大规模越南语数据集,旨在支持越南开发人员构建融入重要地区特定人口统计和文化背景的“主权AI”系统。通过扩展用于主权AI模型开发的合成数据多样性,该数据集有助于减轻数据和模型偏见,并改善越南语模型响应的多样性。数据集包含 100,000 条记录,每条记录包含 6 个不同类型的人物角色描述,总计 600,000 个人物角色。数据规模约为 118M 个 token,其中 52M 为人物角色相关 token。数据集由 21 个字段构成,包括:1 个全局唯一标识符 (uuid);6 个具体领域的人物角色描述字段(职业、体育、艺术、旅行、烹饪人物角色以及一个简洁的通用人物角色);以及 14 个人物角色属性与背景字段,涵盖性别、年龄(18-90岁)、婚姻状况、教育水平、职业类别(20种)、居住区域(城乡)、所属省份/直辖市(覆盖河内、胡志明市、海防、岘港、芹苴、同奈这6个地区)和国家等。所有叙述性文本字段均为标准越南语。数据生成基于越南统计总局(GSO)的官方统计数据(2024年人口和住房普查、家庭生活水平调查)以及 FPT 相关机构的本地专业知识,并利用 NVIDIA 的 NeMo Data Designer 复合AI系统及其专有概率图模型和 SaoLa4-Small 语言模型完成。数据集仅包含成年角色,所有数据均为人工合成,任何与真实人物的相似性均属巧合。该数据集适用于需要多样化、接地气的越南语人物角色数据的任务,如对话系统开发、内容生成、偏见缓解研究以及旨在提高文化相关性的AI模型训练。
Nemotron-Personas-Vietnam is an open-source large-scale Vietnamese synthetic persona dataset licensed under the CC BY 4.0 license. This dataset is generated based on the real-world demographic, geographic, and personality trait distributions of Vietnam, with the goal of comprehensively reflecting the diversity and characteristics of the Vietnamese population. As the first large-scale Vietnamese dataset of its kind, it aims to support Vietnamese developers in constructing "sovereign AI" systems that incorporate critical region-specific demographic and cultural backgrounds. By expanding the diversity of synthetic data for sovereign AI model development, this dataset helps mitigate data and model biases, and enhances the diversity of responses from Vietnamese language models. The dataset comprises 100,000 records, each containing 6 distinct types of persona descriptions, totaling 600,000 personas. The overall data scale is approximately 118M tokens, of which 52M are persona-related tokens. The dataset consists of 21 fields: 1 globally unique identifier (UUID); 6 domain-specific persona description fields (occupational, sports, art, travel, cooking personas, and a concise general persona); and 14 persona attribute and background fields covering gender, age (18–90 years), marital status, education level, occupational categories (20 types), residential area (urban/rural), affiliated province/municipality (covering six regions: Hanoi, Ho Chi Minh City, Haiphong, Da Nang, Can Tho, Dong Nai), and country. All narrative text fields are in standard Vietnamese. The dataset was generated using official statistical data from the General Statistics Office of Vietnam (GSO) (2024 Population and Housing Census, Household Living Standards Survey) and local professional expertise from relevant FPT institutions, leveraging NVIDIA's NeMo Data Designer composite AI system, its proprietary probabilistic graphical models, and the SaoLa4-Small language model. The dataset only includes adult personas, and all data is synthetic; any similarity to real individuals is purely coincidental. This dataset is applicable to tasks requiring diverse, culturally grounded Vietnamese persona data, such as dialogue system development, content generation, bias mitigation research, and AI model training aimed at improving cultural relevance.
Nemotron-Personas-Vietnam 是一个基于越南真实人口分布合成的开源人物画像数据集,旨在支持越南主权人工智能(Sovereign AI)的开发。
基本信息
- 发布方:NVIDIA Corporation 与 FPT Smart Cloud、FPT 集团量子 AI 与网络安全研究所合作开发。
- 许可协议:CC BY 4.0(可免费用于商业和非商业用途)。
- 发布日期:2026年6月4日。
- 语言:越南语。
数据规模与构成
- 记录数:100,000 条。
- 人物画像数:600,000 个(每条记录包含 6 个画像)。
- 令牌数:总计 1.18 亿令牌,其中人物画像令牌 5200 万。
- 字段数:21 个字段,包括 6 个人物画像字段和 15 个上下文(属性与人口统计)字段。具体字段如下:
| 字段 | 类型 | 描述 |
|---|---|---|
| uuid | string | 全局唯一标识符 |
| professional_persona | string | 职业画像(描述主要工作领域、关键专业技能、特质与行为) |
| sports_persona | string | 体育画像(描述运动兴趣、运动队偏好、健身方式) |
| arts_persona | string | 艺术画像(描述创意表达参与度及艺术对身份认同的影响) |
| travel_persona | string | 旅行画像(描述旅行兴趣与风格) |
| culinary_persona | string | 烹饪画像(描述饮食偏好、烹饪技能水平、就餐体验偏好) |
| persona | string | 简洁通用画像(捕捉个人视角与生活方式) |
| cultural_background | string | 文化背景描述 |
| skills_and_expertise | string | 专业技能与个人技能(叙事格式) |
| skills_and_expertise_list | string | 技能与专长列表(字符串化列表) |
| hobbies_and_interests | string | 个人兴趣与休闲活动(叙事格式) |
| hobbies_and_interests_list | string | 爱好与个人兴趣列表(字符串化列表) |
| career_goals_and_ambitions | string | 职业抱负与长期职业目标 |
| sex | string | 性别(Nam/Nữ) |
| age | integer | 年龄(18–90 岁) |
| marital_status | string | 婚姻状况(Độc thân/Đã kết hôn/Góa/Ly thân) |
| education_level | string | 最高教育程度(7 类:从无教育到研究生) |
| occupation | string | 职业类别(20 种,如 Buôn bán / kinh doanh、Kỹ thuật viên / kỹ sư 等) |
| zone | string | 居住区域(Đô Thị/Nông Thôn) |
| region | string | 省份/直辖市(覆盖 6 个:河内、胡志明市、海防市、岘港市、芹苴市、同奈省) |
| country | string | 国家(恒定值:"Việt Nam") |
- 唯一姓名组合:约 13,000 种(基于越南真实命名数据,姓氏分布如 Nguyễn 约 40%,Trần 约 11% 等)。
- 职业结构:基于人口普查数据,共 20 个职业类别。
- 人物画像类型:包括职业、体育、艺术、旅行、烹饪、通用简洁六类。
- 数据切分:仅包含
train切分。
数据来源
- 官方统计:越南统计局(GSO)2024 年人口与住房普查数据、2024 年越南家庭生活水平调查(VHLSS)。
- 行政区划依据:根据 2025 年生效的越南行政合并方案确定边界。
- 本地专长:FPT Smart Cloud 与 FPT 量子 AI 及网络安全研究所提供本地人口与文化专家支持。
生成方法
使用 NeMo Data Designer(NVIDIA 企业级复合 AI 系统)生成,结合:
- 专有概率图模型(PGM)。
- Apache-2.0 许可的
SaoLa4-Small模型。 - 内置验证与评估方法。
限制与假设:
- 数据集由随机合成生成,任何与真实人物的相似纯属巧合。
- 由于公共数据可获取性限制,部分变量之间使用了独立性假设(如职业分配中性别、教育水平、年龄被假设为独立影响结果)。
- 仅包含 18 岁及以上的成年人物画像。
- 使用标准越南语生成,排除企业特定场景(如金融、医疗)及姓名、个性特征等字段。
预期用途
- 拓展越南主权 AI 模型开发的合成数据多样性。
- 减少训练数据中的数据稀缺和潜在偏见(特别是现有画像数据集中的偏见)。
- 改善模型在越南语回复中的多样性。
- 免费提供,鼓励开发者、研究人员和数据专业人员使用。