
SVLTA
收藏资源简介:
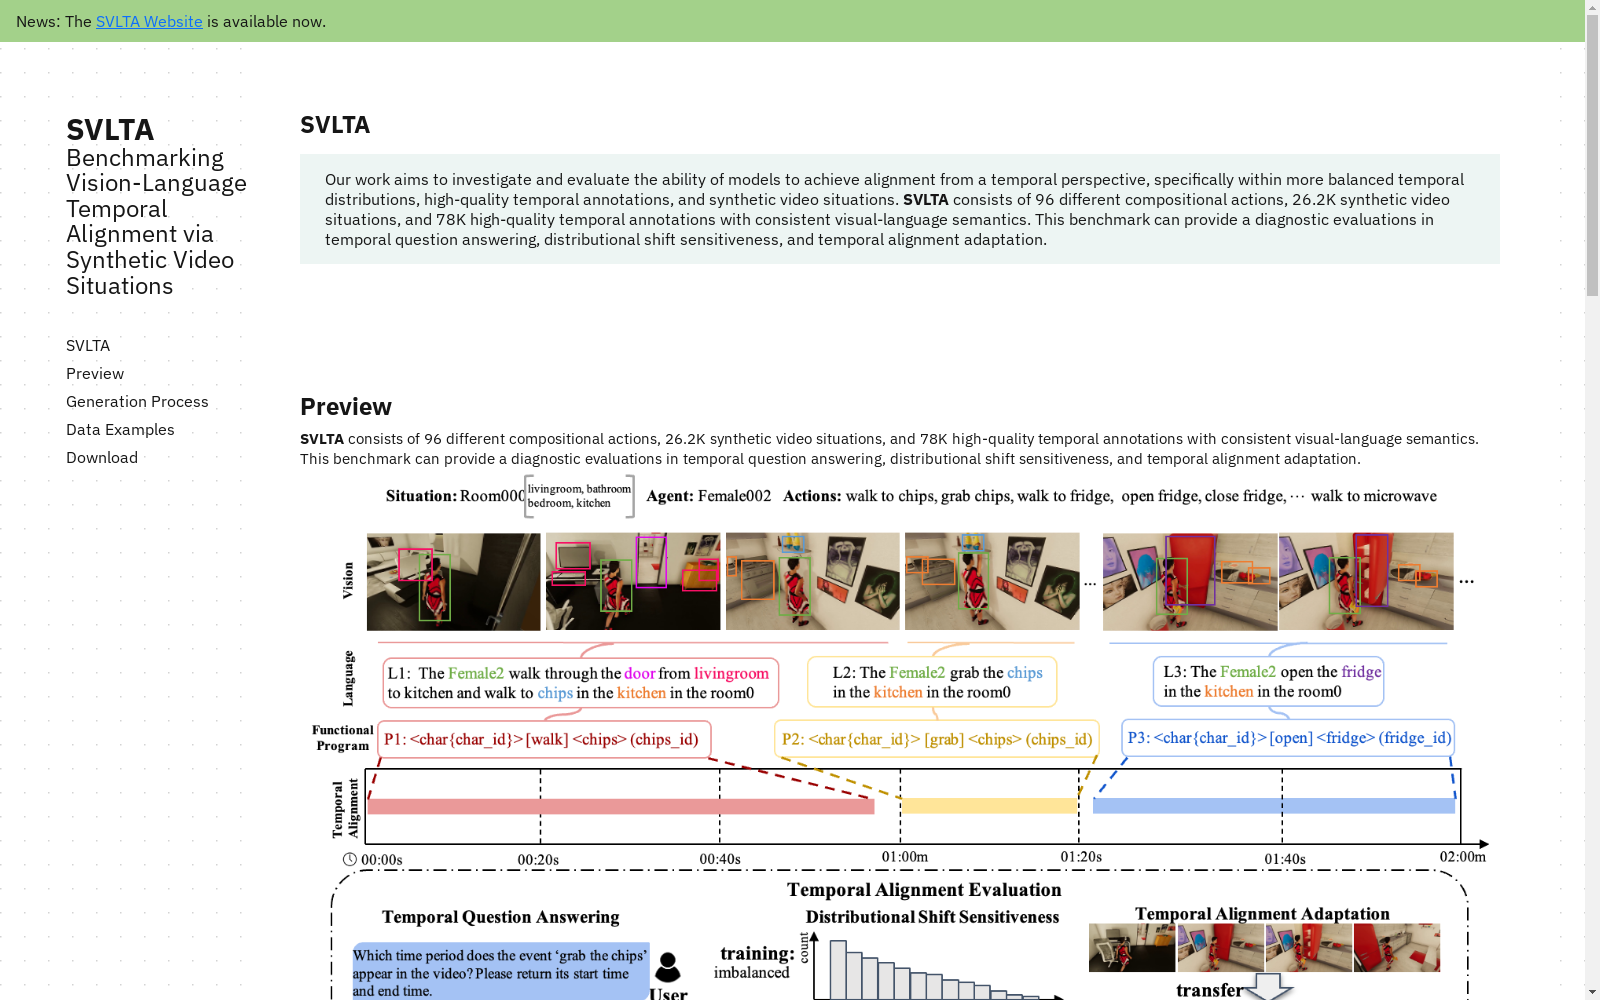
SVLTA是一个合成的视觉语言时间对齐数据集,由中国科学技术大学等机构提出。该数据集通过模拟环境中的功能程序生成合成视频,包含25.3K个人类活动场景,77.1K个语言描述和高质量的时间对齐活动序列,涵盖了96种不同的组合动作。数据集旨在为视觉语言时间对齐任务提供一个公平的诊断框架,具有可扩展性、可控性、合成性、组合性和无偏性等特点。
SVLTA is a synthetic vision-language temporal alignment dataset proposed by institutions including the University of Science and Technology of China. Generated via functional programs in simulated environments, the dataset contains 25.3K human activity scenes, 77.1K language descriptions, and high-quality temporally aligned activity sequences, covering 96 distinct composite actions. It aims to provide a fair diagnostic framework for vision-language temporal alignment tasks, and possesses characteristics including scalability, controllability, synthetic nature, compositionality, and unbiasedness.
- 1SVLTA: Benchmarking Vision-Language Temporal Alignment via Synthetic Video Situation中国科学技术大学 · 2025年


