
CineDance-1M
收藏资源简介:
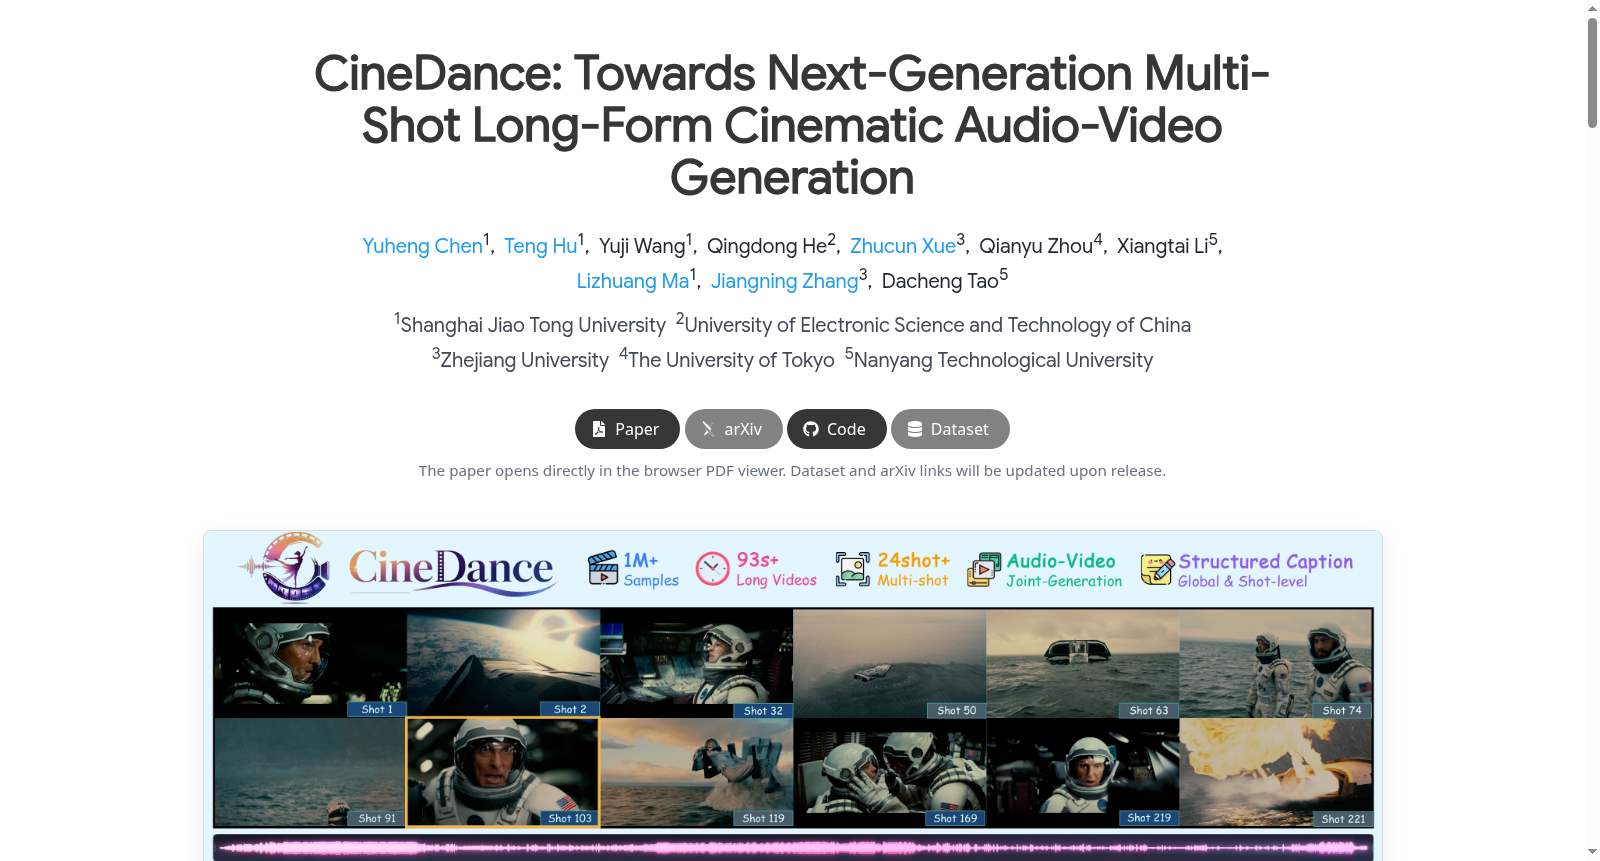
CineDance-1M是由多所顶尖学术机构联合创建的大规模、开源的文本-音频-视频(T2AV)数据集,专门为多镜头、长时长的影视级音视频联合生成而设计。该数据集包含100万条高质量序列,平均时长92.8秒,每段视频包含24.2个连续镜头,以1080p分辨率提供结构化、可配置的双模态标注。其创建过程采用严谨的三阶段流程:首先通过多样化来源与全面清洗确保原始素材质量;其次引入基于电影理论的叙事解析算法,将离散镜头组装为连贯的长叙事单元;最后采用分层双模态标注范式,通过锚定令牌实现全局主体定义与细粒度镜头级描述的精确绑定。该数据集主要应用于推动多镜头长时影视叙事生成研究,旨在解决现有开源模型在长时生成中存在的时序退化、跨镜头语义一致性缺失、以及音视频对齐困难等核心挑战,为构建下一代影视内容生成系统奠定数据基础。
CineDance-1M is a large-scale, open-source text-audio-video (T2AV) dataset jointly created by multiple top-tier academic institutions, specifically designed for multi-shot, long-duration film/TV-grade audio-video joint generation. This dataset encompasses 1 million high-quality sequences, with an average duration of 92.8 seconds, where each video contains 24.2 consecutive shots and is provided at 1080p resolution with structured, configurable dual-modal annotations. Its development follows a rigorous three-stage workflow: first, raw material quality is ensured through diverse data sources and comprehensive cleaning; second, a film theory-based narrative parsing algorithm is introduced to assemble discrete shots into coherent long narrative units; finally, a hierarchical dual-modal annotation paradigm is adopted, achieving precise binding between global subject definitions and fine-grained shot-level descriptions via anchor tokens. This dataset is primarily applied to advance research on multi-shot long-form film/TV narrative generation, aiming to address core challenges faced by current open-source models in long-duration generation, including temporal degradation, lack of cross-shot semantic consistency, and difficulties in audio-video alignment, laying a solid data foundation for building next-generation film and television content generation systems.
数据集概述
CineDance-1M 是一个大规模、开放研究的文本到音频-视频 (T2AV) 数据集,专为多镜头、长格式的联合音视频生成而设计。
核心特征
- 规模:包含 100 万(1M)个精心策划的序列。
- 时长:平均时长 92.8 秒(长序列格式)。
- 镜头数:平均每个视频包含 24.2 个连续镜头(多镜头)。
- 分辨率:最低分辨率为 1080p,保证高质量画质。
- 音频:包含原生音频,并配有结构化的音频标注。
- 标注:提供面向两种模态(音频和视频)的分层结构化字幕。
数据构建流程
数据集通过一个严格的三阶段策划管线生成:
- 多样化来源与全面清洗。
- 基于电影理论的叙事解析。
- 分层双模态字幕生成。
与其他数据集对比
CineDance-1M 是目前唯一达到百万级规模,同时具备以下特点的数据集:1080p 分辨率、长序列多镜头结构、原生音频以及结构化的音视频标注。
配套基准:CineBench
- 内容:包含 1,000 个测试用例,按主题/风格、时长、镜头数和生成难度分层。
- 时长范围:覆盖 10 秒(2-3 镜头)、30 秒(4-9 镜头)和前瞻性的 60 秒(10-20 镜头)。
- 评估维度:采用六维、与人类对齐的指标体系,包括:视频质量、音频质量、音画同步、提示词对齐、叙事连贯性和镜头结构响应。
配套模型:CineDance
基于 LTX-2.3 改造,是用于多镜头长序列音视频生成的稳健开源基线模型,具备镜头过渡、主题与环境一致性保持及结构化提示响应能力。
- 1CineDance: Towards Next-Generation Multi-Shot Long-Form Cinematic Audio-Video Generation上海交通大学; 电子科技大学; 浙江大学; 东京大学; 南洋理工大学 · 2026年


