Realmbird/gsm8k-qwen2.5-7b-L20-activations
收藏资源简介:
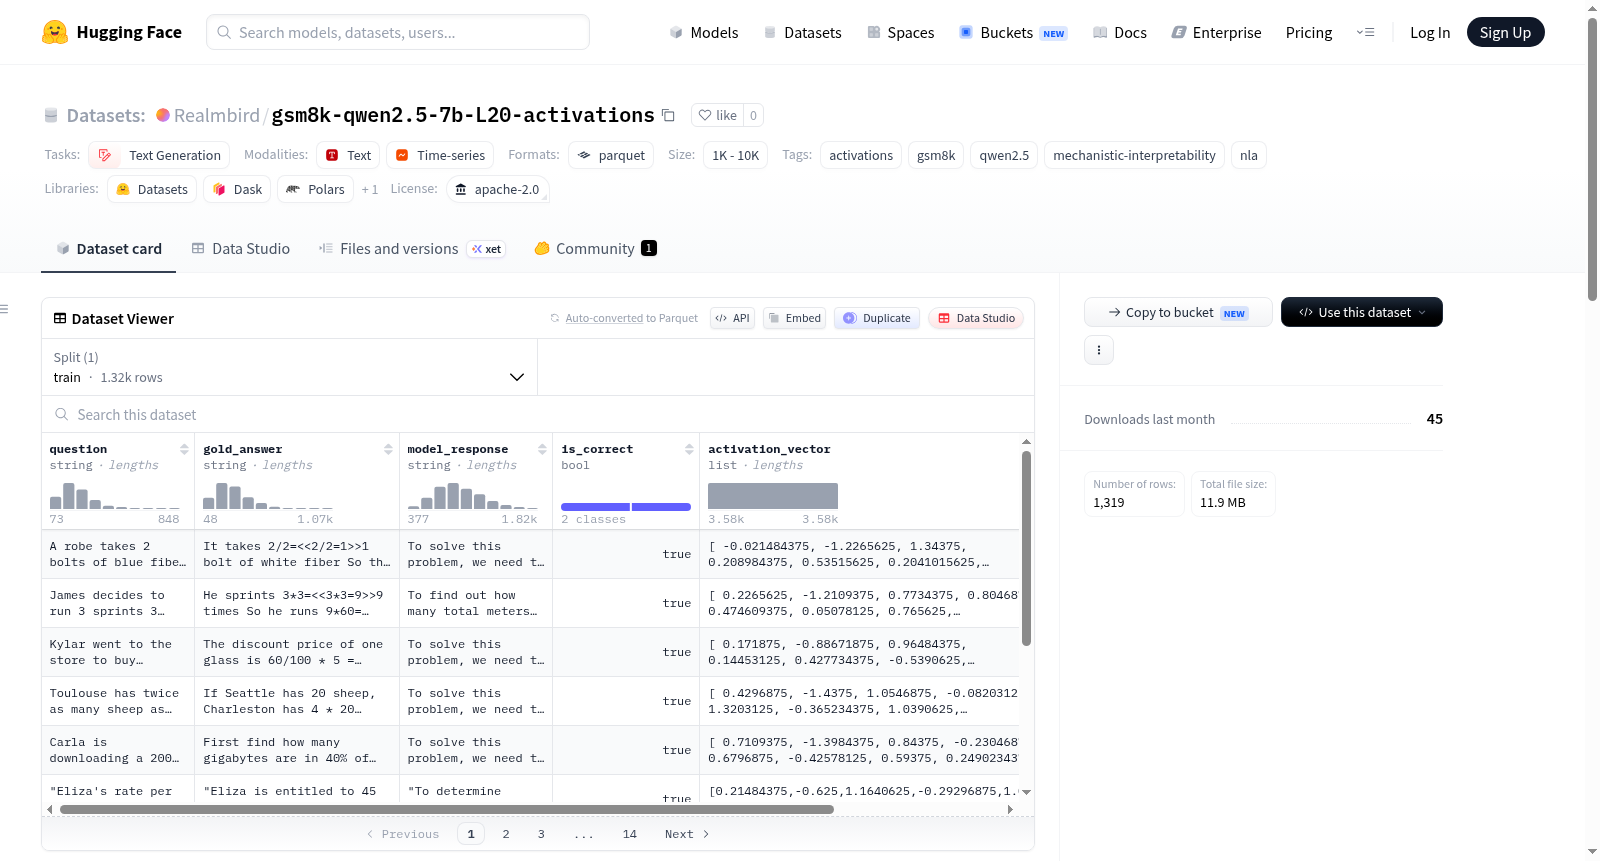
该数据集是从Qwen/Qwen2.5-7B-Instruct模型第20层(共28层)提取的残差流激活数据,针对GSM8K测试集的1319个示例,聚焦于输入提示的最后一个令牌。数据集根据模型回答是否正确分为两个文件:correct.parquet(708行,模型答案与标准答案匹配的示例)和incorrect.parquet(611行,模型答案不匹配的示例)。每行数据包含以下列:问题文本(GSM8K问题)、标准答案(包含真实思维链和答案)、模型响应(Qwen2.5-7B-Instruct的贪婪生成结果)、正确性标志(布尔值,表示模型答案是否与标准答案一致)、激活向量(长度为3584的float32列表,表示第20层残差流在最后一个提示令牌处的激活状态)和示例索引(在GSM8K测试集中的索引)。提取细节包括:模型为Qwen/Qwen2.5-7B-Instruct,层为20(0索引,即第20个transformer块后的残差流输出),位置为输入提示的最后一个令牌(生成开始前),数据类型为float32,模型维度为3584,解码方式为贪婪解码。数据集旨在与自然语言自编码器检查点配对使用,用于解码模型在GSM8K数学推理问题上正确与错误推理时第20层残差流的表示。
This dataset consists of residual stream activation data extracted from layer 20 (out of 28 total layers) of the Qwen/Qwen2.5-7B-Instruct model, covering 1319 examples from the GSM8K test set, with a focus on the last token of the input prompt. The dataset is split into two files based on whether the model's answer is correct: correct.parquet (708 rows, containing examples where the model's answer matches the ground-truth one) and incorrect.parquet (611 rows, containing examples where the model's answer does not match the ground-truth one). Each row contains the following columns: question text (GSM8K problem), ground-truth answer (contains the full Chain-of-Thought (CoT) and final answer), model response (greedy generation output from Qwen/Qwen2.5-7B-Instruct), correctness flag (a boolean value indicating whether the model's answer matches the ground-truth answer), activation vector (a float32 list of length 3584 representing the activation state of the 20th-layer residual stream at the last prompt token), and example index (the index within the GSM8K test set). Extraction details are as follows: the model is Qwen/Qwen2.5-7B-Instruct, the layer is 20 (0-indexed, i.e., the residual stream output after the 20th transformer block), the position is the last token of the input prompt (right before the start of generation), the data type is float32, the model dimension is 3584, and the decoding strategy is greedy decoding. This dataset is designed to be used in conjunction with natural language autoencoder checkpoints for decoding the residual stream representations of the model during correct and incorrect mathematical reasoning on GSM8K math problems.