eval-whisper-large-v3-multimed-hard-20260408-1932
收藏资源简介:
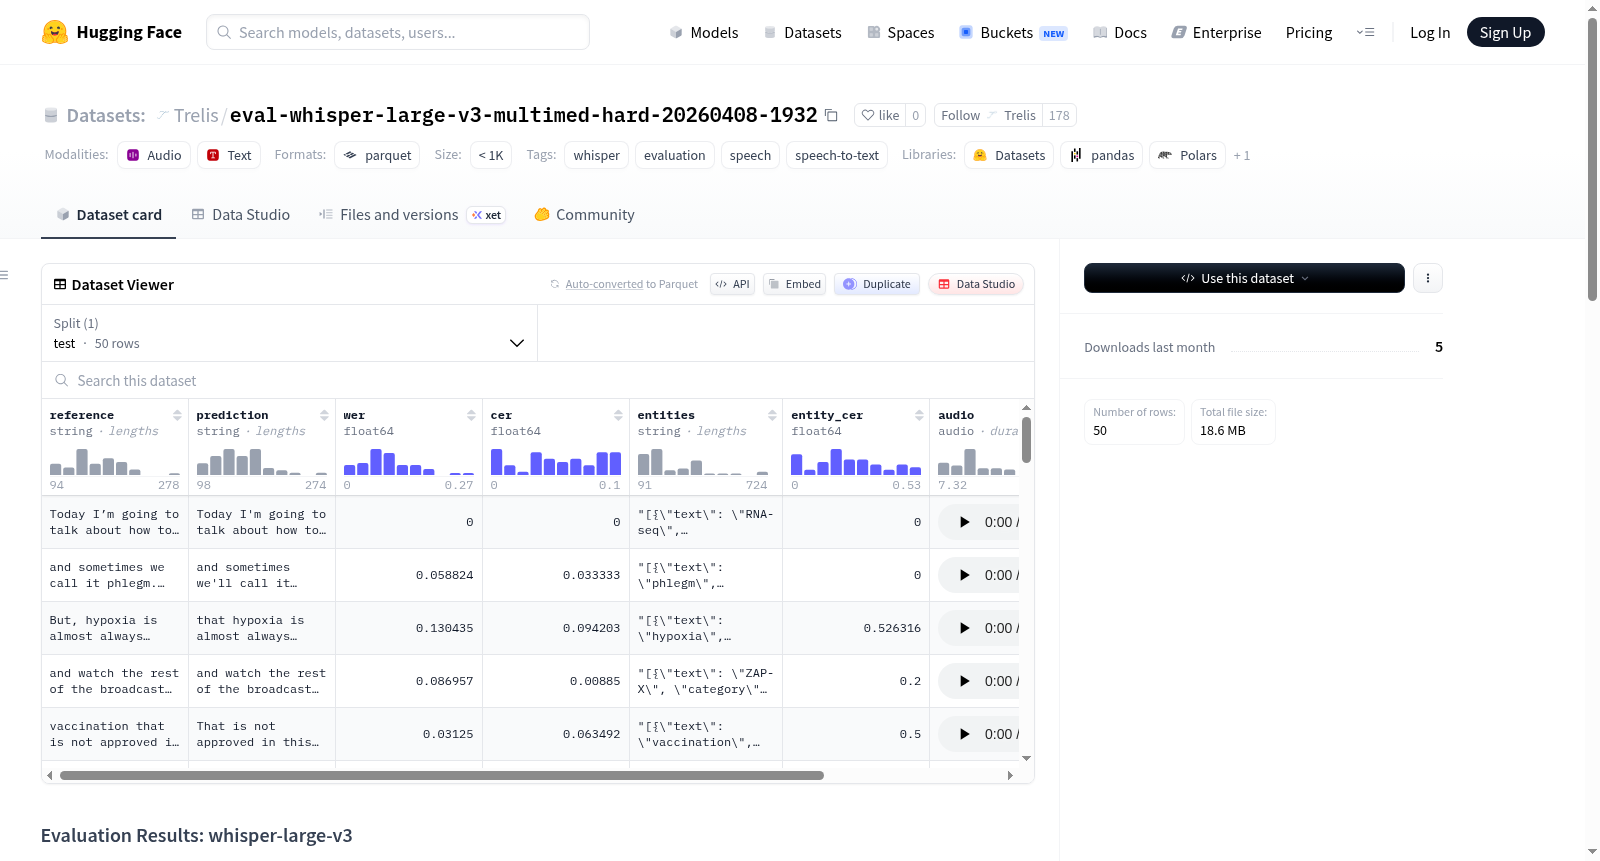
该数据集包含 Whisper 模型(whisper-large-v3)在特定评估数据集上的评测结果。数据集提供了音频样本(如果可用)、真实转录文本、模型预测文本、词错误率(WER)和字符错误率(CER)等字段。此外,还包含实体标注(如解剖学、生物标志物、条件、药物、组织和程序等类别)及相应的实体字符错误率(Entity CER)。评测结果显示,模型在整体字符错误率为5.15%,词错误率为8.54%,但在不同实体类别上的表现差异较大,如解剖学和组织类别的错误率较高。该数据集适用于评估语音识别模型在医学和组织相关术语上的性能。
This dataset contains the evaluation results of the Whisper model (whisper-large-v3) on a specific evaluation dataset. It provides fields including audio samples (if available), ground truth transcriptions, model predictions, Word Error Rate (WER) and Character Error Rate (CER). In addition, it includes entity annotations covering categories such as anatomy, biomarkers, conditions, drugs, tissues and procedures, as well as the corresponding Entity Character Error Rate (Entity CER). The evaluation results show that the model achieves an overall Character Error Rate of 5.15% and a Word Error Rate of 8.54%, yet there is a significant performance gap across different entity categories, with relatively higher error rates observed for the anatomy and tissue categories. This dataset is applicable for evaluating the performance of speech recognition models on medical and tissue-related terminology.