nrl-ai/vn-spell-correction-train
收藏资源简介:
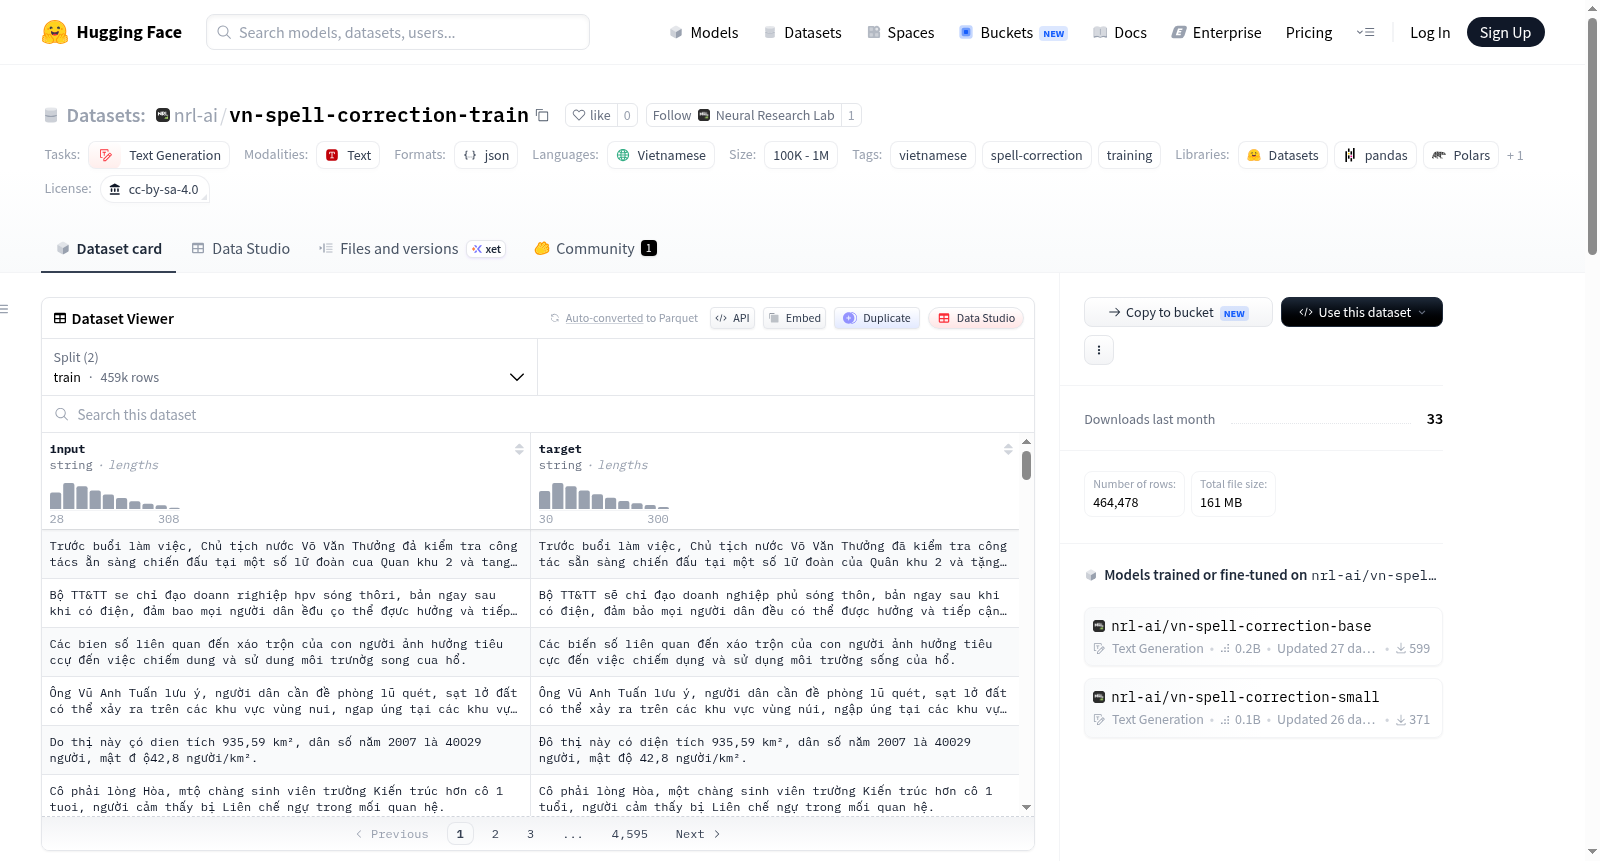
该数据集是一个越南语拼写校正训练数据集,包含459,478对(噪声,干净)越南语训练对,用于微调序列到序列的拼写校正模型。数据集的干净文本来自越南语维基百科和越南语新闻,噪声通过nom-vn库合成,包括轻度噪声、Telex输入法错误噪声和重度噪声三种预设。拼写校正任务涵盖音调恢复、键盘输入错误和OCR字符替换等。数据集格式为JSONL,包含训练集和验证集。许可证为CC-BY-SA-4.0。
This dataset is a Vietnamese spell-correction training dataset containing 459,478 (noisy, clean) Vietnamese training pairs for fine-tuning a seq2seq spell-correction model. The clean side of the dataset is sourced from Vietnamese Wikipedia and Vietnamese news, while the noisy side is synthetically generated using the nom-vn library with three noise presets: light noise, Telex typo noise, and heavy noise. The spell-correction task includes diacritic restoration, keyboard typos, and OCR-style character substitutions. The dataset is formatted in JSONL and includes train and validation splits. The license is CC-BY-SA-4.0.