EgoStandard
收藏资源简介:
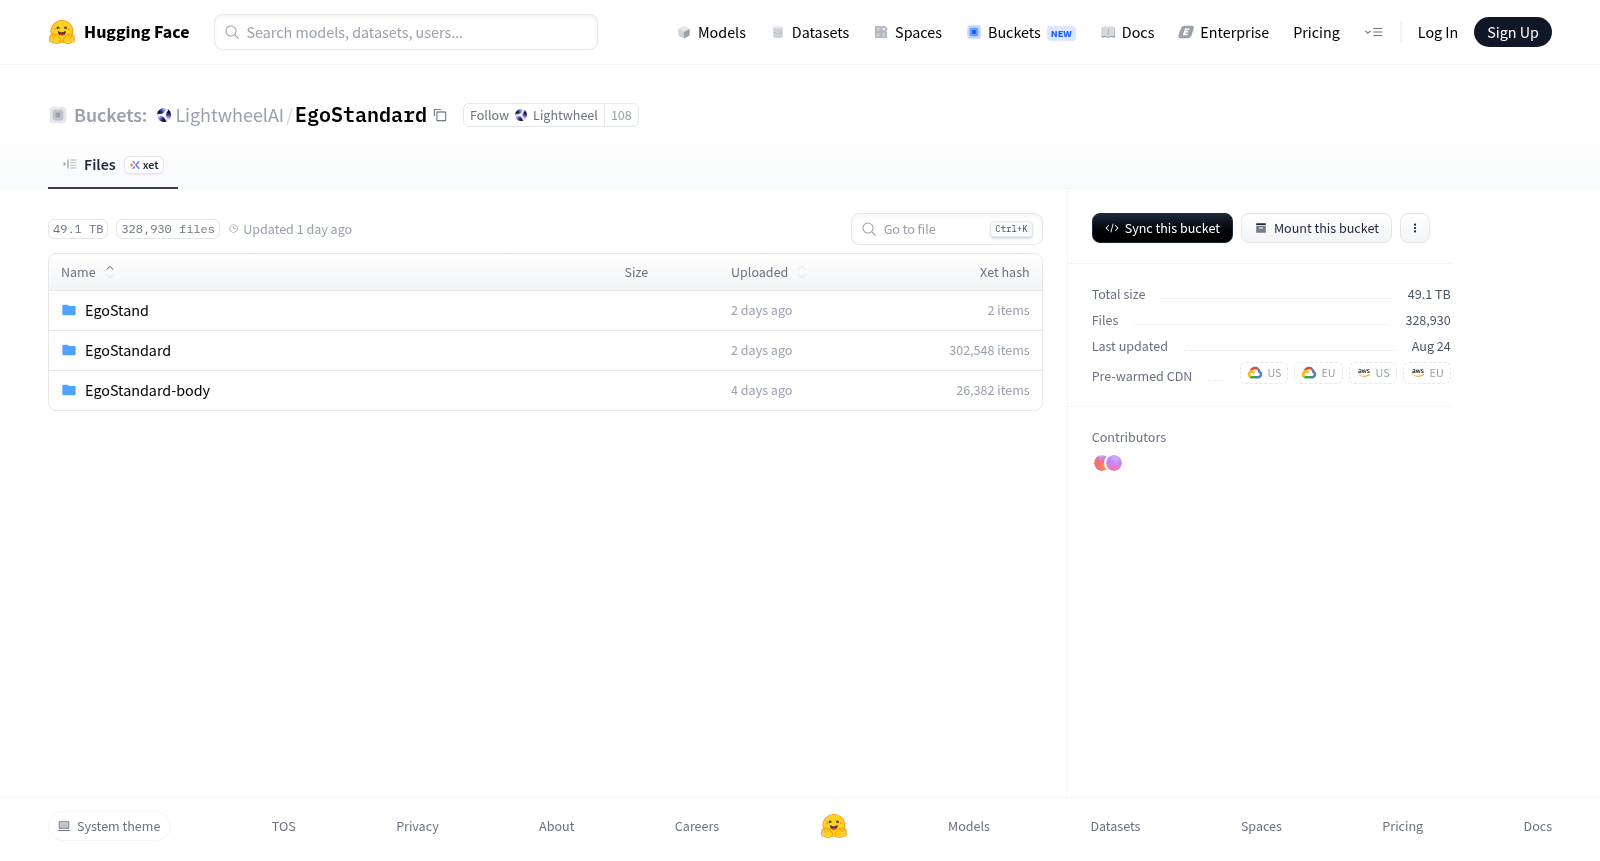
EgoStandard is a large-scale egocentric human demonstration dataset developed by Lightwheel as part of the EgoSuite-Open100K collection, designed for Physical AI, embodied intelligence, robotics learning, first-person vision, and multimodal model training. The dataset provides approximately 90,000 planned hours of head-mounted first-person video paired with synchronized 3D hand pose annotations across diverse real-world tasks and environments. It consists of two major subsets: EgoStand, containing approximately 80,000 hours of head-view video with 3D hand pose annotations, and EgoStand-body, containing approximately 10,000 hours with both 3D hand pose and full-body pose annotations. Wrist-view video is not included in EgoStandard. The dataset also provides temporal event-level semantic annotations as an additional annotation layer, while LeRobot and MCAP representations correspond to alternative formats of the same recorded episodes rather than additional data. EgoStandard is intended to support research and development in egocentric activity understanding, human-object interaction, imitation learning, robot manipulation, Vision-Language-Action models, world models, embodied AI, and Physical AI systems that learn from large-scale human demonstrations in real-world environments.
EgoStandard is a large-scale egocentric human demonstration dataset developed by Lightwheel as part of the EgoSuite-Open100K collection, designed for Physical AI, embodied intelligence, robotics learning, first-person vision, and multimodal model training. The dataset provides approximately 90,000 planned hours of head-mounted first-person video paired with synchronized 3D hand pose annotations across diverse real-world tasks and environments. It consists of two major subsets: EgoStand, containing approximately 80,000 hours of head-view video with 3D hand pose annotations, and EgoStand-body, containing approximately 10,000 hours with both 3D hand pose and full-body pose annotations. Wrist-view video is not included in EgoStandard. The dataset also provides temporal event-level semantic annotations as an additional annotation layer, while LeRobot and MCAP representations correspond to alternative formats of the same recorded episodes rather than additional data. EgoStandard is intended to support research and development in egocentric activity understanding, human-object interaction, imitation learning, robot manipulation, Vision-Language-Action models, world models, embodied AI, and Physical AI systems that learn from large-scale human demonstrations in real-world environments.