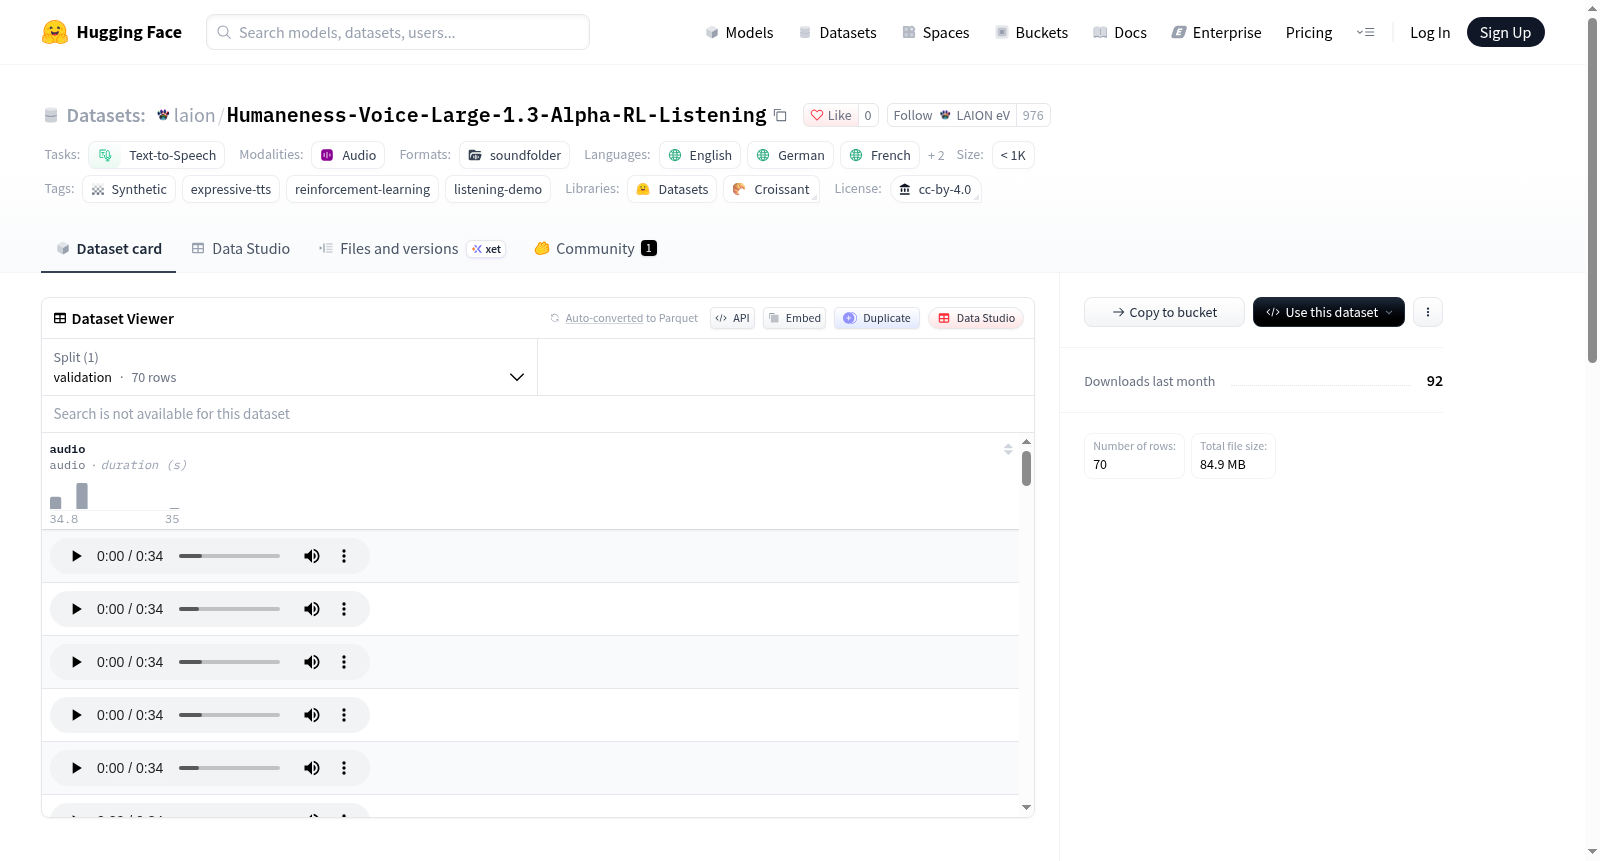
Humaneness-Voice-Large-1.3-Alpha-RL-Listening
收藏资源简介:
该数据集名为 Humaneness Voice Large1.3 Alpha: matched final-RL listening comparison,是一个面向表达性文本转语音与强化学习监听对比的合成语音数据集。采用 CC BY 4.0 许可,语言覆盖英语、德语、法语、荷兰语和西班牙语,任务类别为 text-to-speech,标签包括 synthetic、expressive-tts、reinforcement-learning 和 listening-demo。核心内容是来自已完成训练、rank 为 128 的 RL adapter 在已发布的最终 Large1.3 SFT checkpoint(step 9,799)上生成的 70 个新输出,这些输出不是 smoke 或中间结果。它们对应 35 个既有 scene/language 案例,每个案例分别包含使用和不使用同一独立输入说话人参考的条件,因此形成成对比较。所有单词、指导提示、随机种子、请求帧数和参考 codec 数组均与既有公开根页面对比完全一致。每个条件仅保留一个固定 take,未使用 best-of-N、重试、音频编辑或时间拉伸。旧 1.2/1.3 SFT 输出保留在原始仓库中,未被修改。推理设置方面,公开推理保留基线部署采样器:BF16 基础模型、未合并的 FP32 adapter 残差、temperature 1、top-p 0.95、top-k 50;RL 训练使用 FP32 采样与回放、temperature 0.7 和完整类别支持,二者差异是有意记录而非隐藏。奖励由三部分组成:33% 为 Humaneness EARS Medium Content Enjoyment/10,33% 为匹配两个固定源音频情绪强度(缩放 4 后按 1−MSE 计算),34% 为 genuineness/6;采用 VESPO 序列权重、组内奖励分量分别归一化以及 KL/SFT anchoring,按 UID 划分参考/无参考组,并保持真实/Gemini 来源均衡及五语言来源分层。这些属于学习到的代理指标,并非人类 MOS,也不保证输出改善。数据文件包括 audio/ 中可单独流式播放的 128 kbps 单声道 MP3;predictions.tar 打包这些 MP3、每个 80ms 帧的全部 12 个 MOSS-v2 codec 索引以及完整 JSON provenance;TASKS.json 与 predictions.json 保留精确输入、原始种子、checkpoint 身份、adapter SHA256、请求/实际时长和截断标记;metrics.json 保留旧 1.3SFT 与新 RL MP3 的完整 192-head EARS 输出及多语言 Parakeet ASR。未过滤摘要包含每个 take。超过 30 秒的片段使用均衡、不重叠的 judge 窗口覆盖完整片段,保留 duration-weighted raw-head 平均值及所有逐窗口分数;不丢弃尾部,该标注聚合不编辑 MP3,窗口代理分数不一定等于假设的整段评分。1.2 未被重新评分。该数据集定位为脚本化监听/开发比较,而非认证的 held-out benchmark;不声称这些场景具备 ground-truth 情绪强度匹配或认证说话人身份。说话人参考沿用先前监听数据集中已署名的独立公开合成 Gemini 话语,最终来自 laion/german-english-voice-acting-challenges,但参考音频未在此重新发布。新生成音频和元数据以 CC BY 4.0、LAION、2026 发布。该 adapter/checkpoint 仍是单独标识的实验性 RL 结果,此发布不替代 SFT 基础模型,也不重标记旧 SFT 音频。相关基础模型为 laion/Humaneness-Voice-Large-1.3-Alpha,另有 Listening Space。训练过程中完成尝试组数为 1500,成功优化器更新为 1452。
The dataset is named Humaneness Voice Large1.3 Alpha: matched final-RL listening comparison. It is a synthetic speech dataset for expressive text-to-speech and reinforcement-learning listening comparison, licensed under CC BY 4.0. It covers English, German, French, Dutch, and Spanish, with task category text-to-speech and tags synthetic, expressive-tts, reinforcement-learning, and listening-demo. The core content consists of 70 new outputs generated by a fully trained rank-128 RL adapter on the released final Large1.3 SFT checkpoint (step 9,799); these are not smoke or intermediate results. They correspond to 35 existing scene/language cases, each with paired conditions using and not using the same independent input speaker reference. All words, instruction prompts, random seeds, requested frame counts, and reference codec arrays are exactly matched to the existing public root-page comparison. Only one fixed take is retained per condition; no best-of-N, retries, audio editing, or time stretching were used. Old 1.2/1.3 SFT outputs remain in the original repository and are unmodified. For inference settings, public inference retains the baseline deployment sampler: BF16 base model, unmerged FP32 adapter residual, temperature 1, top-p 0.95, top-k 50; RL training used FP32 sampling and replay, temperature 0.7, and full category support, with the difference intentionally recorded rather than hidden. The reward has three parts: 33% Humaneness EARS Medium Content Enjoyment/10, 33% matching two fixed source-audio emotion intensities (scaled by 4 and computed as 1−MSE), and 34% genuineness/6; it uses VESPO sequence weights, per-group normalization of reward components, and KL/SFT anchoring, splits reference/no-reference groups by UID, and keeps real/Gemini source balance and five-language source stratification. These are learned proxy metrics, not human MOS, and do not guarantee improved outputs. Data files include individually streamable 128 kbps mono MP3s under audio/; predictions.tar packages these MP3s, all 12 MOSS-v2 codec indices per 80 ms frame, and full JSON provenance; TASKS.json and predictions.json preserve exact inputs, raw seeds, checkpoint identity, adapter SHA256, requested/actual durations, and truncation flags; metrics.json preserves full 192-head EARS outputs for old 1.3SFT and new RL MP3s plus multilingual Parakeet ASR. The unfiltered summary includes every take. Segments over 30 seconds are covered by balanced, non-overlapping judge windows, preserving duration-weighted raw-head averages and all per-window scores; tails are not discarded, this annotation aggregation does not edit MP3s, and window proxy scores may not equal a hypothetical whole-segment rating. 1.2 was not re-scored. The dataset is positioned as a scripted listening/development comparison, not a certified held-out benchmark; it does not claim ground-truth emotion intensity matching or certified speaker identity for these scenes. Speaker references reuse credited independent public synthetic Gemini utterances from previous listening datasets, ultimately from laion/german-english-voice-acting-challenges, but the reference audio is not republished here. New generated audio and metadata are released under CC BY 4.0, LAION, 2026. The adapter/checkpoint remains a separately identified experimental RL result; this release does not replace the SFT base model or relabel old SFT audio. The related base model is laion/Humaneness-Voice-Large-1.3-Alpha, and there is also a Listening Space. During training, 1500 attempted groups were completed and 1452 successful optimizer updates were made.
Humaneness Voice Large1.3 Alpha: matched final-RL listening comparison
基本信息
| 项目 | 内容 |
|---|---|
| 数据集页面 | https://huggingface.co/datasets/laion/Humaneness-Voice-Large-1.3-Alpha-RL-Listening |
| 许可证 | cc-by-4.0 |
| 语言 | en, de, fr, nl, es |
| 任务类别 | text-to-speech |
| 标签 | synthetic, expressive-tts, reinforcement-learning, listening-demo |
数据集概述
- 包含70个新输出,来自已完成的 rank128 RL adapter,运行于已发布的最终 Large1.3 SFT checkpoint(step 9,799)。
- 这些输出不是 smoke 或 intermediate outputs。
- 包含35个现有场景/语言案例,每个案例均包含带与不带同一单独输入说话人参考的版本。
- 先前的1.2/1.3 SFT 输出在其原始仓库中保持不变。
- 所有 words、directing prompts、seeds、requested frames 和 reference codec arrays 与现有公开 root-page comparison 完全匹配。
- 每个条件仅一个 fixed take。
- 无 best-of-N、重试、音频编辑或 time-stretch。
推理与训练配置
- 公开推理保留 baseline deployment sampler:BF16 base、unmerged FP32 adapter residuals、temperature 1、top-p 0.95、top-k 50。
- RL 训练使用 FP32 sampling 和 replay,temperature 0.7,并带 full categorical support。
- 该差异是有意且被记录的,并非隐藏于相同策略声明之后。
奖励与训练目标
- 奖励组成:33% Humaneness EARS Medium Content Enjoyment/10。
- 奖励组成:33% matching TWO fixed source-audio emotion intensities(1−MSE after scaling by 4)。
- 奖励组成:34% genuineness/6。
- 使用 VESPO sequence weights 和 separate within-group reward-component normalization,并带 KL/SFT anchoring。
- G8,针对每个 UID 使用 separate reference/no-reference groups。
- 使用 equal real/Gemini 和 balanced five-language source strata。
- 这些是 learned proxies,不是 human MOS,也不保证输出改进。
文件与元数据
audio/包含可单独流式播放的 128kbps mono MP3s。predictions.tar打包这些 MP3s、每80ms帧的全部12个 MOSS-v2 codec indices 和完整 JSON provenance。TASKS.json和predictions.json保留 exact inputs、original seeds、checkpoint identity、adapter SHA256、requested/actual timing 和 truncation flags。metrics.json保留 full 192-head EARS outputs 以及针对旧 1.3SFT 和新 RL MP3s 的 multilingual Parakeet ASR。- 未过滤摘要包含每一个 take。
- 超过30秒的 clips 使用 balanced non-overlapping judge windows,覆盖完整 clip,并保留 duration-weighted raw-head averages 和所有 per-window scores。
- 不丢弃 tail;该 annotation aggregation 不编辑 MP3。
- Windowed proxy scores 不必等于假设的 whole-clip rating。
- 1.2 在此不重新评分。
评价性质与限制
- 这是 scripted listening/development comparison,不是 certified held-out benchmark。
- 在这些场景上不提出 ground-truth emotion-intensity match 或 certified speaker identity claim。
- Speaker references 是先前 listening dataset 中已归属的相同单独公开 synthetic Gemini utterances,最终来自 laion/german-english-voice-acting-challenges。
- References 不在此重新发布。
- 新生成的音频和元数据:CC BY 4.0, LAION, 2026。
- Adapter/checkpoint 仍是被单独标识的实验性 RL 结果;此发布不替代 SFT base model,也不重新标记旧 SFT audio。
相关链接
- Base model: https://huggingface.co/laion/Humaneness-Voice-Large-1.3-Alpha
- Listening Space: https://laion-humaneness-voice-large-1-2-alpha-listening.static.hf.space/
- 数据集页面: https://huggingface.co/datasets/laion/Humaneness-Voice-Large-1.3-Alpha-RL-Listening
训练统计
- Completed attempted groups: 1500
- Successful optimizer updates: 1452