shaswatamitra/falcon-yara-rule-decoys
收藏资源简介:
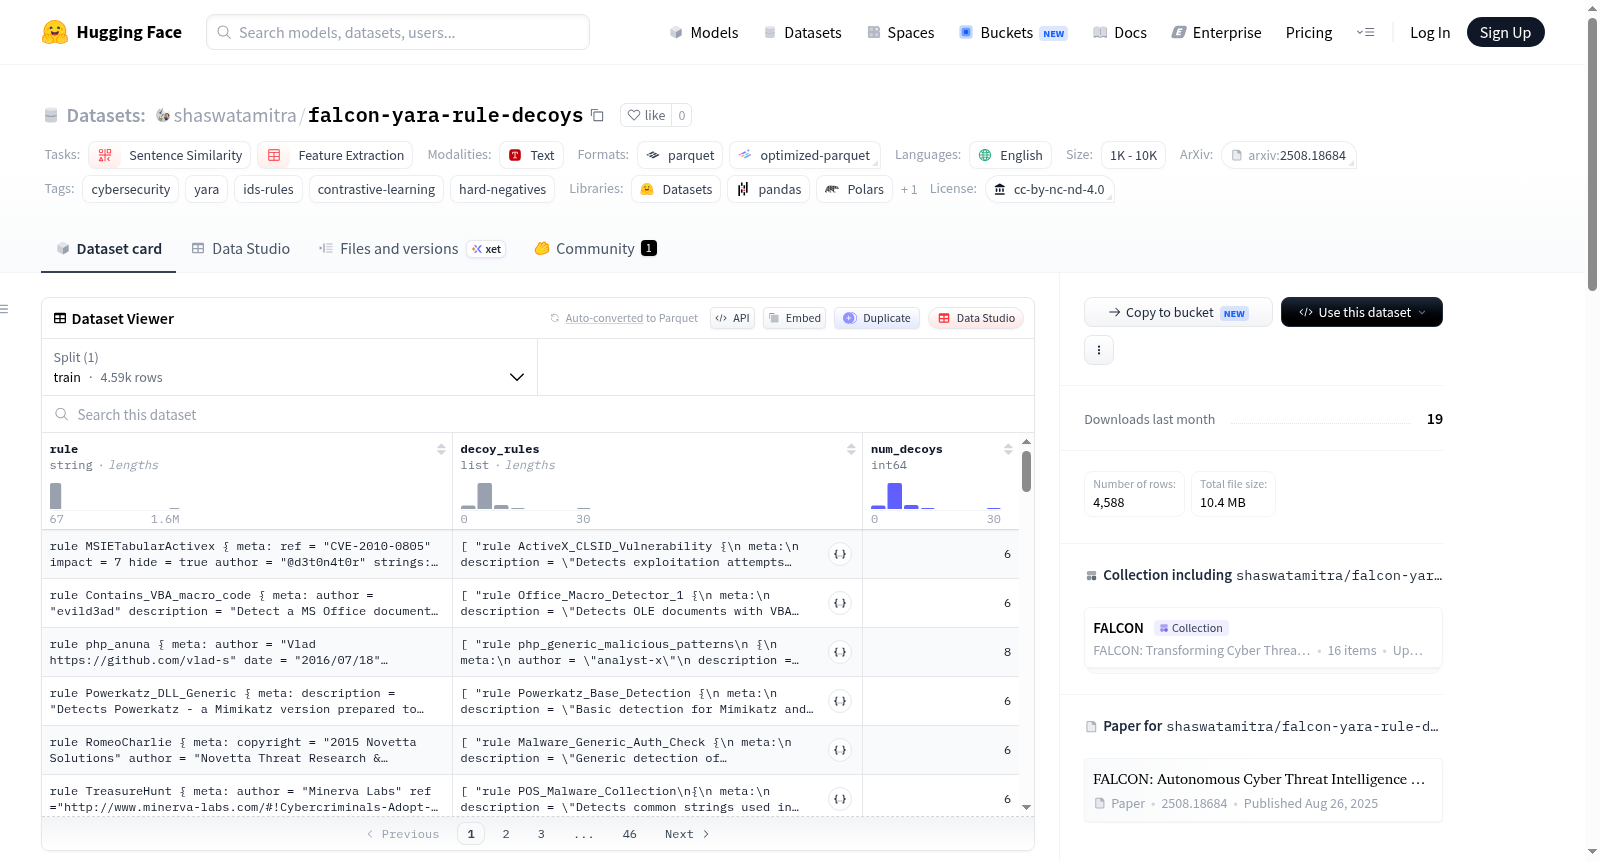
FALCON YARA规则与诱饵规则数据集包含真实YARA规则与LLM生成的相似规则(称为“诱饵”或“废弃”规则)的配对数据。该数据集旨在作为对比句子编码器微调中的硬负样本,以及用于规则与相似规则检索的鲁棒性基准。数据集包括4,588个锚点规则和总计25,875个诱饵规则(平均每个锚点5.64个,范围0-30)。每个数据行包含真实YARA规则的完整源代码、LLM生成的相似规则列表(每个锚点3-8个)以及诱饵规则数量。锚点规则来自与CTI ↔ Rule数据集相同的语料库,LLM被提示生成表面相似(相同句法骨架、类似消息标记、可比结构)但检测逻辑不同的规则,以确保它们行为上不可互换。预期用途包括对比学习中的硬负样本增强和检索鲁棒性测试,以评估模型在给定CTI时区分真实规则与相似规则的能力。
The FALCON YARA Rule ↔ Decoy-Rule Dataset consists of ground-truth YARA rules paired with LLM-generated look-alike rules (referred to as decoy or deprecated rules). It is intended as hard negatives for contrastive sentence-encoder fine-tuning and as a robustness benchmark for rule-versus-look-alike retrieval. The dataset includes 4,588 anchor rules and 25,875 total decoys (mean 5.64 per anchor, range 0-30). Each row contains the full source of a ground-truth YARA rule, a list of LLM-generated look-alike rules (3-8 per anchor), and the number of decoys. Anchor rules are drawn from the same corpus as the CTI ↔ Rule dataset, and an LLM is prompted to produce rules that look similar at the surface level (same syntactic skeleton, similar message tokens, comparable structure) but differ in detection logic so they are not behaviourally interchangeable. Intended uses include hard-negative augmentation for contrastive learning and retrieval-robustness benchmarking to assess a models ability to distinguish real rules from look-alikes given the CTI they justify.