Molmo2-CapEval
收藏资源简介:
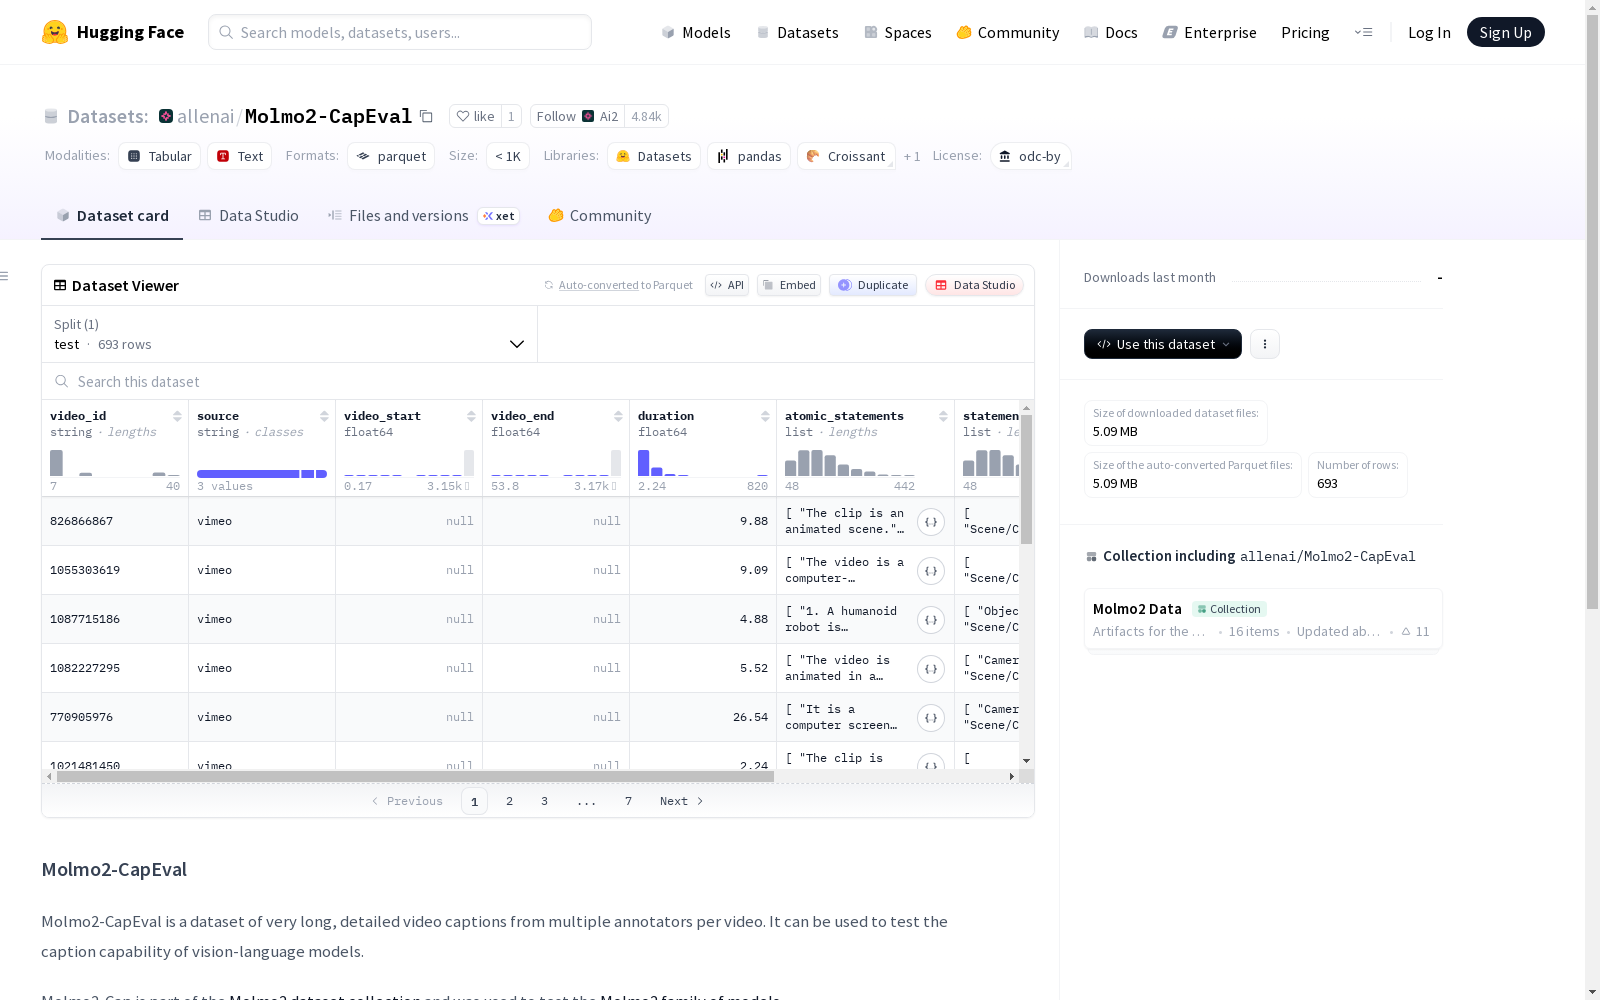
Molmo2-CapEval是一个包含多个标注者为每个视频提供的非常详细的长视频字幕的数据集,可用于测试视觉语言模型生成字幕的能力。视频来自Vimeo、Ego4D和BDD100K,以视频ID形式存储,需单独下载。数据集包含视频ID、来源、视频开始和结束时间、持续时间、原子语句、语句类别和聚合字幕等特征。测试集包含693个示例。数据集遵循ODC-BY许可,并包含基于GPT-4.1和GPT-5生成的文本字幕。
Molmo2-CapEval is a dataset providing detailed long-form video captions annotated by multiple annotators for each video, which is designed to test the caption generation capabilities of vision-language models. The videos come from Vimeo, Ego4D and BDD100K, are stored in the form of video IDs and require separate downloading. The dataset includes features such as video ID, source, video start and end timestamps, duration, atomic statements, statement categories and aggregated captions. The test set contains 693 examples. The dataset follows the ODC-BY license and includes textual captions generated based on GPT-4.1 and GPT-5.
Molmo2-CapEval 数据集概述
数据集基本信息
- 数据集名称:Molmo2-CapEval
- 发布者:allenai
- 许可证:ODC-BY
- 下载大小:5,091,174 字节
- 数据集大小:10,651,923 字节
- 数据拆分:仅包含一个“test”拆分,包含693个样本
数据集描述
Molmo2-CapEval 是一个包含非常长、详细视频描述的数据集,每个视频有多个标注者提供的描述。该数据集可用于测试视觉-语言模型的描述生成能力。它是 Molmo2 数据集集合的一部分,并用于测试 Molmo2 系列模型。
数据来源
视频来源于 Vimeo、Ego4D 和 BDD100K。数据集中仅存储视频ID,需要用户自行下载对应的视频文件。
数据格式与特征
数据集包含以下字段:
video_id(字符串):视频标识符。source(字符串):视频来源。video_start(浮点数):视频片段的起始时间。video_end(浮点数):视频片段的结束时间。duration(浮点数):视频片段的持续时间。atomic_statements(字符串列表):原子化描述语句。statement_categories(字符串列表):描述语句对应的类别。aggregated_caption(字符串):聚合后的视频描述。
相关资源链接
- 数据集集合页面:https://huggingface.co/collections/allenai/molmo2-data
- 模型集合页面:https://huggingface.co/collections/allenai/molmo2
- 论文:https://allenai.org/papers/molmo2
- 博客与视频:https://allenai.org/blog/molmo2
使用许可与注意事项
- 本数据集遵循 ODC-BY 许可证,旨在用于符合 Ai2 负责任使用指南的研究和教育目的。
- 数据集中的文本描述由 GPT-4.1 和 GPT-5 生成,受 OpenAI 使用条款约束。
- 部分数据内容基于仅限学术和非商业研究使用的第三方数据集创建。更多信息请参阅源归属文件。