M4-Instruct-Data
收藏资源简介:
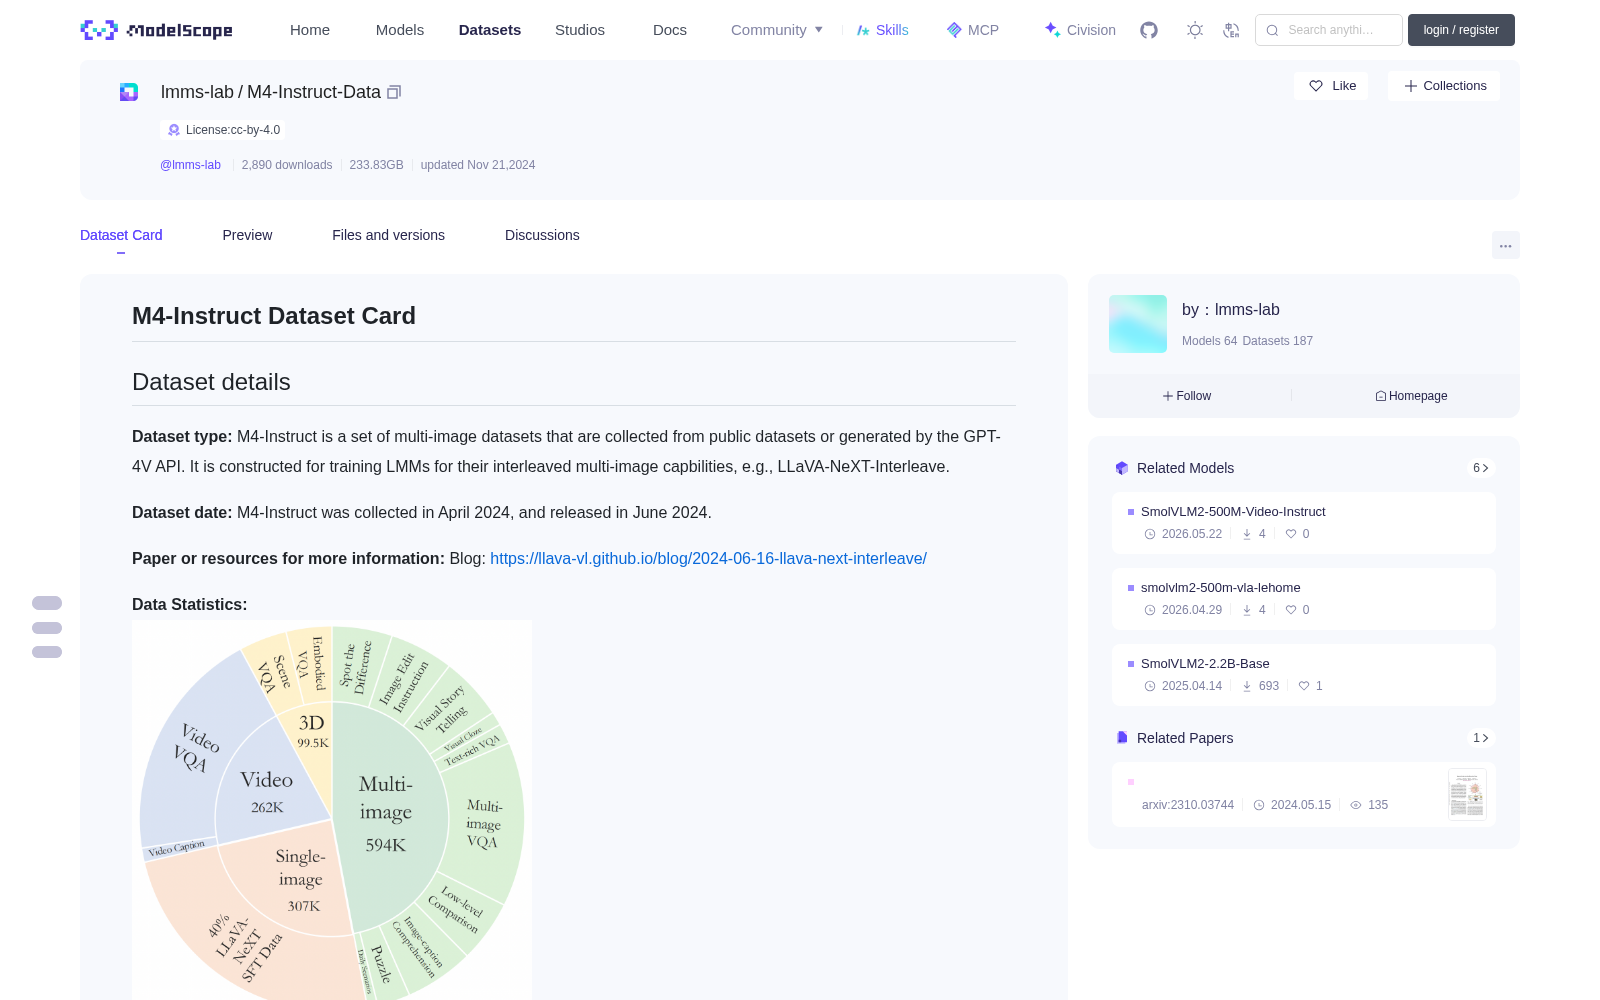
# M4-Instruct Dataset Card ## Dataset details **Dataset type:** M4-Instruct is a set of multi-image datasets that are collected from public datasets or generated by the GPT-4V API. It is constructed for training LMMs for their interleaved multi-image capbilities, e.g., LLaVA-NeXT-Interleave. **Dataset date:** M4-Instruct was collected in April 2024, and released in June 2024. **Paper or resources for more information:** Blog: https://llava-vl.github.io/blog/2024-06-16-llava-next-interleave/ **Data Statistics:** <img src="data-statistics.png" alt="isolated" width="400"/> Note that we only released the multi-image, multi-frame (video), and multi-view (3D) data of M4-Instruct in this repo. Please also download videos from [LLaVA-Hound](https://huggingface.co/datasets/ShareGPTVideo/train_video_and_instruction/tree/main/train_300k), and organize them according to their instructions. To reproduce LLaVA-NeXT-Interleave, you can complement the multi-patch (single-image) data by randomly sampling 307K of the stage-2 SFT data of [LLaVA-1.5](https://arxiv.org/pdf/2310.03744). **Data Content:** - json file: m4_instruct_annotations.json and m4_instruct_video.json - images: *.zip - For dreamsim_split.z01 and dreamsim_split.zip, please run "zip -s 0 dreamsim_split.zip --out dreamsim.zip" **License:** Creative Commons Attribution 4.0 International; and it should abide by the policy of OpenAI: https://openai.com/policies/terms-of-use **Where to send questions or comments about the model:** fliay@connect.ust.hk 1700012927@pku.edu.cn ## Intended use **Primary intended uses:** The primary use of M4-Instruct Data is research on large multimodal models and chatbots. **Primary intended users:** The primary intended users of the model are researchers and hobbyists in computer vision, natural language processing, machine learning, and artificial intelligence.
# M4-Instruct 数据集卡片 ## 数据集详情 **数据集类型:** M4-Instruct 是一套多图像数据集,其数据来源涵盖公开数据集,或通过 GPT-4V API 生成。本数据集专为训练大多模态模型(Large Multimodal Model, LMM)的交错式多图像处理能力而构建,例如 LLaVA-NeXT-Interleave。 **数据集采集与发布时间:** M4-Instruct 于2024年4月完成采集,并于2024年6月正式发布。 **更多信息参考资源:** 博客:https://llava-vl.github.io/blog/2024-06-16-llava-next-interleave/ **数据统计:** <img src="data-statistics.png" alt="isolated" width="400"/> 注:本仓库仅发布了 M4-Instruct 中的多图像、多帧(视频)及多视角(3D)数据。 请从 [LLaVA-Hound](https://huggingface.co/datasets/ShareGPTVideo/train_video_and_instruction/tree/main/train_300k) 下载视频资源,并按照配套指令进行整理。 若需复现 LLaVA-NeXT-Interleave,可通过随机采样 [LLaVA-1.5](https://arxiv.org/pdf/2310.03744) 的第二阶段监督微调(Supervised Fine-Tuning, SFT)数据中的307K条数据,以此补全多补丁(单图像)数据。 **数据内容:** - 标注文件:`m4_instruct_annotations.json` 与 `m4_instruct_video.json` - 图像文件:`*.zip` - 对于 `dreamsim_split.z01` 和 `dreamsim_split.zip`,请执行命令 `zip -s 0 dreamsim_split.zip --out dreamsim.zip` 进行分卷合并。 **许可协议:** 采用知识共享署名4.0国际许可协议(Creative Commons Attribution 4.0 International),同时需遵守 OpenAI 的使用条款:https://openai.com/policies/terms-of-use **数据集反馈与咨询方式:** fliay@connect.ust.hk 1700012927@pku.edu.cn ## 预期用途 **核心预期用途:** 本数据集的核心用途为开展大多模态模型与聊天机器人相关研究。 **核心目标用户:** 本数据集的目标用户为计算机视觉、自然语言处理、机器学习及人工智能领域的研究人员与爱好者。