SupraLabs/agentic-reasoning-trace-summaries-40k
收藏资源简介:
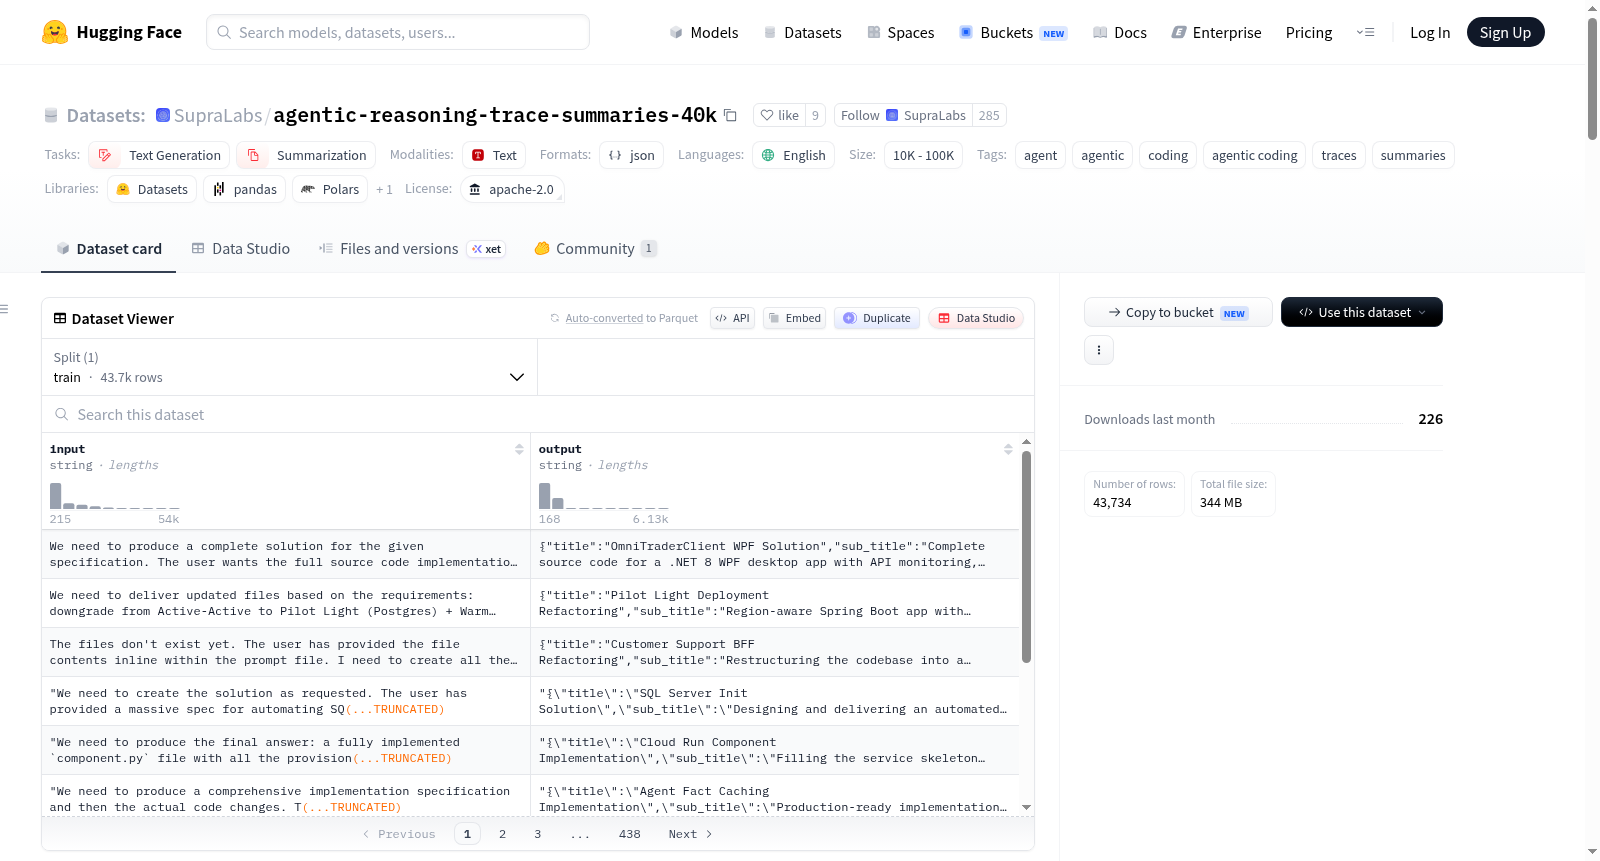
该数据集名为Agentic Summaries,是一个用于训练模型将冗长的推理或工作轨迹转换为简短结构化摘要的JSONL数据集。数据集包含43,734行数据,每行包含两个字段:input(冗长的推理或工作轨迹文本)和output(一个字符串形式的JSON摘要,包括title、sub_title、summary和cur_task四个字段)。摘要旨在模拟模型在工作过程中产生的进度更新,具有标题、副标题、简短摘要和当前任务的结构。数据行按从长到短排序,以确保长上下文示例优先。数据集适用于文本生成和摘要任务,专注于代理(agent)和编码(coding)相关领域,语言为英语。数据集经过完整验证,所有行均有效,且输出可解析为JSON对象。源轨迹可能包含代码、工具调用、实现笔记、数学计算、调试步骤等任务导向文本,目标输出保持紧凑和结构化,有助于训练模型生成清晰的进度摘要而非冗长的自由形式解释。数据集中故意包含了一些破损或极短的样本,以教导模型如何应对这些输入,建议不要移除这些样本。
This dataset, named Agentic Summaries, is a JSONL dataset designed to train models to convert long reasoning or work traces into short structured summaries. It contains 43,734 rows, each with two fields: input (a verbose reasoning or work trace text) and output (a JSON summary as a string, including title, sub_title, summary, and cur_task fields). The summary mimics the kind of progress update a model should produce while working, with a structured format of title, subtitle, short summary, and current task. Rows are ordered from longest to shortest to prioritize long-context examples. The dataset is suitable for text-generation and summarization tasks, focusing on agent and coding-related domains, and is in English. It has been fully validated, with all rows valid and outputs parsable as JSON objects. Source traces may include code, tool calls, implementation notes, math, debugging steps, and other task-oriented text, while target outputs remain compact and structured, helping train models to produce clean progress summaries instead of long free-form explanations. The dataset intentionally includes broken or extremely short samples to teach the model to react to such inputs, and it is recommended not to remove these samples.