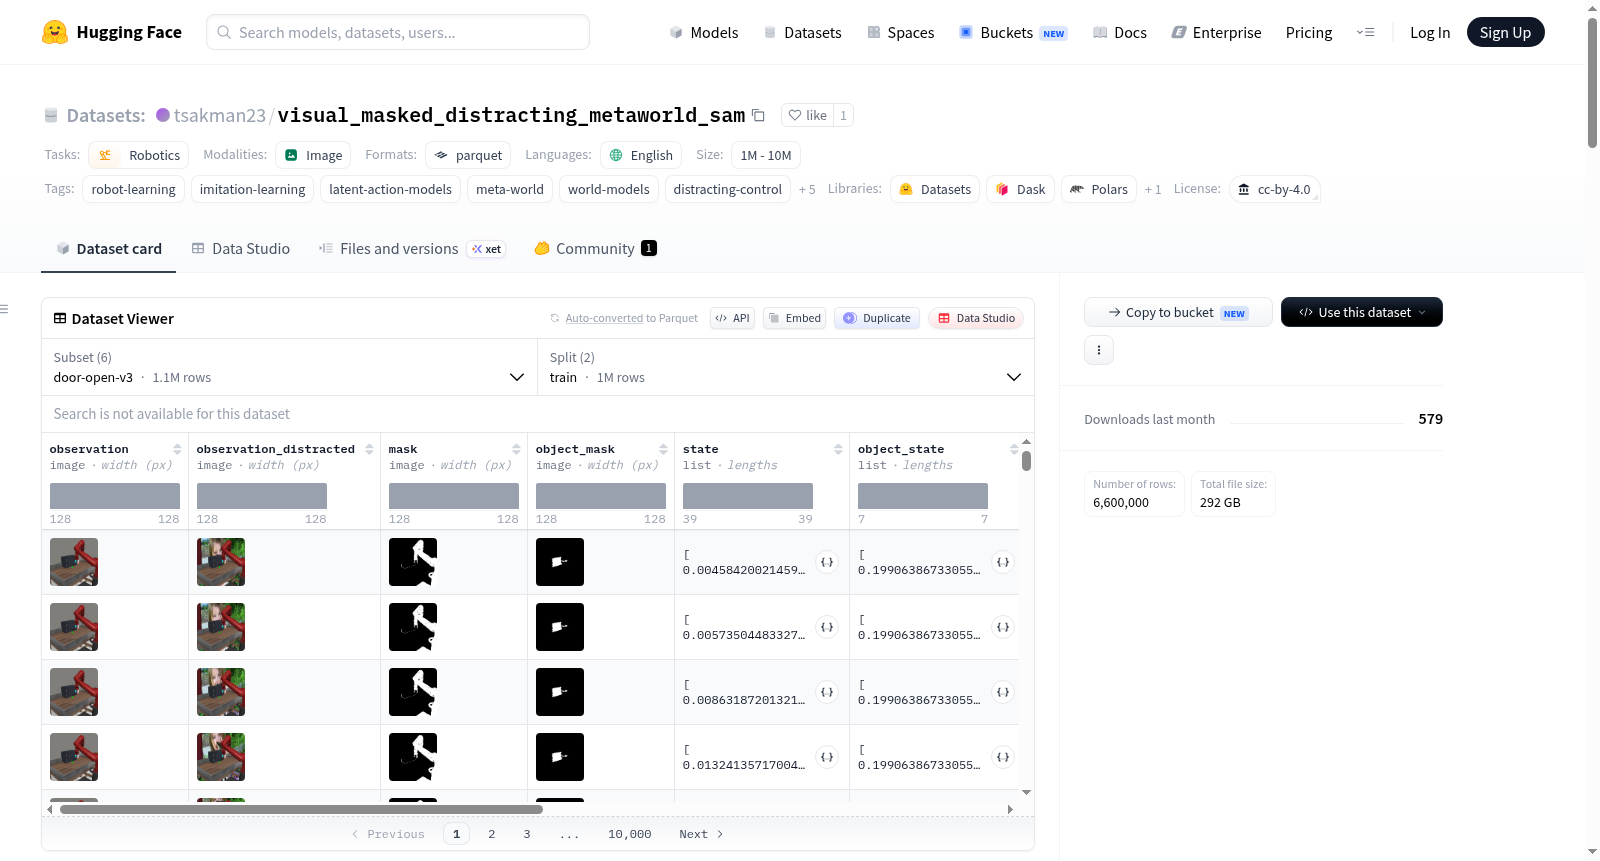
visual_masked_distracting_metaworld_sam
收藏资源简介:
该数据集是 Visual Masked Distracting Meta-World 的变体,包含由专家策略生成的 Meta-World 操作轨迹,并渲染了动态视频背景干扰。每个时间步提供 128×128 的 RGB 图像(无干扰帧和带有 DAVIS 视频背景的干扰帧)、ground-truth 代理和操作对象分割掩码(二值图,0/255)、以及由 Segment Anything Model (SAM) 预测的对应掩码。此外,还包含操作对象的世界坐标系姿态(7维:位置+四元数)、完整环境状态向量(39维)、专家动作(4维:dx, dy, dz, gripper)、奖励值以及终止/截断标志。数据集被组织为 6 个 Meta-World 任务配置:push-v3、sweep-into-v3、door-open-v3、handle-pull-v3、pick-place-v3、peg-insert-side-v3。每个任务提供 1,000,000 步训练集和 100,000 步测试集。该数据集旨在支持机器人操作中的对象感知学习,特别是在视觉干扰下,通过掩码区分代理、操作对象和背景,可用于训练和评估世界模型、潜在动作模型(如 IM-LAM 和 Foreground-MaskLAM),以及研究分割质量对模型鲁棒性的影响。数据集的 ground-truth 掩码来自 MuJoCo 模拟器分割渲染,预测掩码来自 SAM,背景帧来自 DAVIS 数据集。数据集采用 CC BY 4.0 许可证,但干扰帧部分受 DAVIS 研究使用限制。
This dataset is a variant of Visual Masked Distracting Meta-World, containing Meta-World manipulation trajectories generated by expert policies with dynamic video background distractions. Each timestep provides 128×128 RGB images (both non-distracting frames and distracting frames with DAVIS video backgrounds), ground-truth segmentation masks for the agent and manipulated objects (binary images with values 0/255), and corresponding masks predicted by the Segment Anything Model (SAM). Additionally, it includes the 7-DoF world-coordinate pose (position + quaternion) of the manipulated object, the full 39-dimensional environment state vector, 4-dimensional expert actions (dx, dy, dz, gripper), reward values, and termination/truncation flags. The dataset is organized into 6 Meta-World task configurations: push-v3, sweep-into-v3, door-open-v3, handle-pull-v3, pick-place-v3, and peg-insert-side-v3. Each task provides 1,000,000 steps for training and 100,000 steps for testing. The dataset is designed to support object-aware learning in robotic manipulation, especially under visual distractions, where masks help distinguish the agent, manipulated objects, and background. It can be used for training and evaluating world models, latent action models (e.g., IM-LAM and Foreground-MaskLAM), and studying the impact of segmentation quality on model robustness. The ground-truth masks are rendered via MuJoCos segmentation rendering, predicted masks come from SAM, and background frames are from the DAVIS dataset. The dataset is licensed under CC BY 4.0, with the distracting frames subject to DAVIS research use restrictions.
数据集概述
Visual Masked Distracting Meta-World (ground-truth + SAM masks) 是一个用于机器人操作研究的视觉数据集,由 Georgios Tsakoumakis 制作,相关论文为 Interaction-Masked Latent Action Models for Object-Aware Manipulation under Visual Distractors(伦敦帝国理工学院硕士论文)。数据集旨在为模仿学习、潜在动作模型和世界模型研究提供带有动态视频背景干扰的专家操作轨迹,并同时提供仿真器的精确分割掩码和 SAM 模型预测的分割掩码。
核心特点
- 动态干扰背景:场景背景为 DAVIS 视频片段,可模拟任务无关的动态视觉干扰。
- 双重掩码来源:每个时间步同时提供 ground-truth(仿真器精确分割) 与 SAM 预测分割,便于分析模型对分割质量的鲁棒性。
- 对象级信息:包含被操作对象的位姿(位置 + 四元数方向)。
- 规范化格式:数据遵循
(o_t, a_t, r_t, term_t, trunc_t)标准时间步结构,便于时序建模。
数据字段说明
每个示例为单时间步(t),字段详情如下:
| 字段 | 类型 | 形状/数据类型 | 描述 |
|---|---|---|---|
observation |
图像 | 128x128 RGB | 无干扰背景的原始帧。 |
observation_distracted |
图像 | 128x128 RGB | 叠加 DAVIS 视频背景的帧,用于干扰变体训练。 |
mask |
图像 | 128x128 L (0/255) | Ground-truth 智能体(机器人)分割掩码(255=机器人)。 |
object_mask |
图像 | 128x128 L (0/255) | Ground-truth 被操作对象分割掩码(255=对象)。 |
pred_mask |
图像 | 128x128 L (0/255) | SAM 预测的智能体分割掩码。 |
pred_object_mask |
图像 | 128x128 L (0/255) | SAM 预测的被操作对象分割掩码。 |
object_state |
list[float] | 7 | 被操作对象在世界坐标系中的位姿 [x, y, z, qw, qx, qy, qz]。 |
state |
list[float] | 39 | 完整环境/本体感知状态向量。 |
action |
list[float] | 4 | 专家动作 [dx, dy, dz, gripper]。 |
reward |
float | 标量 | 时间步 t 的奖励值。 |
terminated |
bool | 标量 | 时间步 t 是否终止。 |
truncated |
bool | 标量 | 时间步 t 是否截断。 |
任务配置(Configurations)
数据集按 Meta-World 任务划分为多个 HuggingFace builder 配置。加载时需使用下述配置名称(不加前缀)。可用任务如下:
push-v3sweep-into-v3door-open-v3handle-pull-v3pick-place-v3peg-insert-side-v3
数据划分(Splits)
每个任务配置均提供以下划分:
| 划分 | 时间步数 |
|---|---|
| train | 1,000,000 |
| test | 100,000 |
掩码的生成方式
- Ground-truth 掩码(
mask,object_mask):源自 MuJoCo 分段渲染,以与 RGB 帧相同的相机位姿按几何体 ID 生成二值掩码。 - SAM 预测掩码(
pred_mask,pred_object_mask):在帧上运行 Segment Anything Model 并提取智能体及被操作对象区域。可能含有分割误差,用于研究对不完美掩码的鲁棒性。
使用与实现
标准加载方式见下方 Python 代码示例。该数据集支持仅加载部分列以节省内存。用户可据实验需求选择:
- 使用 ground-truth 掩码:
["observation_distracted", "mask", "object_mask", ...] - 使用 SAM 预测掩码:
["observation_distracted", "pred_mask", "pred_object_mask", ...]
python from datasets import load_dataset
ds = load_dataset( "tsakman23/visual_masked_distracting_metaworld_sam", name="handle-pull-v3", # 任务配置名 split="train", )
ex = ds[0] ex["observation_distracted"] # PIL.Image, 128x128 RGB(带干扰帧) ex["mask"] # PIL.Image, 128x128 L, ground-truth 智能体掩码 = 255 ex["object_mask"] # PIL.Image, 128x128 L, ground-truth 对象掩码 = 255 ex["pred_mask"] # PIL.Image, 128x128 L, SAM 预测智能体掩码 ex["pred_object_mask"] # PIL.Image, 128x128 L, SAM 预测对象掩码 ex["object_state"] # [x, y, z, qw, qx, qy, qz] ex["state"] # 39 维状态向量 ex["action"] # [dx, dy, dz, gripper]
训练时通常使用 observation_distracted 作为观测量,并移除纯净的 observation 字段。
许可与引用
- 许可证:CC BY 4.0,但其中
observation_distracted帧包含 DAVIS 视频内容,该部分受 DAVIS 研究用途许可限制,商业使用或再分发需审阅 DAVIS 许可。 - 归属:
- Meta-World(MIT License)
- DAVIS 视频背景(非商业研究使用)
- Segment Anything Model(SAM)
- 引用格式:
bibtex @mastersthesis{tsakoumakis2026imlam, title = {Interaction-Masked Latent Action Models for Object-Aware Manipulation under Visual Distractors}, author = {Tsakoumakis, Georgios}, school = {Imperial College London}, year = {2026}, type = {{MSc} thesis} }