DAVIAN-Robotics/RoboLab-BananaInBowl-30cm-pi05rollout-det-260716
收藏资源简介:
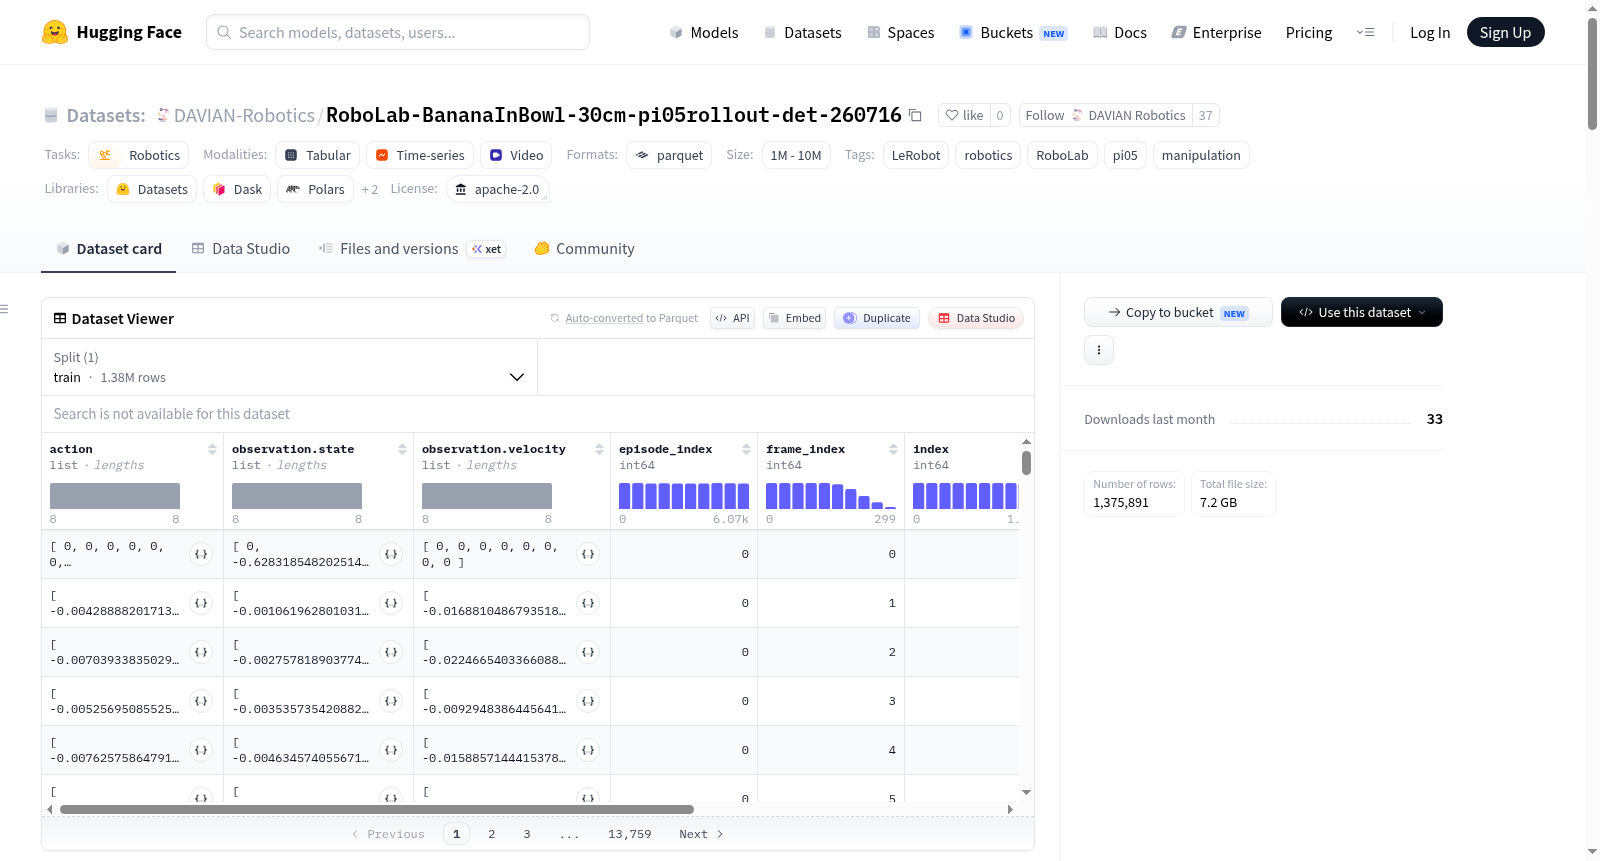
该数据集使用LeRobot创建,包含来自预训练pi0.5策略本身(DAVIAN-Robotics/pi05_droid_jointpos)的rollouts,已转换为LeRobot v3.0格式用于pi0.5 SFT。其存在目的是作为消融实验的数据源基线:一个由速率受限RL策略(relrate k1-c0)构建的数据集移除了pi0.5的SFT崩溃问题。该数据集用于隔离增益是来自RL策略的动作平滑性还是仅来自拥有大量成功演示——收集器、环境和约定相同,仅执行策略不同。数据细节包括:策略为确定性预训练模型,动作块大小15;动作空间记录为绝对关节目标(droid帧,j7偏移-pi/4);夹爪为二进制{0,1}(1表示关闭);成功标准为K-hold settle(success_hold_steps=15),以成功作为截断条件;初始化随机化30cm;成功率约0.325;摄像头包括over_shoulder_left_camera(外部)和wrist_cam;统计信息包含q01/q99分位数;视频经过CFR归一化。比较集为RoboLab-BananaInBowl-30cm-relrate-k1c0-{det,stoch}-gripbin-260716。
This dataset was created using LeRobot. It contains rollouts from the pretrained pi0.5 policy itself (DAVIAN-Robotics/pi05_droid_jointpos), converted to LeRobot v3.0 for pi0.5 SFT. The purpose of this set is to serve as the data-source baseline for an ablation: a dataset built from a rate-limited RL policy (relrate k1-c0) removed pi0.5s SFT collapse. This set isolates whether that gain came from the RL policys action smoothness or simply from having many successful demonstrations — the collector, environment and conventions are identical; only the acting policy differs. Details include: policy is deterministic pretrained model with chunk_size=15; action space recorded as absolute joint targets (droid frame, j7 offset -pi/4); gripper is binary {0,1} (1 = close); success defined by K-hold settle with success_hold_steps=15, success-as-truncation; init randomization at 30cm; yield ~0.325 success per rollout; cameras include over_shoulder_left_camera (exterior) and wrist_cam; stats include q01/q99 quantiles; videos are CFR-normalized. Comparison sets: RoboLab-BananaInBowl-30cm-relrate-k1c0-{det,stoch}-gripbin-260716.