YuvrajSingh9886/jetson-non-reasoning-benchmark-15w
收藏资源简介:
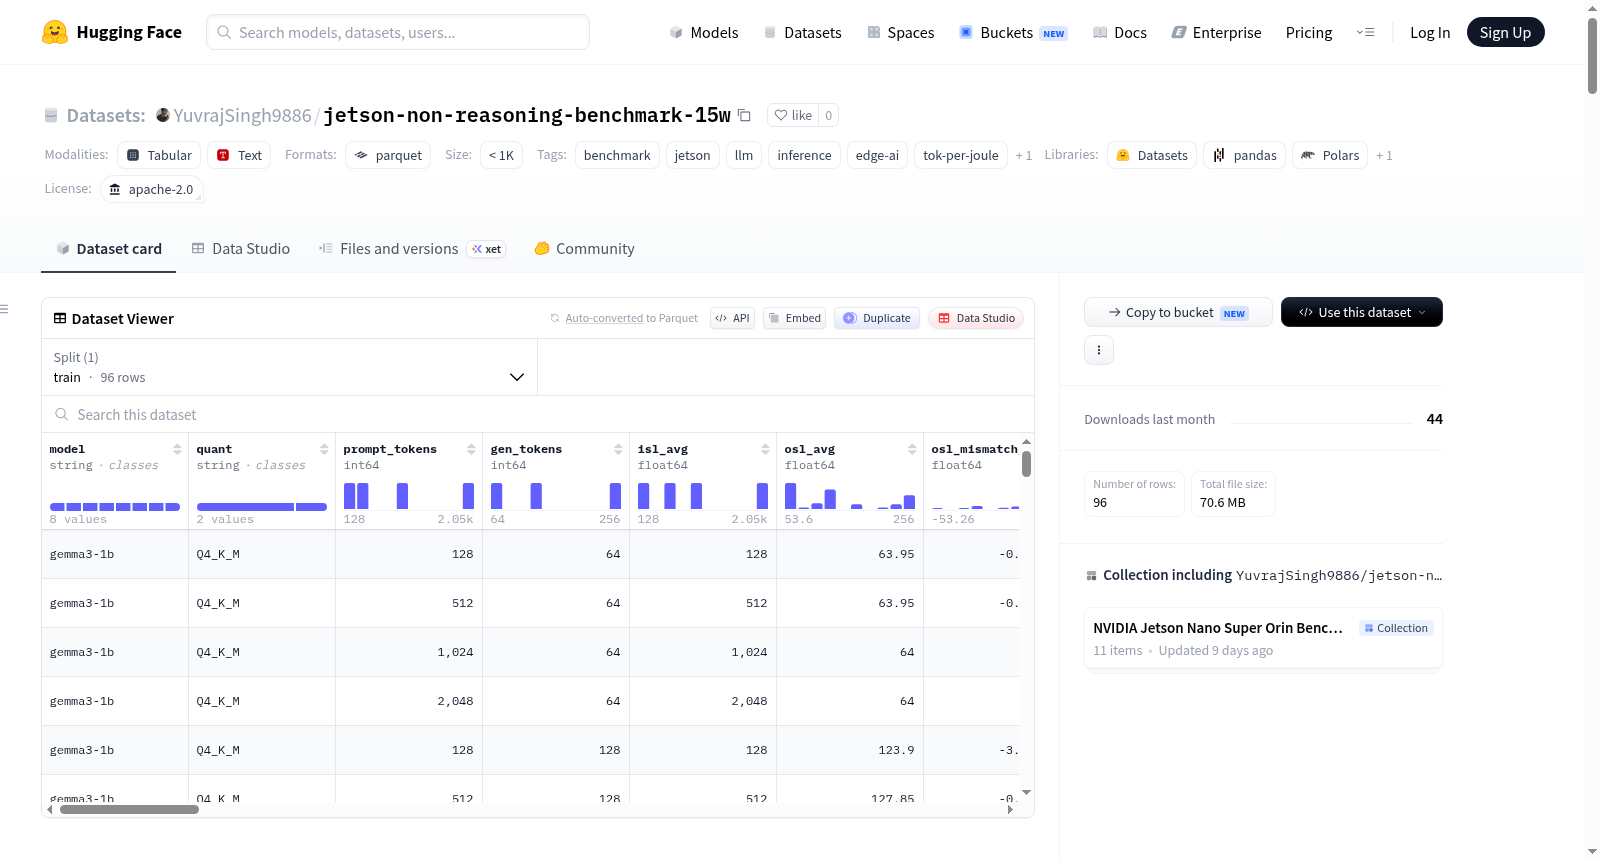
该数据集是一个针对小型大语言模型(LLM)在NVIDIA Jetson Orin Nano 8GB边缘AI设备上的推理性能基准测试集合。测试使用llama.cpp CUDA后端(-ngl 99),并发数为1,覆盖了不同输入token数(128、512、1024、2048)和生成token数(64、128、256)的组合。数据集包含多个模型(如gemma3-1b、lfm2.5-1.2b、llama3.2-1b、qwen2.5-0.5b、qwen3-0.6b等)的量化版本(如Q4_K_M、Q8_0)的详细性能指标,包括首次token时间(TTFT)、token到token延迟(T2T)、输入token延迟(ITL)、token每秒(Tok/s)、请求每秒(Req/s)、端到端token每秒(E2E tok/s)、请求延迟、预填充token每秒、功率消耗(瓦特)以及能效指标(每焦耳token数,Tok/J)。数据用于评估边缘设备上LLM的推理效率和能效,适用于AI推理优化和边缘计算研究。
This dataset is a collection of inference performance benchmark tests for small large language models (LLMs) on the NVIDIA Jetson Orin Nano 8GB edge AI device. The tests use the llama.cpp CUDA backend with the parameter -ngl 99, set the concurrency to 1, and cover combinations of various input token counts (128, 512, 1024, 2048) and output token counts (64, 128, 256). It includes detailed performance metrics for quantized versions of multiple LLMs such as gemma3-1b, lfm2.5-1.2b, llama3.2-1b, qwen2.5-0.5b, qwen3-0.6b and others, with quantization formats like Q4_K_M and Q8_0. The metrics cover Time to First Token (TTFT), token-to-token latency (T2T), input token latency (ITL), tokens per second (Tok/s), requests per second (Req/s), end-to-end tokens per second (E2E tok/s), request latency, prefill tokens per second, power consumption (in watts), and energy efficiency indicator (tokens per joule, Tok/J). This dataset is used to evaluate the inference efficiency and energy efficiency of LLMs on edge devices, and is applicable to research on AI inference optimization and edge computing.